
10 Enterprise AI Project Ideas
Ten enterprise AI project ideas with October 2026 stacks, build steps, risks and a build-or-buy call for each, plus why AI projects stall in production.
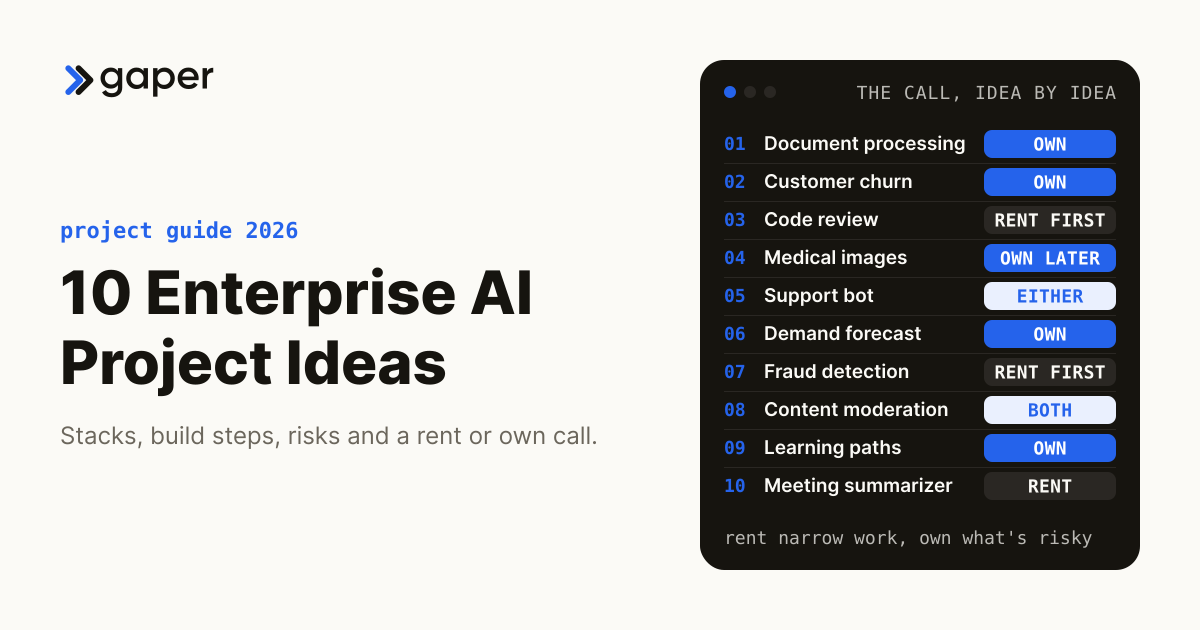
The enterprise AI projects worth building in 2026 fix a problem you already measure, run on data you can test against, and have a named owner. Here are ten, each with a stack checked in October 2026, a build sequence, the main risks and a build-or-buy call.
Pick your path first.
- Ideas to learn on: the support bot (idea 5) and meeting summarizer (idea 10) are the easiest here, or try our 25 machine learning project ideas for beginners.
- A project your firm should actually build: read what to build first and why AI projects stall.
Definition: AI-native implementation partner. An AI-native implementation partner is a firm that builds, deploys and supervises production AI agents inside your existing systems, then hands over the code, prompts and runbook so you own what runs. It ships working agents, not advice or billable hours. Gaper is the AI-native implementation partner that deploys supervised AI agents you own. Read what an AI-native implementation partner does, and when to skip one.
Updated October 2026: models, tools and statistics rechecked at their sources.
TL;DR: The AI Projects Getting Built This Year (And Why)
The core difference between 2024 and 2026: AI is moving from proof of concept to production, unevenly: most companies use it, fewer than half have scaled it, and fewer still see it in earnings. The 10 AI project ideas in this guide aren't theoretical: each comes with a current stack, a build sequence and the risks that decide whether it survives production.
Key stats to know:
- Nearly nine in ten respondents report regular AI use in at least one business function, and 44% say AI is scaling across the enterprise, but only 37% attribute any EBIT impact to AI, about the same as the 39% in the 2025 survey (McKinsey, The state of AI in 2026: On the road to ROI, 25 August 2026, 1,719 respondents).
- Gartner expects more than 40% of agentic AI projects to be scrapped by the end of 2027, citing rising costs, unclear value and weak risk controls (Gartner prediction, June 2025).
- Only 7% say their organization's data is completely ready for AI, and 73% found preparing data for AI challenging (Cloudera-sponsored HBR Analytic Services survey, March 2026, 230+ respondents).
- External partnerships with customized tools (bought or co-developed with vendors) reached deployment about 67% of the time against about 33% for internal builds, self-reported by a preliminary sample of 52 organizations; treat it as directional (MIT NANDA, The GenAI Divide, July 2025).
Jump To:
- What Makes a Good AI Project in 2026
- The 10 AI Project Ideas
- Comparison Table: All 10 Projects at a Glance
- What Should Your Firm Build First
- How to Scope and Build AI Projects
- Why AI Projects Stall Before Production
- How Gaper Builds AI Projects
- Questions to Settle Before You Build
What Makes a Good AI Project in 2026?
A good AI project fixes a problem you already measure, has real examples to test against, has a named owner who stays after launch, and can run with a person approving anything risky. If you cannot say which number should move and who answers for it, the project is not ready to build.
Not every problem needs machine learning. Two more tests separate the projects that actually ship in 2026: the success metric is objective, not subjective, and the run cost is priced before the build. Timelines depend on the integrations and approvals the workflow needs, so they are scoped up front.
The Shift from Demos to Production AI
In 2024, the question was: "Can we build this AI project?" Now it's: "Can we maintain this AI project in production for 18 months without it breaking when the underlying model vendor changes their API?" That is not hypothetical: OpenAI set 23 October 2026 as the shutdown date for GPT-4 Turbo and the May 2024 GPT-4o snapshot (OpenAI), and Anthropic set 30 November 2026 for Claude Sonnet 4.5 (Anthropic). This shift changes everything about project selection. You need to think about retraining pipelines or a rerunnable evaluation set, fallback logic, monitoring, and cost. The projects in this guide all assume you're planning for production from day one.
Criteria for Choosing Your Next AI Project
Use these three filters. First, the data question: do you own historical examples of the decision you're trying to automate, with the right answer recorded? If not, you're not ready (or you need to partner with a vendor who has that data). Second, the economics question: is the problem costing you clearly more in labor, fraud losses, or missed revenue than the build plus the run cost? If not, the ROI won't justify the engineering team. Third, the ownership question: do you have a dedicated owner (a Chief AI Officer, VP of Product, VP of Engineering, operations lead or partner) who will stay with this project well past launch? AI projects fail when leadership changes hands every quarter.
The 10 AI Project Ideas
Difficulty, team size and the data starting points in the comparison table are editorial estimates for an in-house build, not quotes or minimums. Model names are from the OpenAI, Anthropic and Google model pages, October 2026.
1. Intelligent Document Processing Pipeline
- Difficulty: Intermediate (6/10)
- Team size: 2 engineers, 1 data person
- Tech stack: Python, LangChain, a high-volume model (Claude Haiku 5.5, GPT-6 Luna or Gemini 3.5 Flash-Lite) with a larger one for hard pages, Tesseract OCR, Unstructured.io, PostgreSQL, FastAPI
- Maintenance burden: Low to Moderate
- Main cost driver: model calls per page, plus OCR at volume
Why it matters: Invoices, claims, bank statements and contracts still arrive as PDFs and scans, and someone retypes them into a system of record. Insurance, healthcare, legal, financial services and accounting all run on this work, which is why document processing is often the first AI project with a clean before-and-after number.
What you're building: A system that ingests PDFs, images, and scanned documents, extracts structured data from them (names, dates, amounts, account numbers), normalizes that data, and routes documents to the right downstream systems. The workflow looks like this: Document comes in via S3 upload or API. Tesseract OCR handles scanned images if needed (current models can also read a page image directly). LangChain orchestrates a model call that extracts fields using few-shot prompting (you show the model 3-5 examples and it generalizes). Extracted data goes into PostgreSQL. A FastAPI endpoint makes the whole system callable from existing systems.
Real tech example: Unstructured.io is an open source library built for this, with a commercial platform alongside. You'd use LangChain as the orchestration layer, a current model as the extraction engine, and Python for the glue code. For large-scale deployments, add a dedicated OCR service like Amazon Textract instead of Tesseract.
Build sequence:
- Step 1: Set up OCR pipeline, test with 100 sample documents, measure baseline accuracy
- Step 2: Build the LangChain extraction pipeline, create prompt templates
- Step 3: Database schema design, integration with your core systems, error handling
- Step 4: Testing at scale, monitoring setup, fallback logic for extractions that fail validation
Risks and mitigation: The biggest risk is prompt brittleness: the model handles common layouts, then fails on edge cases. Language models do not return calibrated confidence, so drive the human-in-the-loop queue with checks: totals that do not add up, dates out of range, blank required fields. Keep a fast feedback loop to improve your prompt templates. Your first 500 documents might need manual review. Plan for that.
Reference build: illustrative, not a client engagement. A vendor invoice agent matches invoices to purchase orders and drafts entries. Ownership Map: matching Automated, entries Agent-drafted and human-approved, payment approval Human-owned. Metric to track: invoices per 100 a reviewer corrects.
Sitting on a document backlog? Scope a document-processing agent in a free 30-minute AI assessment.
2. Predictive Customer Churn Model
- Difficulty: Intermediate (6/10)
- Team size: 2 data engineers, 1 ML engineer
- Tech stack: Python, XGBoost, LightGBM, Scikit-learn, Dagster (orchestration), Snowflake, dbt, Plotly
- Maintenance burden: Moderate
- Main cost driver: warehouse compute for features and retraining
Why it matters: Churn is a revenue line you already report, so the business case is arithmetic. On $10 million of annual recurring revenue, each percentage point of churn you prevent keeps about $100,000 a year. The model's job is to tell your success team which accounts to call first, and why.
What you're building: A system that predicts which customers will churn in the next 30, 60, or 90 days. You feed it historical data (account age, MRR, feature usage, support tickets, login frequency, invoice history), and it outputs a probability score for each customer. Sales and success teams use that score to decide who gets outreach. The ML model is usually XGBoost or LightGBM for tabular data like this. They're fast, explainable with SHAP values, and require far less data than deep learning.
Real tech example: Databricks publishes a churn prediction solution accelerator. You'd pull account data from your billing system (Stripe, Zuora, or Salesforce) into Snowflake, run feature engineering in dbt, train XGBoost in Python, and set up Dagster to retrain weekly. A Plotly dashboard shows which customers are at risk and why.
Build sequence:
- Step 1: Define churn (most teams get this wrong; you need to decide if 90 days of zero activity means churn, or 30 days without paying). Extract 2-3 years of account history. Start with 10-15 features.
- Step 2: Feature engineering. Build features like "did this customer use feature X in week 4?" and "how many support tickets this month vs. last month?" Most of the value comes from this step.
- Step 3: Train XGBoost, validate on the most recent stretch of history the model has not seen (for example the last 20% of the timeline). Compare its AUC with the rule your team uses today; a model that cannot beat that rule is not ready.
- Step 4: Deploy prediction pipeline, set up retraining, integrate with Salesforce or your CRM so the churn score shows up next to each account.
Risks and mitigation: The biggest risk is creating a feedback loop that makes things worse. If you only reach out to customers the model says will churn, and your outreach works, then your model becomes trained on "successful retention" not "actual churn." You need a control group. Take 20% of at-risk customers and don't reach out to them. Measure the difference. Also, your churn definition will probably change. Plan to retrain the model monthly for the first three months.
Reference build: illustrative, not a client engagement. An account-health agent briefs the owner of each flagged account and drafts an outreach email. Ownership Map: scoring and briefing Automated, the email Agent-drafted and human-approved, discounts Human-owned. Metric to track: retention in the contacted group against the control group.
3. AI-Powered Code Review Assistant
- Difficulty: Intermediate to Advanced (7/10)
- Team size: 2-3 engineers, 1 ML engineer
- Tech stack: Python, a current coding model (Claude Sonnet 5.5 for routine diffs, Claude Opus 5.5 or GPT-6 Astra for hard ones), GitHub API, LangChain, PostgreSQL, FastAPI
- Maintenance burden: Moderate to High
- Main cost driver: model tokens per pull request
Why it matters: Review is where security issues and missing tests are cheapest to catch, and where senior engineers' time goes. An assistant that comments first takes the mechanical checks off that queue. GitHub made Copilot code review generally available to paid Copilot subscribers in April 2025, so build your own only when you need your own rules, data handling or models.
What you're building: A system that runs every time someone opens a PR. It clones the repo, runs the diff, feeds the changed code to the model with prompts asking for: security issues, performance problems, style violations, missing tests, and architectural inconsistencies. It posts inline comments on the PR. Developers accept or dismiss each comment, and you use their responses to tune the prompts so it stops making low-value comments.
Real tech example: You'd build your own version by hooking into GitHub's webhook API, sending diffs to the model, and using the GitHub API to post comments. LangChain handles the prompt logic. Store all feedback in PostgreSQL so you can measure what comments engineers actually acted on.
Build sequence:
- Step 1: Set up GitHub webhook integration, get familiar with the GitHub API, write code to extract and format diffs
- Step 2: Create prompt templates for the 5 categories above. Test on your last 100 PRs. How many issues did it catch? How many were false positives?
- Step 3: Build the feedback loop. Store which comments engineers accepted vs. dismissed. Refine your prompt templates based on the data.
- Step 4: Deploy to your team, set up cost controls (per-token pricing can add up fast), create a dashboard showing what kinds of issues the system catches most often
Risks and mitigation: The biggest risk is that engineers ignore your bot. If the first 10 comments are wrong, they'll mute the bot and never look at it again. Weight precision over recall at first: better to miss half the issues with comments engineers trust than to flag most of them with comments they learn to ignore. Also, API costs can balloon. At Claude Sonnet 5.5's list price ($2 per million input tokens, $10 per million output, Anthropic, October 2026), a review reading 20,000 tokens and writing 1,000 costs about 5 cents, or about 10 cents on Claude Opus 5.5 at $4 and $20. Thinking tokens bill as output, so price it on real PRs, multiply by your daily volume and budget for it.
4. Medical Image Classification System
- Difficulty: Advanced (8/10)
- Team size: 2-3 ML engineers, 1 clinical advisor
- Tech stack: Python, PyTorch, MONAI (Medical Open Network for AI), TensorFlow, Hugging Face, FastAPI, DICOM
- Maintenance burden: High
- Main cost driver: regulatory work and clinical validation, then compliant GPU hosting
Why it matters: Imaging is where most authorized medical AI already sits. Of the 1,614 AI-enabled devices on the FDA's list (content current as of 4 September 2026), 1,230, about 76%, name radiology as the lead review panel (FDA). The category is established, and the bar to ship is regulatory authorization, not a demo. The real value is accuracy: catching findings early and putting urgent studies first.
What you're building: A system that ingests DICOM files (the medical image standard), classifies them (presence of abnormality, type of abnormality, severity), and flags high-confidence issues for immediate radiologist review. You're not replacing radiologists. You're triaging and alerting them.
Real tech example: MONAI is the open-source, PyTorch-based framework for healthcare imaging. Teams typically start from pretrained weights (from its Model Zoo, Hugging Face or a general image model), then fine-tune on their hospital's own labelled data.
Build sequence:
- Step 1: Get HIPAA compliant infrastructure set up. This is non-negotiable in healthcare. Work with your IT/security team. Get access to labelled imaging data covering every finding you want to detect.
- Step 2: Build data pipeline. DICOM files are complex. Learn the format. Standardize image sizes, orientations, and intensities.
- Step 3: Model development. Start with transfer learning (fine-tune a pre-trained model). Compare PyTorch and TensorFlow. Train on your data. Measure accuracy, sensitivity, specificity.
- Step 4: Clinical validation. Get a radiologist to review the model's predictions on 200 new scans the model hasn't seen. How accurate is it? Get IRB approval if you're conducting research. Deploy with human-in-the-loop.
Risks and mitigation: Healthcare is heavily regulated. Under the FDA's clinical decision support guidance of 29 January 2026, software that analyzes a medical image remains a medical device (FDA), so a triage model typically needs FDA authorization, usually 510(k) clearance. You also need to handle data privacy carefully (de-identify DICOM files, encrypt in transit). The biggest technical risk is that your model works great on your training data but fails on new data from a different scanner brand or different hospital. Build a monitoring system that catches performance degradation. Also, medical models are black boxes. Doctors won't trust a system they can't understand. Use attention maps or gradient-based visualizations to show clinicians what the model is looking at.
5. Conversational AI Customer Support Bot
- Difficulty: Beginner to Intermediate (5/10)
- Team size: 1-2 engineers, 1 product person
- Tech stack: Python, LangChain, a current model (GPT-6.1 Sol, Claude Sonnet 5.5 or Gemini 3.8 Flash), Redis (for conversation memory), FastAPI, Twilio or custom chat widget
- Maintenance burden: Moderate
- Main cost driver: model calls per conversation, or a per-resolution fee if you buy
Why it matters: Klarna shows both the upside and the trap. In February 2024 it said its assistant did the work of 700 representatives (company-reported); by May 2025 it was recruiting people for customer service again, and its chief executive said the cost focus had meant lower quality (CX Dive, May 2025). Let the bot answer routine questions and route the rest to people.
What you're building: A chatbot that answers customer questions without human intervention. It uses retrieval-augmented generation (RAG): it pulls your knowledge base (help articles, FAQ, documentation), embeds that into vector form, finds relevant articles for the user's question, adds those to the prompt, and sends the whole thing to the model. The model generates an answer grounded in your actual documentation, which reduces hallucination but does not remove it. If the bot cannot find a good source, it hands off to a human agent.
Real tech example: Fin (the AI agent in Intercom's helpdesk; the company renamed itself Fin in May 2026), Zendesk and Front all sell this now; Intercom lists its helpdesk with Fin at $29 per seat a month plus $0.99 per outcome (October 2026). You'd build your own version with LangChain (handles RAG), a model API, and your knowledge base (stored as embeddings in Pinecone or a vector database). Redis is great for conversation memory (so the bot remembers the customer said "I paid $100" 5 messages ago); Redis 8 folded the old Redis Stack into Redis Open Source.
Build sequence:
- Step 1: Set up LangChain, connect a model API, load your knowledge base (help articles), create embeddings
- Step 2: Build the RAG pipeline. Test with 50 common questions from your support team. How often does it find the right article?
- Step 3: Deploy to a test group of customers. Set up conversation logging and monitoring. Measure: how many tickets did it resolve? How many escalated to humans?
- Step 4: Iterate based on data. Which types of questions does it handle well? Which does it struggle with? Retune your prompts.
Risks and mitigation: The biggest risk is hallucination: the bot makes up answers that sound plausible but are wrong. Mitigate this by always citing sources ("This is from our [Help Article Name]") and by escalation rules you have tested: no strong source found, a refund or account change, or a frustrated customer goes to a person. Also, expect customer backlash from people who hate talking to bots. Build a fast path to escalation and monitor escalation rates; a sudden rise means the knowledge base or routing has drifted.
Reference build: illustrative, not a client engagement. A client inbox agent for a professional services firm answers routine status questions with a citation. Ownership Map: routine answers Automated with sampled review, fee and deadline replies Agent-drafted and human-approved, advice Human-owned. Metric to track: answers the reviewer corrects.
6. Supply Chain Demand Forecasting
- Difficulty: Intermediate to Advanced (7/10)
- Team size: 2-3 data engineers, 1 ML engineer, 1 business analyst
- Tech stack: Python, Prophet (Meta), statsforecast, ARIMA, XGBoost, Pandas, DuckDB, Looker or Power BI
- Maintenance burden: High
- Main cost driver: data engineering to keep sales, price and promotion feeds clean
Why it matters: Forecast error shows up twice in your P&L: as excess inventory you pay to hold, and as stockouts that lose sales. That makes forecasting easy to price, because you can compare last year's forecast error, product by product, with what a model does on the same history. For fast-moving consumer goods, pharmaceuticals, and semiconductors, where inventory is expensive, it belongs near the top of the list.
What you're building: A system that forecasts demand for each product in each region for the next 90 days. You feed it historical sales data (at least 2 years), seasonality information (what months do you sell more?), and external signals (price changes, competitor activity, holidays, weather for produce, etc.). The model outputs a point forecast ("you'll sell 1,000 units") and a prediction interval ("with 80% confidence, you'll sell 800-1,200 units"). Supply chain teams use this to decide how much to manufacture or order.
Real tech example: Prophet (from Meta) is a common starting point for business time series with seasonality. It has been in maintenance mode since version 1.4.0, with no new features planned, so treat it as a baseline rather than the gold standard. You'd start with Prophet, then layer on XGBoost to capture external signals. Combine the two for best results.
Build sequence:
- Step 1: Data assembly. Pull 2-3 years of sales data from your ERP or data warehouse. Get granular (by product, by region, by channel if possible). Engineer external features: holidays, price points, competitor prices if available, promotions.
- Step 2: Model development. Start with Prophet for each product. Measure accuracy on a holdout test set (usually the last 3 months of data). Compare its MAPE (Mean Absolute Percentage Error) with a seasonal naive forecast and your planners' current forecast; the model has to beat both.
- Step 3: Add XGBoost as a second model. See if it improves accuracy when you combine it with Prophet. For some products Prophet dominates, for others XGBoost is better. Build an ensemble.
- Step 4: Deploy prediction pipeline. Set up automated retraining (monthly or quarterly). Connect to your ERP or planning system. Create a dashboard showing forecast accuracy over time (did we get the forecast right?).
Risks and mitigation: The biggest risk is that your forecast is accurate but your supply chain ignores it. You'll build something perfect and operations will override it because they "have a gut feeling." Get buy-in from supply chain and procurement before you start. Also, external events (pandemics, wars, tariffs) break time series models, and your history may not contain the next disruption. Monitor forecast accuracy religiously and trigger a full retrain if accuracy drops below a threshold.
7. Real-Time Fraud Detection System
- Difficulty: Advanced (8/10)
- Team size: 2-3 ML engineers, 1 data engineer, 1 systems engineer
- Tech stack: Python, PySpark, Kafka, Feature store (Databricks, which absorbed Tecton after announcing the deal in August 2025, or open-source Feast), XGBoost, Redis, FastAPI
- Maintenance burden: Very High
- Main cost driver: streaming infrastructure and real-time feature serving
Why it matters: For fintech and payment companies, fraud is a direct loss line. But the real cost of fraud isn't just the stolen money; it's chargebacks, regulatory scrutiny, and good customers who leave after a false decline. A good fraud system is table stakes for any payment processor.
What you're building: A system that makes a fraud/no-fraud decision on every transaction in milliseconds. It ingests transaction data (amount, merchant, customer history, device fingerprint, location, etc.), runs hundreds of features through an XGBoost model, and returns a risk score. High-risk transactions get declined or sent to a second authentication layer. Low-risk transactions go through instantly.
Real tech example: Stripe Radar, Square Risk Manager and PayPal's fraud tools are the off-the-shelf versions; Stripe says Radar scores transactions in real time with AI (Stripe docs). You'd build your own with Kafka (for event streaming), Spark (for feature computation), a feature store to keep features in sync across training and serving (such as Databricks', which now includes Tecton, or open-source Feast), XGBoost (the model), and Redis (for low-latency serving), inside your payment flow's latency budget.
Build sequence:
- Step 1: Set up infrastructure. Kafka for event streaming, Spark for processing. Start getting transactions into your system and logging decision outcomes.
- Step 2: Feature engineering. Build features about each customer, device, merchant, and transaction type.
- Step 3: Model training. Label historical transactions (fraud or legitimate). Train XGBoost. Set the decline threshold from what each error costs: a missed fraud costs the loss and the chargeback, a false decline costs the sale and maybe the customer.
- Step 4: Deploy in shadow mode first. Make predictions but don't use them to decline transactions. Log both your predictions and the ground truth. Once shadow results hold up across normal and peak periods, flip the switch and start declining transactions.
Risks and mitigation: The biggest risk is false positives. Decline one legitimate transaction and the customer might move their business to a competitor, so be conservative. Also, fraudsters adapt: a model that performs well today can degrade within months. Monitor performance constantly. Retrain weekly. Also, you need to be able to explain decisions. If the same models decide credit, Regulation B requires specific reasons for adverse action (12 CFR 1002.9), though a point-of-sale decline generally is not one; in the EU, GDPR Article 22 limits solely automated decisions with significant effects. This is information, not legal advice. Use SHAP (SHapley Additive exPlanations) to generate explanations.
Reference build: illustrative, not a client engagement. A fraud-case triage agent turns each transaction the model routes to review into a one-page case summary. Ownership Map: the summary is Automated; the decision to block or refund is Human-owned. Metric to track: cases an analyst reopens.
8. AI Content Moderation Platform
- Difficulty: Intermediate to Advanced (7/10)
- Team size: 2-3 ML engineers, 1 content strategist
- Tech stack: Python, Hugging Face Transformers, OpenAI moderation API, LangChain, Datadog (monitoring), PostgreSQL, FastAPI
- Maintenance burden: High
- Main cost driver: human review time on flagged and appealed items
Why it matters: Any platform that hosts posts, comments or uploads needs moderation that scales past what a review team can read and stays consistent from one reviewer to the next. In the EU, each removal also needs a statement of reasons saying, where applicable, whether automated means were used (Digital Services Act, Article 17). Pre-sorting lets reviewers focus on borderline cases.
What you're building: A system that classifies content into categories: spam, hate speech, violence, sexual content, misinformation, and safe. For each category, you output a probability score. A FastAPI endpoint receives a piece of content (text, image, video frame), runs it through models, and returns scores. Your moderation dashboard shows flagged content to human reviewers in priority order (highest risk first).
Real tech example: Hugging Face has pre-trained models for hate speech detection, toxicity detection, and others. For a free baseline, OpenAI's omni-moderation-latest model flags text for categories such as harassment and hate, and text and images for self-harm, sexual content and violence (OpenAI moderation guide). You'd combine multiple models (text model + image model) for multimodal content. LangChain can orchestrate the pipeline.
Build sequence:
- Step 1: Understand your company's content policy in detail. What violates policy? What's borderline? Get 100 examples of each from your content team. Label them.
- Step 2: Evaluate pre-trained models. Test a Hugging Face toxicity model and the moderation API on your examples. How accurate are they out of the box? Which categories are they good at?
- Step 3: Fine-tune. Use your labelled examples to fine-tune a model on your specific policy. Compare models: Hugging Face BERT vs. RoBERTa vs. OpenAI API. Which is fastest and most accurate?
- Step 4: Deploy with human review. Route all flagged content to human moderators. Log their decisions. Use that to measure model performance and retrain quarterly.
Risks and mitigation: The biggest risk is bias. Content moderation models can flag some communities at higher rates than others: in Sap et al., ACL 2019, tweets in African American English were up to twice as likely to be labelled offensive. A model might also flag discussion of civil rights as "hate speech" because historical training data associated those words with hate. Use demographic parity and equalized odds metrics to catch bias. Also, get cultural context. What's normal in one country might be offensive in another. You need regional models or at least the ability to tune thresholds per region.
9. Personalized Learning Path Generator
- Difficulty: Intermediate (6/10)
- Team size: 2 ML engineers, 1 product manager
- Tech stack: Python, LangChain, a model API, Embeddings (Sentence Transformers), Pinecone or Weaviate, FastAPI, React
- Maintenance burden: Moderate
- Main cost driver: embedding and model calls as the catalog grows
Why it matters: One-size-fits-all education is inefficient: it repeats what learners know and loses them on what they are not ready for. Enterprise training platforms measure completion and time to competency; online learning platforms measure engagement and churn. Both are already tracked, so an A/B test gives a clean answer.
What you're building: A system that recommends the next lesson, exercise, or resource based on: what the student has already completed, their proficiency level (measured by quiz scores), their learning style preference (video vs. text vs. interactive), and what similar students did next. It uses collaborative filtering (if 100 students with similar profiles took course X next, recommend course X) and content-based filtering (if you're good at math and bad at writing, recommend a math course, not writing).
Real tech example: You'd use embeddings to represent students and courses in a vector space, then find nearest neighbors. Pinecone makes this fast. LangChain can orchestrate the recommendation logic. FastAPI serves it.
Build sequence:
- Step 1: Data assembly. Get historical data on students (what courses did they take, in what order?), their quiz scores (proficiency), their demographics, and their feedback (which courses did they love vs. hate?).
- Step 2: Feature engineering. Create student profiles (what skills do they have?) and course profiles (what skills does this course teach?). Embed both into vector space.
- Step 3: Build recommendation engine. Collaborative filtering: find students like this one, see what they took next. Content-based filtering: find courses similar to ones they took. Combine both.
- Step 4: Deploy A/B test. Half the platform gets personalized recommendations, half gets the old algorithm. Measure: do personalized students complete more courses? Do they spend more time learning?
Risks and mitigation: The biggest risk is that you recommend things at the wrong level of difficulty. If you recommend something too hard, students get discouraged. Too easy, they get bored. Use Bloom's taxonomy or a similar framework to think about difficulty levels. Also, avoid feedback loops where you only recommend things students already like, making them less likely to grow.
10. Autonomous Meeting Summarizer
- Difficulty: Beginner to Intermediate (5/10)
- Team size: 1-2 engineers
- Tech stack: Python, a speech-to-text model (OpenAI gpt-transcribe, or open-source Whisper you host), LangChain, a current model for summaries, PostgreSQL, Slack/Calendar API
- Maintenance burden: Low
- Main cost driver: transcription minutes
Why it matters: Meetings produce decisions and action items that often live only in someone's notes. A summary that lands in the right channel, with owners and due dates, saves the follow-up meeting. It is also the clearest case for renting: products already do this well, so build only when transcripts must stay in your environment or feed your own systems.
What you're building: A system that joins Zoom/Google Meet calls (or receives audio files), transcribes them, summarizes them with a current model, and posts the summary to Slack or your notes app. It also extracts action items and due dates. The summary includes what was decided, who said what, and what happens next.
Real tech example: Gong, Fireflies, and Otter all do this. You'd build it with a transcription model, LangChain for orchestration, and a current model for summarization. OpenAI now recommends gpt-transcribe and set 26 February 2027 as the removal date for its whisper-1 API model (OpenAI), while open-source Whisper can still be self-hosted. For extraction, you'd use prompting with structured outputs.
Build sequence:
- Step 1: Set up transcription, get test audio files, transcribe a few meetings, measure accuracy
- Step 2: Build LLM pipeline. Prompt the model to summarize the transcript. Then prompt it again to extract action items and decisions.
- Step 3: Integrate with Slack and your calendar. Automatically post summaries to the right Slack channel.
- Step 4: Measure value. Ask 50 employees: did the summary help you? Would you have needed to rewatch the meeting? How much time did you save?
Risks and mitigation: The biggest risk is transcription errors. Even a low error rate leaves mistakes across an hour of audio, and they cluster on names, product terms and numbers. It might transcribe a product name wrong or mishear a decision. Always include a link back to the full recording and flag low-confidence segments. Also, some people feel surveilled when you're recording and transcribing everything. Be transparent about the system, check recording-consent rules, and let people opt out of specific meetings.
Comparison Table: All 10 Projects at a Glance
| Project | Difficulty | Team Size | Maintenance | Main Cost Driver | First Metric to Watch | Data Requirements |
|---|---|---|---|---|---|---|
| Document Processing | 6/10 | 3 people | Low to moderate | Model calls per page | Fields corrected per 100 documents | Real documents, bad scans included |
| Customer Churn | 6/10 | 3 people | Moderate | Warehouse compute | Retention vs. control group | 2+ years history |
| Code Review | 7/10 | 3 people | Moderate to high | Tokens per PR | Comments accepted without edits | 100+ PRs |
| Medical Images | 8/10 | 3 people | High | Regulatory validation | Sensitivity and specificity | Labelled studies per finding |
| Support Bot | 5/10 | 2 people | Moderate | Calls per conversation | Answers corrected | 500+ tickets |
| Demand Forecast | 7/10 | 4 people | High | Data engineering | Error vs. seasonal naive forecast | 2+ years data |
| Fraud Detection | 8/10 | 4 people | Very high | Streaming and serving | False declines in shadow mode | Millions of txns |
| Content Moderation | 7/10 | 3 people | High | Human review time | Reviewer overturn rate | 1,000+ examples |
| Learning Paths | 6/10 | 3 people | Moderate | Embedding calls | Completion in an A/B test | 10K+ students |
| Meeting Summarizer | 5/10 | 2 people | Low | Transcription minutes | Rewatches avoided | 100+ meetings |
What Should Your Firm Build First?
Build first the idea that moves a number you already report, runs on data you control and keeps a person approving anything risky: for most firms, document processing, a support agent or churn scoring. Rent narrow, common ones such as meeting notes, and hold regulated ones until an owner is named.
The table applies the Rent-vs-Own test, which AI agents vs SaaS tools explains: rent a point tool for narrow, common work, own a supervised agent when it touches systems of record, data or risk.
| Idea | Call | The deciding test |
|---|---|---|
| Document processing | Own | Do the documents feed a system of record? |
| Customer churn | Own | Will a named team act on the scores? |
| Code review | Rent first | Does Copilot code review cover your rules? |
| Medical images | Own, with an FDA plan, not as a first project | Do you have clinical partners and an FDA route? |
| Support bot | Own or rent | Do answers depend on your own systems? |
| Demand forecast | Own | Will planners use the forecast? |
| Fraud detection | Rent first | Is payments or lending your business? |
| Content moderation | Rent a baseline, own the policy | Does your policy differ from generic categories? |
| Learning paths | Own | Do you have learner history? |
| Meeting summarizer | Rent | Must transcripts stay in house? |
How to Scope and Build AI Projects
Data Quality Is Always the Bottleneck
Every AI team has the same conversation: "We have lots of data, but not in a format we can use." You inherit data schemas built 10 years ago by people who don't work there anymore. You have 90 days of clean data and 5 years of corrupted data. You have customer IDs that change meaning halfway through the dataset. You spend three months building a data pipeline and zero months on machine learning. This is normal.
In a Cloudera-sponsored Harvard Business Review Analytic Services survey of more than 230 people (fielded October 2025, published March 2026), 73% said preparing data for AI has been challenging, and 7% called their data completely ready (Cloudera). Plan for this. When you estimate a project, put most of the effort against data work, not modeling.
Model Accuracy vs. Production Reliability
A model that scores well on your test set can do much worse in production. Why? Because your test set doesn't represent production data. Your training data has a 60/40 male/female split but production is 80/20. Your training data has 2% fraud, but production has 0.5% (or 5%, depending on the season). Your training data has products from 2025, but production gets new products launched in 2026.
The fix is constant monitoring. Log every prediction and the ground truth (once you know it). If accuracy drops below a threshold, retrain automatically. For some models, you retrain daily. For others, monthly. For fraud detection, you might retrain weekly because fraudster tactics change fast. For language-model builds, the equivalent is an evaluation set you rerun on every prompt or model change.
The MLOps Gap
There's a huge gap between "I trained a model on my laptop" and "this model serves 1,000 requests per second in production, auto-retrains when accuracy drops, and I can roll back if something breaks." This gap is called MLOps (machine learning operations) and it's where most AI projects fail.
You need: a training pipeline (reproducible, versioned, logged), a model registry (tracking which models are in production), serving infrastructure (APIs, low latency), monitoring (accuracy, latency, cost), and rollback mechanisms. Google engineers made the case in Hidden Technical Debt in Machine Learning Systems (NIPS 2015): quick model wins hide large ongoing maintenance costs in the system around them.
The good news is the tooling has gotten much better. MLflow is open source and solid. Databricks, Weights and Biases, and others have commercial offerings that make MLOps easier. Budget for MLOps.
Weighing an in-house team for this? Compare the salaries with a scoped build in the AI engineer salary calculator.
Why Do AI Projects Stall Before Production?
Many stall for reasons beyond the model: run costs nobody priced, no agreed metric, and weak risk controls once the system acts. Gartner predicted in June 2025 that over 40% of agentic AI projects will be canceled by the end of 2027 over costs, unclear value or inadequate risk controls.
Gartner adds that current models lack the maturity to reach complex goals on their own. Among the ten ideas above, each driver has a familiar form:
- Cost: fraud detection can stall when streaming and real-time serving were never priced against the losses prevented. About one in five respondents to McKinsey's August 2026 State of AI survey said operating costs, such as token fees, limit their organization's AI use.
- Value: churn scoring can stall when nobody owns the outreach. Agree the metric, today's baseline and who acts before any code.
- Data: document processing can stall on bad scans and odd layouts. Test on real documents first.
- Control: medical imaging can stall on regulatory authorization. For any idea, place each step on the Gaper Ownership Map (Automated, Agent-drafted and human-approved, or Human-owned) and name the approver.
- Ownership: Gartner predicted in September 2026 that by 2028, 70% of enterprises will abandon agentic AI built by embedded vendor engineers, unable to evolve it on their own, and advised settling IP ownership, knowledge transfer and an exit plan from day one. The Hand over step below exists for that risk: you receive the code, prompts, evaluation set and runbook, so your team can operate it without us.

The general argument is in why AI projects stall. Integration is where these gaps surface first, so check your systems with the MCP readiness assessment.
How Gaper Builds AI Projects
Every Gaper engagement runs the same five steps, in order, on one workflow at a time. The steps are fixed. How long each one takes depends on the integrations and approvals the workflow needs, so it is scoped up front from your real process rather than promised in advance.
- Assess: a free AI assessment to find the workflow with the most leverage and the one metric that proves it worked, and to say plainly if none is worth building yet.
- Scope: place every step on the Ownership Map and make the Rent-vs-Own call.
- Build: a Gaper engineer embeds with your team, forward-deployed, and builds the agent in your repo and your cloud, with evals, guardrails, connectors to your systems and human approval on risky actions.
- Supervise: the agent runs in supervised production with approval gates, confidence thresholds and an audit log, and a named owner on your side reviews the exceptions.
- Hand over: you receive the code, prompts, evaluation set and runbook, and the audit trail stays in your systems, where the agent has been writing it since the Supervise step. Your team runs it, or we operate it under an agreed SLA.
Ready to Build Your AI Project?
Bring one workflow from the list above and leave with a build, buy or wait call and the metric that would prove it worked. Talk to an AI architect about your first AI project.
Free AI Assessment
The most expensive part of an AI project is choosing the wrong project or scoping it wrong. Gaper's free AI assessment finds the workflow with the most leverage and the one metric that proves it worked, makes the build-or-buy call, and says plainly if none of these ten is worth building yet.
Questions to Settle Before You Build
What's the difference between an AI project and a software project? Can't I just hire a regular engineer?
Regular engineers are trained in architectures that stay the same once they're deployed. Build a REST API once, it works the same way for years. AI projects are fundamentally different. The model's accuracy degrades over time, and vendors retire the models themselves. You need monitoring, an evaluation set, retraining, fallback logic, and versioning. You need someone who understands statistics, data quality and evaluation, not just Python and AWS, whether that person is on your payroll or a partner's.
How much should I budget for compute and infrastructure?
Budget by cost driver, not project size. Language-model projects (support bots, meeting summarizers, document processing) are driven by model calls: tokens per task times the published price times volume, so price them on real sample tasks. Churn and forecasting models are driven by warehouse compute, fraud detection by streaming and low-latency serving, and medical imaging by validation and compliant hosting. Then add the review time your approval gates need.
How do I know if my data is good enough to train a model?
You need enough examples of each outcome you're trying to predict. For some problems (like fraud detection), you need millions. More importantly, you need examples that cover all the cases you care about. If you're building a churn model but 99% of your customers don't churn, your model will be worthless (it'll just predict "no churn" for everyone). You need a reasonably balanced dataset, at least as much as you can get. Also, you need ground truth labels. If you're building a fraud model, you need to know which transactions were actually fraud, not just which ones you suspected.
Should I build or buy?
Run the Rent-vs-Own test on the workflow, not on the size of the company; the what to build first table makes the call for each idea. Buying (Fin or Zendesk for a support agent, Stripe Radar for fraud) gives you on day one what you would otherwise build and maintain, at the cost of control and customization. Build when the work touches your systems of record, client data or risk and no product fits it as sold.
How long should I expect until I see ROI?
It depends on how fast your metric moves, so set the baseline before you build and measure from the first day of supervised production. A support agent shows its effect quickly because tickets arrive daily; a churn model needs at least one renewal cycle; a fraud system needs enough shadow-mode data to compare against what happened. Timelines depend on the integrations and approvals the workflow needs, so they are scoped up front. Be wary of anyone promising payback by a date before seeing your data.
What if my model breaks in production?
It will. You'll have a bad model update, your underlying data will shift, your vendor will retire the model, or an edge case you didn't think of will show up. The question isn't "if" but "when." You mitigate this by: shipping with monitoring that catches accuracy degradation in hours, not days. Having a rollback procedure so you can go back to the old model in minutes. Rerunning your evaluation set before any model or prompt change. Having a human-in-the-loop queue for low-confidence predictions. Having alerting so your team gets paged if accuracy drops below a threshold. This is your insurance policy.
What makes a good AI project worth building in 2026?
Worth building means the problem costs clearly more than the build plus the monthly run cost, so price both before any code. It also means no product covers the workflow as sold: if one does, buying it is the better project.
How much data do you need to train an AI model?
There is no universal minimum. A predictive model needs labelled history covering every outcome you care about, and rare outcomes such as fraud can need millions of records. A language-model build that trains nothing still needs a test set of real cases with the right answer recorded.
Why do AI projects spend more time on data preparation than modeling?
Real data sits in silos, legacy formats and half-corrupted history, so cleaning and pipelines dominate the work. In a Cloudera-sponsored Harvard Business Review Analytic Services survey (2026), 73% found preparing data for AI challenging.
Should a company build its own AI system or buy a SaaS product?
Run the Rent-vs-Own test. Rent a point tool for narrow, common work such as meeting notes or a standard support widget, and own a supervised agent when the work touches your systems of record, client data or risk. Company size matters less than whether a product fits the workflow as sold.
What is the MLOps gap and why does it cause AI projects to fail?
It is the distance between a model that works on a laptop and one that runs reliably in production, with versioned pipelines, a model registry, monitoring, rollback and an evaluation set you can rerun. Projects fail there because that work is real, ongoing and rarely budgeted.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
What Makes a Good AI Project in 2026?
What Should Your Firm Build First?
Why Do AI Projects Stall Before Production?
What makes a good AI project worth building in 2026?
How much data do you need to train an AI model?
Why do AI projects spend more time on data preparation than modeling?
Should a company build its own AI system or buy a SaaS product?
What is the MLOps gap and why does it cause AI projects to fail?
25 Machine Learning Project Ideas for Beginners
AI agentsAI Agent Myths vs. Reality: What Enterprise Buyers Get Wrong
A practical breakdown of the most common AI agent myths and the production reality enterprise buyers face when taking agents from pilot to live workflows.
Apr 2, 2026
Autonomous AI Agents for Enterprise Workflows
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.