
Algorithmic Trading in Python (2026): From Backtest to a Supervised Production Pipeline
Algorithmic trading in Python, 2026: tested Backtrader code, maintained frameworks, regulator approval gates, and what replaced the $25,000 PDT rule in 2026.
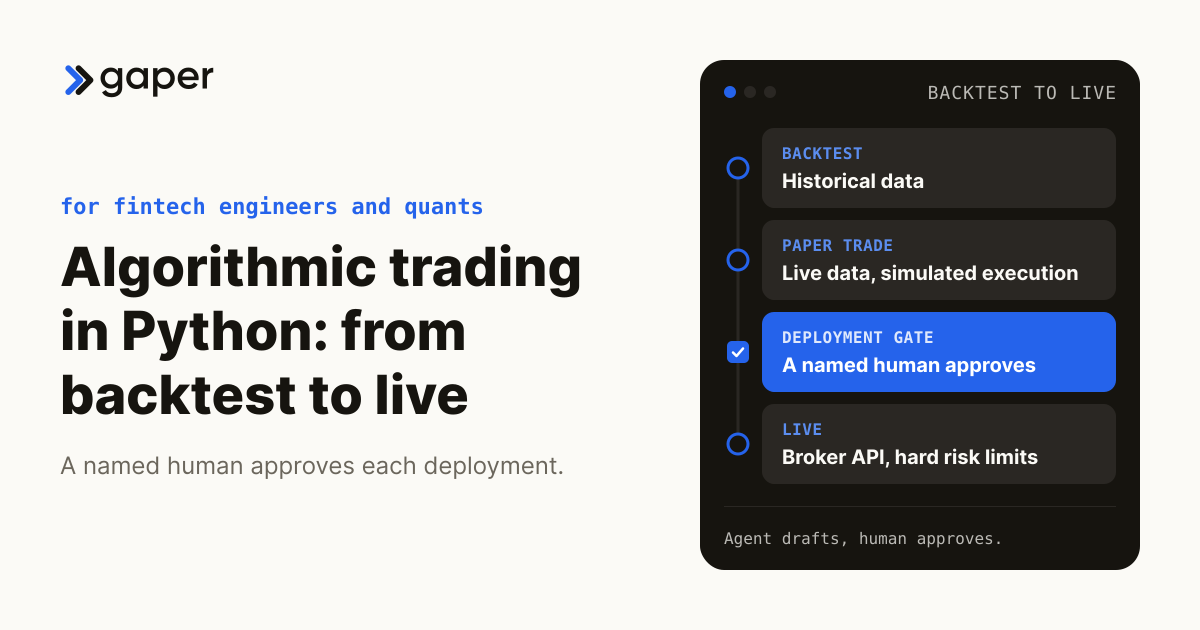
Algorithmic trading in Python means writing trading rules in Python, testing them on historical data, paper trading them, and only then letting a broker API execute them under hard risk limits. The code is the quick part. The governed loop around it, with a named human approving each deployment, is where the time and the regulatory scrutiny sit.
TL;DR: Algorithmic Trading in Python
Algorithmic trading in Python has moved from a niche practice at major hedge funds into something a small fintech, prop shop, or independent quant can run in production. But writing the strategy is the easy part. The expensive, repetitive, judgment-adjacent work is the loop around the strategy: data validation, backtest sweeps, overfitting checks, risk review, the deployment approval, live monitoring, and audit trails. That loop is where AI agents belong, and in trading, the human approval gate that agents must respect is a regulatory requirement.
- Python was used by 57.9% of respondents to the 2025 Stack Overflow Developer Survey, up 7 points in a year, and was the most desired language (39.3%).
- The global algorithmic trading market was about $21.06 billion in 2024 and is projected to reach $42.99 billion by 2030, a 12.9% CAGR from 2025 (Grand View Research).
- A moving-average crossover takes an afternoon; a governed pipeline a regulator will accept takes far longer, and is the part worth automating.
- The original Zipline is defunct, Backtrader has had no release since April 2023, and actively maintained options (zipline-reloaded, VectorBT, NautilusTrader) now matter.
- In trading, the human approval gate is mandated by supervision and market-access rules, so "agent drafts, human approves" is the compliant design, not a compromise.
- New in 2026: FINRA replaced the pattern day trader rule and its $25,000 minimum with intraday margin standards, effective 4 June 2026 (firms may phase it in until October 2027).
Educational content, not investment advice. This article explains how to build and operate algorithmic trading systems. It does not recommend any strategy, security, parameter, or capital amount, and nothing here is a prediction of returns. Trading involves substantial risk of loss. Compliance requirements below are summarized for orientation only; verify them with qualified securities counsel before you deploy anything.
What algorithmic trading in Python is
Algorithmic trading in Python means using Python to define, test, and run trading rules that a computer executes without a human placing each order. The rules can be simple (buy when the 50-day moving average crosses the 200-day) or complex (a machine-learning model scoring hundreds of features), but the shape is the same: a signal generates an order, subject to risk limits and controls, executed through a broker API.
Why Python for quantitative finance
Python won quant research because the ecosystem is unmatched: pandas and NumPy for data, scikit-learn and PyTorch for models, and a deep bench of backtesting and broker libraries. It is not the fastest language, and the lowest-latency execution still lives in C++ and FPGAs, but for research, backtesting, and anything slower than microsecond execution, Python is the default, and the language developers most want to work in.
What Python is good at, and what it is not
Python is excellent for the research-to-production loop: ingesting data, engineering features, backtesting, and deploying strategies that trade on second-to-daily horizons. It is not where you build a latency-sensitive market-making engine. Be honest about which problem you have before you pick the stack.
Python backtesting frameworks compared
The framework you pick shapes everything downstream. The landscape changed since this guide first published, so here is the current picture (releases checked on PyPI and GitHub, 29 October 2026).
| Framework | Best for | Maintenance status (2026) | Learning curve | Cost |
|---|---|---|---|---|
| zipline-reloaded | Daily-bar equity factor research, Pipeline API | Active community fork (Stefan Jansen), 3.2.1 in October 2026; the original Quantopian Zipline is defunct (last release 2020) | Steep (bundle ingestion, Pipeline paradigm) | Open source |
| Backtrader | General event-driven backtesting, broker integrations | Aging; development has slowed, still widely used (last release April 2023) | Moderate | Open source |
| VectorBT | Fast vectorized backtests, large parameter sweeps | Active (1.2.0, October 2026); fastest option for sweeps | Moderate to steep | Open core (PRO is paid) |
| NautilusTrader | Intraday, order-book, live crypto/FX | Active (1.231, August 2026); Rust core, strong live-trading focus | Steep | Open source |
| QuantConnect | Cloud backtesting, hosted data, live deployment | Active managed platform; LEAN engine is open source | Moderate | Free tier plus paid (live trading is paid) |
How to choose. For daily equity factor research, zipline-reloaded or VectorBT. For fast, wide parameter sweeps, VectorBT. For live intraday or order-book strategies, NautilusTrader. For a hosted, data-included environment, QuantConnect. Backtrader remains a reasonable teaching and event-driven engine, and it is what the tutorial below uses, but if you are choosing fresh, weigh the newer options. If a strategy is worth real capital, the framework is the least of your concerns next to the operational loop around it.
How do Zipline, Backtrader, and QuantConnect compare for Python backtesting?
Zipline lives on as zipline-reloaded, strong for daily-bar equity factor research through the Pipeline API but steep to set up. Backtrader is a flexible event-driven engine whose development has slowed. QuantConnect is a hosted platform with data included and a path to live trading.
Is Backtrader still maintained in 2026?
Backtrader has had no release or commit since 1.9.78.123 in April 2023, yet it still runs on Python 3.13 with pandas 3.1 and NumPy 2.5 in our October 2026 test. Its built-in Yahoo Finance feed no longer works, so load data another way.
Building your first Python trading algorithm, step by step
This tutorial builds a working strategy in Backtrader. Every block is runnable. Re-run on 29 October 2026 with Python 3.13, Backtrader 1.9.78.123, pandas 3.1, NumPy 2.5, scikit-learn 1.9 and yfinance 1.7; the Alpaca block was checked against alpaca-py 0.44 without sending an order. Backtrader is chosen here for clarity, not because it is the fastest engine.
Step 1: Data acquisition and preparation
Start with a simple moving-average strategy so the mechanics are clear before the logic gets interesting.
import backtrader as bt
import yfinance as yf

class MyStrategy(bt.Strategy):
    params = (('maperiod', 15),)

    def __init__(self):
        self.dataclose = self.data.close
        self.sma = bt.indicators.SimpleMovingAverage(
            self.data, period=self.params.maperiod)

    def next(self):
        if not self.position:
            if self.dataclose[0] > self.sma[0]:
                self.buy(size=100)
        else:
            if self.dataclose[0] < self.sma[0]:
                self.close()

cerebro = bt.Cerebro()
cerebro.addstrategy(MyStrategy)

# Backtrader's built-in YahooFinanceData feed no longer works with Yahoo's
# current endpoints, so download with yfinance and wrap the DataFrame.
df = yf.download('AAPL', start='2020-01-01', end='2025-01-01',
                 auto_adjust=True, progress=False, multi_level_index=False)
data = bt.feeds.PandasData(dataname=df)

cerebro.adddata(data)
cerebro.broker.setcash(100000.0)
cerebro.addsizer(bt.sizers.FixedSize, stake=100)
cerebro.run()
print(f'Final Portfolio Value: {cerebro.broker.getvalue()}')
Note: free data feeds are fine for learning, not for research you will trade. yfinance is not affiliated with Yahoo, and its README says Yahoo's API is for personal use only. Vendor feed quality, survivorship bias, and corporate-action adjustments matter more than the strategy, which is exactly why data validation is the first agent workflow later on.
Step 2: Signal generation with indicators and machine learning
Combine indicators into a signal. Backtrader's Bollinger Bands expose their lines as top, mid, and bot. Backtrader lines do not support Python's & operator, so this block uses bt.And.
class AdvancedStrategy(bt.Strategy):
    params = (('rsi_period', 14), ('bb_period', 20))

    def __init__(self):
        self.rsi = bt.indicators.RSI(self.data, period=self.params.rsi_period)
        self.bb = bt.indicators.BollingerBands(self.data, period=self.params.bb_period)
        self.macd = bt.indicators.MACD(self.data)

        # Buy when RSI is oversold AND price is below the lower Bollinger Band.
        self.signal = bt.And(self.rsi < 30, self.data.close < self.bb.lines.bot)

    def next(self):
        if self.signal[0]:
            if not self.position:
                self.buy(size=50)
        elif self.position and self.rsi[0] > 70:
            self.close()
A machine-learning variant scores features instead of using fixed thresholds. This version defines its Bollinger Bands so bb_lower and bb_upper exist, and labels each training row by whether the next bar closed higher, so there is no lookahead.
from sklearn.ensemble import RandomForestClassifier
import numpy as np

class MLStrategy(bt.Strategy):
    def __init__(self):
        self.features_buffer = []
        self.close_buffer = []
        self.model = RandomForestClassifier(n_estimators=100, random_state=42)
        self.trained = False
        self.rsi = bt.indicators.RSI(self.data)
        self.bb = bt.indicators.BollingerBands(self.data, period=20)

    def next(self):
        close_prices = self.data.close.get(size=20)  # last 20 closes
        if len(close_prices) < 5:
            return

        bb_lower = self.bb.lines.bot[0]
        bb_upper = self.bb.lines.top[0]
        bb_position = (self.data.close[0] - bb_lower) / (bb_upper - bb_lower)

        features = np.array([
            close_prices[-1] / close_prices[-5],  # 5-day return
            self.rsi[0] / 100,                     # normalized RSI
            bb_position
        ])

        if len(self.features_buffer) < 100:
            self.features_buffer.append(features)
            self.close_buffer.append(self.data.close[0])
            return

        if not self.trained:
            # Label each bar by whether the NEXT bar closed higher (no lookahead).
            X = np.array(self.features_buffer[:-1])
            closes = np.array(self.close_buffer)
            y = (closes[1:] > closes[:-1]).astype(int)
            self.model.fit(X, y)
            self.trained = True

        prediction = self.model.predict([features])[0]
        if prediction == 1 and not self.position:
            self.buy()
        elif prediction == 0 and self.position:
            self.close()
Honest note on machine learning: a model that looks brilliant in backtest is usually overfit. Markets are non-stationary, so a pattern that held last year decays, sometimes fast. This is alpha decay, and it is why the overfitting and robustness review later in this article is a real workflow, not a formality. Backtest returns are not realized returns.
Step 3: Backtesting and performance metrics
Wire in analyzers and read the metrics that matter. Backtrader's Sharpe analyzer defaults to yearly returns (five data points here), so this block annualizes from daily returns.
cerebro = bt.Cerebro()
cerebro.addstrategy(AdvancedStrategy)
cerebro.broker.setcash(100000)
cerebro.broker.setcommission(commission=0.001)  # 0.1% commission

# Track performance
cerebro.addanalyzer(bt.analyzers.SharpeRatio, _name='sharpe',
                    timeframe=bt.TimeFrame.Days, annualize=True)
cerebro.addanalyzer(bt.analyzers.DrawDown, _name='drawdown')
cerebro.addanalyzer(bt.analyzers.Returns, _name='returns')

data = bt.feeds.PandasData(dataname=df)  # df from Step 1
cerebro.adddata(data)

results = cerebro.run()
strat = results[0]

print(f"Sharpe Ratio: {strat.analyzers.sharpe.get_analysis()['sharperatio']}")
print(f"Max Drawdown: {strat.analyzers.drawdown.get_analysis()['max']['drawdown']}")
print(f"Total Return: {(cerebro.broker.getvalue() / 100000 - 1) * 100}%")
The six metrics to read, and rough thresholds for orientation (not targets, not advice):
- Sharpe ratio: risk-adjusted return. Above ~1.0 is worth attention, above ~2.0 is strong, and suspiciously high usually means a bug or lookahead.
- Sortino ratio: like Sharpe but penalizing only downside volatility.
- Maximum drawdown: the worst peak-to-trough loss. Decide your ceiling before you deploy.
- Win rate: percentage of winning trades, meaningless without payoff size.
- Profit factor: gross profit over gross loss. Above ~1.5 is generally considered healthy.
- CAGR: compound annual growth rate, read alongside drawdown, never alone.
Step 4: Risk management and position sizing
Risk controls are the difference between a strategy and a way to lose money quickly. This class enforces a drawdown ceiling and sizes positions off account risk. It defines its own signal, guards against sizing before an entry exists, and flattens the open position and stays halted once the ceiling is breached.
class RiskManagedStrategy(bt.Strategy):
    params = (
        ('max_account_drawdown', 0.20),  # stop trading if down 20%
        ('risk_per_trade', 0.02),        # risk 2% of account per trade
        ('stop_pct', 0.02),              # 2% stop loss
        ('take_pct', 0.05),              # 5% take profit
    )

    def __init__(self):
        self.entry_price = None
        self.halted = False
        self.account_high = self.broker.getvalue()
        self.sma = bt.indicators.SimpleMovingAverage(self.data, period=20)
        self.signal = self.data.close > self.sma  # simple trend filter

    def notify_order(self, order):
        if order.status == order.Completed and order.isbuy():
            self.entry_price = order.executed.price

    def next(self):
        current_value = self.broker.getvalue()
        self.account_high = max(self.account_high, current_value)
        drawdown = (self.account_high - current_value) / self.account_high

        # Hard halt if the drawdown ceiling is breached: flatten, then stay stopped.
        if self.halted or drawdown > self.params.max_account_drawdown:
            self.halted = True
            if self.position:
                self.close()
            return

        if self.signal[0] and not self.position:
            # Size off account risk and the stop distance, using the current price.
            account_risk = current_value * self.params.risk_per_trade
            stop_distance = self.data.close[0] * self.params.stop_pct
            size = int(min(account_risk / stop_distance,
                           self.broker.getcash() / self.data.close[0]))
            if size > 0:
                self.buy(size=size)

        if self.position and self.entry_price:
            if self.data.close[0] < self.entry_price * (1 - self.params.stop_pct):
                self.close()
            elif self.data.close[0] > self.entry_price * (1 + self.params.take_pct):
                self.close()
Step 5: Paper trading and live deployment
Paper trade before real capital, always. One caution on tooling: alpaca_backtrader_api has had no release or commit since January 2022 and pins Alpaca's archived alpaca-trade-api; Alpaca's current SDK is alpaca-py. Use paper trading to validate execution assumptions (fills, slippage, latency) against your backtest before going live.
# Paper trading with Alpaca's current SDK (alpaca-py), not the old
# alpaca_backtrader_api. Validate fills and slippage before risking capital.
import os
from alpaca.trading.client import TradingClient
from alpaca.trading.requests import MarketOrderRequest
from alpaca.trading.enums import OrderSide, TimeInForce

# Keys come from the environment, never from source code.
# paper=True routes to the paper environment (simulated execution, live data).
client = TradingClient(os.environ['APCA_API_KEY_ID'],
                       os.environ['APCA_API_SECRET_KEY'], paper=True)

order = MarketOrderRequest(
    symbol='AAPL',
    qty=10,
    side=OrderSide.BUY,
    time_in_force=TimeInForce.DAY,
)
client.submit_order(order_data=order)
For Interactive Brokers, the official Python client ships in IBKR's own TWS API download, and ib_async is the community successor to the archived ib_insync. Most teams that outgrow a backtesting engine for live execution move the live layer onto a maintained execution stack rather than trading directly from Backtrader. That handoff, backtest to live, is exactly where the workflow layer below earns its keep.
What is the difference between backtesting and paper trading?
Backtesting runs a strategy against historical data offline. Paper trading runs it against live market data with simulated execution, which surfaces real-world issues (latency, fills, slippage) that a backtest cannot. Do both, in that order, before live capital.
What is the most expensive mistake algorithmic traders make?
Overfitting the backtest by tuning parameters until past returns look perfect, then watching the edge vanish live as the market regime shifts. This is alpha decay, and it is why an out-of-sample and robustness review is a required workflow, not a formality.
The agentic trading-ops workflow layer
The algorithm is not the interesting automation target; the loop around it is. Research, data validation, backtest sweeps, overfitting checks, risk review, the deployment gate, monitoring, and audit trails are repetitive, judgment-adjacent, and done today by expensive people: the place for supervised agents. Because trading is regulated, the human approval gate is required by law, which makes "agent drafts, human approves" the compliant design rather than a compromise.
Each stage lists what the human does today, what an agent can own, what stays human-approved, the failure mode, and the audit artifact.
Stage 1: Data ingestion and validation
Human today: reconciling vendor feeds, spotting gaps, checking split and dividend adjustments, screening for survivorship bias. Agent-owned with alerting. Failure mode: a silent bad tick or an unadjusted split poisons every downstream backtest. Audit artifact: a daily data-quality report per feed, exceptions flagged. Unglamorous, high value, and the safest place to start.
Stage 2: Strategy research and hypothesis generation
Human today: scanning literature and factors, engineering features, retrieving prior experiments. Agent-drafted, human-directed. The agent proposes and retrieves; a researcher decides. Failure mode: plausible but spurious factors. Audit artifact: a logged hypothesis with its rationale and sources. On how far language models get writing the strategy itself, see Can LLMs crack algorithmic trading?
Stage 3: Backtest execution and parameter sweeps
Human today: setting up environments, walk-forward splits, running and aggregating sweeps. Agent-owned. Failure mode: an environment mismatch or a leaked future value invalidates results. Audit artifact: reproducible run manifests (data version, code hash, parameters, seeds).
Stage 4: Overfitting and robustness review
Human today: checking in-sample versus out-of-sample divergence, deflated Sharpe, regime sensitivity, lookahead leakage. Agent-drafted findings, human-owned verdict. The agent runs the battery of checks and flags concerns; a human makes the call. Failure mode: shipping an overfit strategy because checks were skipped under deadline. Audit artifact: a robustness report attached to the strategy.
Stage 5: Risk and position-sizing review
Human today: limit checks, drawdown ceilings, correlation with the existing book. Agent-drafted, human-approved. Failure mode: a strategy that looks fine alone but concentrates risk against positions you already hold. Audit artifact: a pre-deployment risk assessment.
Stage 6: The deployment gate
The hard stop. The agent assembles the approval package (strategy description, controls, test evidence, risk assessment); a named human approves. Nothing reaches production without it. This maps to supervision expectations under FINRA Rule 3110 and the market-access controls under SEC Rule 15c3-5. Failure mode: an ungated deployment, both a trading risk and a supervisory violation. Audit artifact: the signed approval record.
Stage 7: Live monitoring and incident response
Human today: watching for drift, comparing live fills against backtest assumptions, triggering kill switches, escalating. Agent-owned detection, human-owned intervention. Kill switches are hard-coded, never model-mediated: an LLM does not decide whether to halt trading. Failure mode: drift silently erodes the edge, or a runaway loop keeps trading. Audit artifact: a monitoring log with every alert and action.
Stage 8: Audit trail and compliance reporting
Human today: assembling order logs, strategy IDs, change history, and approval records for supervisors and examiners. Agent-owned generation, human-attested. Failure mode: an incomplete trail when a regulator asks. Audit artifact: the compliance record itself, generated continuously.

What parts of a quant research workflow can safely be automated?
Data validation, backtest orchestration and sweeps, robustness checks, monitoring, and audit-trail generation are safely agent-owned or agent-drafted. Strategy direction, the overfitting verdict, risk approval, and the deployment decision stay human. See the eight-stage breakdown above.
How do agent decisions in a trading pipeline get audited?
Every stage emits an artifact: data-quality reports, run manifests with data and code versions, robustness reports, risk assessments, signed approvals, and monitoring logs. The trail is generated continuously, not reconstructed when an examiner asks.
What should never be agent-owned in trading
Naming what you refuse to automate is what makes the rest credible to an operator and a compliance officer. These stay human, full stop:
- Autonomous capital allocation without a human gate. No strategy goes live, and no size changes materially, without a named human approving it.
- Self-modifying live strategies. A strategy that rewrites its own logic in production is unsupervisable and unauditable.
- LLM-mediated kill switches. Halts are deterministic and hard-coded. A language model never sits between a risk breach and the stop.
- Anything where a hallucinated value could reach an order router. Model output does not flow unvalidated into orders. Ever.
If a vendor cannot tell you where these lines are in their system, that is the answer.

What a governed pipeline actually costs
The right question is not what does an engineer hour cost. It is what does it cost to stand up a governed research-to-production pipeline, and what does each additional strategy cost once the pipeline exists.
The useful economics here have not changed: the first strategy is expensive because you are building the pipeline (data validation, backtesting infrastructure, risk controls, the deployment gate, monitoring, audit). Every strategy after that is far cheaper, because it rides the same governed rails. That is an infrastructure-and-agents cost curve, not a per-hour staffing one. You are buying a durable capability your team owns, not renting hours.
For how that maps to a build decision and payback, see the AI agent development cost and AI agent ROI breakdowns rather than a price you will not be able to hold us to.
Regulatory compliance for algorithmic trading
Compliance summarized for orientation only. It is not legal advice, and the specifics change. Verify with qualified securities counsel before deploying.
Supervision and registration
Firms running algorithmic strategies are subject to FINRA Rule 3110 (Supervision), which requires supervisory systems and written procedures, before and after a strategy is deployed. Under FINRA Regulatory Notice 16-21 (SEC-approved in 2016, effective 30 January 2017), the people primarily responsible for designing, developing, or significantly modifying algorithmic trading strategies, or supervising that work, must register as Securities Traders and pass the Series 57. If you build algos at a member firm, that may include your engineers. Regulatory Notice 15-09 (2015) adds guidance, such as testing before production and launching new strategies as limited pilots.
Market access and pre-trade controls
SEC Rule 15c3-5 (the Market Access Rule) requires broker-dealers with market access to apply pre-trade risk controls to every order, human or algorithmic: blocking orders that breach credit or capital thresholds, rejecting erroneous or duplicative ones, with an annual review the chief executive certifies. In practice this is where hard limits and kill switches live.
Short selling and anti-fraud
Regulation SHO governs short selling, including locate and close-out requirements; its Rule 203 bars a broker-dealer from accepting a short sale unless it has borrowed the security or has reasonable grounds to believe it can be. SEC Rule 10b-5 is the general anti-fraud rule and, for algorithms, the backdrop for manipulation concerns such as spoofing and layering. These are separate from market-access controls.
Practical checklist
- Pre-trade risk controls under the market-access rule, applied before any order reaches an exchange.
- Hard-coded kill switches and position limits, tested and documented.
- A documented approval process with a named supervisor for each strategy.
- A complete, timestamped audit trail: orders, strategy IDs, changes, approvals.
- Registration for the people who design or significantly modify strategies, where the rule applies.
Treat the above as a map, not the territory, and confirm it with counsel.
What does a regulator expect from an automated approval gate?
A documented supervisory system (FINRA Rule 3110), approval protocols before new or changed code reaches production (FINRA Notice 15-09), pre-trade risk controls on every order (SEC Rule 15c3-5), and a complete audit trail. An agent can assemble the package; a person approves it. Confirm with counsel.
Does the pattern day trader rule still apply in 2026?
Not in its old form. FINRA replaced the pattern day trader designation, the day-trade count and the $25,000 minimum with intraday margin standards in Rule 4210, effective 4 June 2026, and firms may phase the change in until 20 October 2027.
The SEC approved it on 14 April 2026 (FINRA Regulatory Notice 26-10). Regular maintenance margin is unchanged. If an algorithm day trades in a margin account, ask your broker which regime it applies today.

What is the realistic minimum capital to start algorithmic trading live?
Backtesting and paper trading cost nothing. Some brokers allow live trading with very low or no account minimums, so capital is rarely the constraint; data quality, risk controls, and discipline are. Verify current minimums directly with the broker, as they change.
How Gaper shows up
Gaper is an AI-native implementation partner. For trading and quant operations, we build and deploy the supervised agent workflows described above, the data-validation, backtest-orchestration, robustness-review, monitoring, and audit-generation layers, into your own stack, on your data, with the human approval gates your obligations require. You own the system and can hand it to your regulator.
What that means for this buyer specifically:
- Ownership and auditability, not labor. Here we build a governed pipeline your team owns and can change, not a block of engineer hours (Gaper also offers staff augmentation when a team wants vetted developers it manages), with the audit trail an examiner expects generated by default.
- Agents where they belong, humans where the rules require. Every workflow above respects a named-human approval gate and hard-coded kill switches. That alignment with supervision and market-access rules is the point, not a limitation.
- We do not touch what should stay human. No autonomous allocation, no self-modifying live strategies, no model-mediated halts.
This is the flagship engineering piece for our AI agents for fintech work. If you want to go deeper on the build decision, see build vs buy AI agents and how to become AI-native, and on the operational side, deploy AI agents and AI agent data privacy for enterprises.
Book a free AI assessment and we will map which part of your research-to-production loop is the highest-leverage place to automate, and scope the smallest governed workflow worth shipping. Free, 30 minutes, no obligation. Or talk to an AI architect about the technical and compliance shape of it.
Build or buy trading infrastructure?
Buy a hosted platform if a common workflow fits its rails and you do not need to change it. Build (and own) when the pipeline touches your data, your controls, and your regulatory posture, so you can audit and modify it. See build vs buy AI agents.
That is the Rent-vs-Own test: rent a point tool for narrow, common work; own a supervised agent when it touches systems of record, data or risk. Gaper is the AI-native implementation partner that deploys supervised AI agents you own.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
How do Zipline, Backtrader, and QuantConnect compare for Python backtesting?
Is Backtrader still maintained in 2026?
What is the difference between backtesting and paper trading?
What is the most expensive mistake algorithmic traders make?
What parts of a quant research workflow can safely be automated?
How do agent decisions in a trading pipeline get audited?
What does a regulator expect from an automated approval gate?
Does the pattern day trader rule still apply in 2026?
What is the realistic minimum capital to start algorithmic trading live?
Build or buy trading infrastructure?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.