Cloud Large Language Models in 2026: Choosing a Hosted LLM Platform for Production Agents
Cloud large language models in 2026: Bedrock, Microsoft Foundry and Google's Agent Platform compared on models, residency, pricing, agent tools and lock-in.
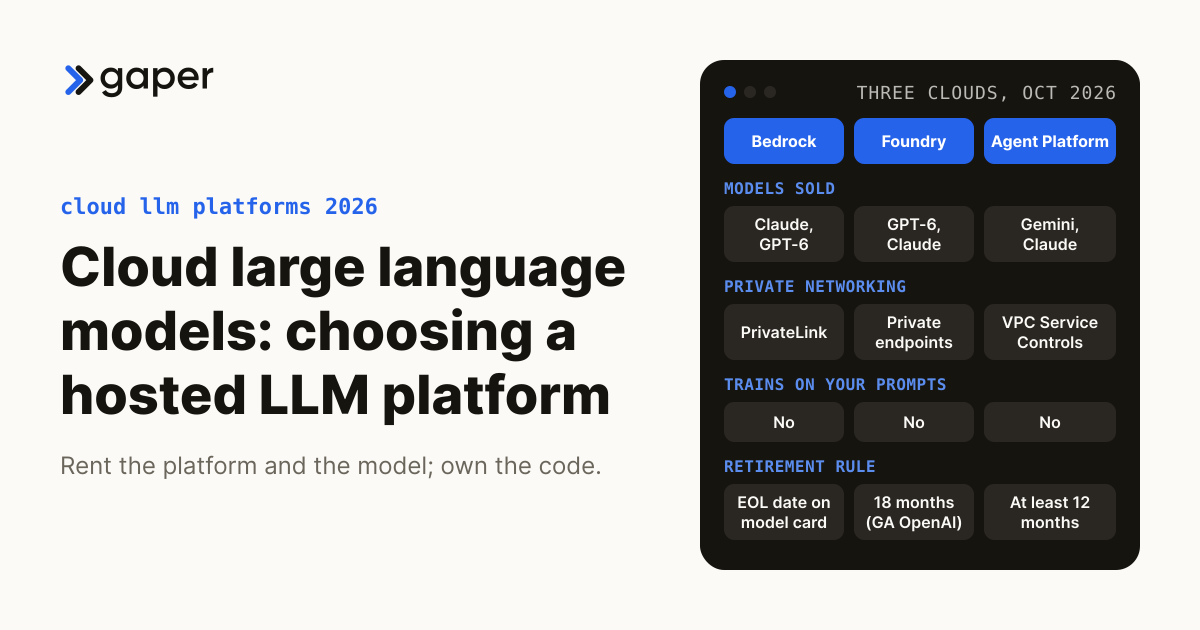
For production agents in October 2026, run cloud large language models on the platform inside the cloud agreement you already have: Amazon Bedrock and Microsoft Foundry sell Claude and OpenAI's GPT-6 models, and Google's Gemini Enterprise Agent Platform, the new name for Vertex AI, sells Gemini and Claude. Decide on residency, retention, retirement rules and agent tooling, and keep the prompts, evaluation set, runbook and code in your own repository so the platform or model can be swapped.
Updated October 2026: platform facts checked on AWS, Microsoft and Google's own pages on 27 October 2026.
Cloud large language models in 2026: a buyer's guide to hosted LLM platforms
Engineering leaders shipping production AI in 2026 evaluate cloud large language models across three hyperscale platforms, the vendors' own APIs, and self-hosted open weights. The right pick depends on data residency, throughput floor, token economics, and how much vendor lock-in your finance team will tolerate.
Key Takeaways
- All three hyperscalers sell Claude; Bedrock and Foundry add OpenAI's GPT-6 models, and only Google sells Gemini.
- List prices run from $0.10 input and $0.50 output per million tokens (GPT-6 Luna, Claude Haiku 5.5) to $10 and $50 (GPT-6 Astra, Claude Fable 5.1); batch halves most of them.
- P95 first-token latency varies 4x across providers, from 280 ms on Anthropic Haiku to 1,200 ms on heavyweight reasoning endpoints.
- One model can retire on different dates: Claude Sonnet 4.5 leaves Anthropic's API and Foundry on 30 November 2026, Bedrock on 8 April 2027.
Table of Contents
- The 2026 cloud LLM landscape
- Comparing the five major providers
- What each platform offers in October 2026
- Pricing models: per token, reserved, dedicated
- Latency, throughput, and data residency
- Picking a provider by workload
- How three buyer archetypes ship
- Lock-in pitfalls and BYO-model options
- Buyer questions, answered
The 2026 cloud LLM landscape
Every option promises production inference without running GPUs in-house. The gap between a vendor's API and the clouds has closed for Claude: Anthropic announced Claude Opus 5.5 (22 September 2026), Sonnet 5.5 and Haiku 5.5 as available on AWS, Google Cloud and Microsoft Azure on launch day.
The buying decision changed sharply in 2025, when reasoning models (Gemini 2.0 Flash Thinking in December 2024, Claude 3.7 Sonnet in February 2025, OpenAI o3 in April 2025) broke the old "small and cheap versus big and expensive" trade-off. A 2026 buyer picks a routing strategy across three to five models, not one model. Hyperscaler contracts bind LLM spend to the same enterprise agreement covering S3, BigQuery, or Office 365, which simplifies procurement but lengthens lock-in.
2026 Hosted LLM Market Dashboard
| Market metric | Latest figure | Source |
|---|---|---|
| Enterprise generative AI spend | $37 billion in 2025, up from $11.5 billion in 2024 | Menlo Ventures, December 2025 |
| Enterprise LLM API spend share | Anthropic 40%, OpenAI 27%, Google 21% | Menlo Ventures, an Anthropic investor |
| Enterprises on 3 or more model families | 81%, up from 68% | Andreessen Horowitz, January 2026 |
| Price of a fixed level of AI performance | Down about 47% a quarter | Epoch AI, September 2026 |
The market is no longer "which model is smartest." It is which mix of models, hosted under which contract, hits your latency, residency, and unit-economics targets at scale.
Comparing the five major cloud large language models providers
Amazon Bedrock leads on model breadth and IAM integration for AWS teams. Microsoft Foundry suits workloads on Microsoft 365 or Dynamics and now sells Claude beside OpenAI's models, though Anthropic operates Claude there. Google's Agent Platform ships first on Gemini, grounds answers in Google Search, and has the deepest BigQuery tie-ins.
The two pure-play APIs (Anthropic and OpenAI) expose the richest tool-use and streaming primitives and carry the lowest integration overhead. The cost is a separate contract, a separate compliance review, and data that may transit a smaller vendor's network. Most 2026 buyers we see end up running a primary hyperscaler contract plus one pure-play API on the side for whichever new model that vendor has shipped this quarter. For teams that want a single architect to scope this, our LLM engineering specialists design the routing layer and the failover policy in the first sprint.
Provider Capability Bars (0 to 100)
Internal Gaper benchmark, Q1 2026: model breadth counts distinct hosted families; frontier speed measures days between vendor release and platform availability; compliance scores aggregated SOC 2, HIPAA, FedRAMP, ISO 27001 coverage.
| Provider | Model breadth | Frontier speed | Compliance |
|---|---|---|---|
| AWS Bedrock | 95 | 70 | 90 |
| Azure OpenAI | 60 | 85 | 95 |
| GCP Vertex AI | 75 | 80 | 85 |
| Anthropic API | 35 | 98 | 70 |
| OpenAI API | 40 | 95 | 65 |
Bedrock and Azure dominate compliance. Anthropic and OpenAI dominate time-to-frontier. Vertex wins when data gravity is on Google Cloud. The right pick is almost never one of these alone, usually two wired together with a routing fallback.
Scores use Q1 2026 names: Vertex AI is now Gemini Enterprise Agent Platform, and Azure OpenAI sits in Microsoft Foundry.
What does each cloud LLM platform offer in October 2026?
All three hyperscalers sell Claude, open-weight models and their own families; Bedrock and Foundry also sell OpenAI's GPT-6 models, and only Google sells Gemini. They differ on residency, retention, retirement policy and agent tooling maturity, so compare those rows first.
| Checked 27 Oct 2026 | Amazon Bedrock | Microsoft Foundry | Google Gemini Enterprise Agent Platform |
|---|---|---|---|
| Models | Claude 5.5 family and Fable 5.1, GPT-6 models, gpt-oss, Llama 4 (Legacy, ends March 2027), Mistral, DeepSeek, Qwen3 | GPT-6 models, gpt-oss, DeepSeek V4, Llama 4 (retiring by January 2027), Mistral, Grok; Claude 5.5 family as partner models | Gemini 4 Argon, 3.8 Flash and 3.1 Pro (preview), Claude 5.5 family and Fable 5.1, Llama 4, DeepSeek, gpt-oss, Qwen 3 |
| Residency | In-Region, geographic profiles (US, EU, APAC and others), or global routing at about 10% less | Data at rest in your Azure geography; processing Global, Data Zone (such as US or EU) or Regional | Global (no residency guarantee), US or EU multi-region, or regional; non-global endpoints cost about 10% more on GA Gemini 3 and later |
| Private networking | AWS PrivateLink | Private endpoints; agents can use your virtual network | VPC Service Controls, Private Service Connect |
| Your data | Not used to train, not shared with model providers | Not available to OpenAI or other providers, not used to train | Not used to train or tune without permission |
| Retirement rule | "EOL no sooner than" date on each new model card | GA OpenAI models retire at 18 months, 60 days' notice minimum | Stable models at least 12 months; dates never move earlier |
| Compliance | HIPAA eligible, FedRAMP Moderate; FedRAMP High in GovCloud (US-West), each model authorized separately | Azure OpenAI FedRAMP High | On Google's HIPAA BAA list; FedRAMP High in Assured Workloads |
Sources: AWS models, regions, FAQs, lifecycle; Microsoft models, deployments, privacy, retirements, FedRAMP; Google models, residency, pricing options, versions, HIPAA.
Direct vendor APIs offer less private networking: OpenAI's Private Link works only on Azure, through sales (OpenAI). Claude Platform on AWS is a hybrid: billed through your AWS account, but Anthropic processes the data outside AWS (AWS). For vendor-by-vendor prices and data terms, see AI giants compared: Google vs OpenAI vs Anthropic.
Do cloud LLM platforms train on your prompts or keep your data?
None of the three hyperscalers trains models on your prompts, but each keeps some data in some cases: flagged content for abuse review, and full prompts for the most capable gated models. Zero retention is a setting or an approval, not a default, so confirm it model by model.
- Bedrock: Claude Fable 5 and 5.1 require opting in to a retention mode that keeps prompts and outputs inside AWS up to 30 days for possible review by AWS, not shared with Anthropic (AWS).
- Foundry: a sample of flagged content may be stored for human review unless you are approved for modified abuse monitoring. On Claude, Anthropic is an independent processor, and Anthropic-hosted versions may process data outside Azure (Microsoft).
- Google: Search grounding keeps logs up to three days with no off switch, and Claude Fable prompts are logged for 30 days (retention, abuse monitoring).
Pricing models: per token, reserved capacity, and dedicated deployments
Cloud LLM pricing defaults to per-token, but per-token is only one of three meters. Reserved capacity buys a throughput floor: Bedrock's Reserved tier runs 1 or 3 months with a 99.5% uptime target (AWS), Azure's reservation discount varies by model and term, and Google's Provisioned Throughput runs 1 week to 1 year (Google). Dedicated deployments give you a private endpoint billed by the machine hour. Per-token wins at low volume. Reserved wins above 50 million tokens per day.
Batch costs 50 percent less on all five where a model supports it, flex tiers trade latency for a discount, and priority costs more ($3.60 instead of $2 per million input tokens on Gemini 4 Argon through 30 November 2026). Support varies: on Bedrock, Claude Opus 5.5 runs on Standard only.
The hidden cost is the output-to-input ratio. Flagship models charge about 5 to 6 times more for output than input, and reasoning tokens bill as output. At list price, a call with 2,000 input and 500 output tokens costs $0.00045 on Claude Haiku 5.5 and $0.045 on GPT-6 Astra, and 5,000 reasoning tokens lift the Astra call to $0.295. The fix is to route by intent: small models for classification and retrieval, frontier reasoning only where needed. Teams hiring senior Python developers to build that routing layer typically recover the engineering cost in under 60 days.
2026 Cloud LLM Pricing Ledger
| Model tier | Input ($/M tokens) | Output ($/M tokens) | Discount | Primary host | Best use |
|---|---|---|---|---|---|
| Open weights (DeepSeek V4.1 Flash) | $0.30 peak, $0.15 off-peak | $1.20 peak, $0.60 off-peak | Off-peak 50% | DeepSeek API, Agent Platform, your GPUs | Batch, bulk drafting |
| Small (GPT-6 Luna, Claude Haiku 5.5) | $0.10 | $0.50 | Batch 50% | Claude on all three clouds, GPT on Bedrock and Foundry | Routing, classification |
| Mid tier (GPT-6.1 Sol, Claude Sonnet 5.5) | $2.00 | $10.00 | Batch 50% | Same as above | Production chat, agents |
| Flagship (Claude Opus 5.5) | $4.00 | $20.00 | Batch 50% at Anthropic | All three clouds | Hard adjudication |
| Flagship (GPT-6 Astra, Claude Fable 5.1) | $10.00 | $50.00 | Batch 50% at the vendor | Vendor APIs, Bedrock, Foundry; Fable also on Google | Hardest reasoning |
| Blended per request (typical) | $0.0021 | $0.0094 | -58% routed | 2 primaries | Mixed workload |
Vendor list prices checked 27 October 2026 (OpenAI, Anthropic, DeepSeek). Cloud prices sit on each platform's pricing page; on Bedrock and Google, regional endpoints cost about 10 percent more than global.
The ledger gives a single message: model selection beats provider selection on cost. A routed stack across mid and workhorse tiers, with frontier reasoning reserved for the 8 to 12 percent of requests that actually need it, lands at a blended cost roughly 58 percent below an all-frontier deployment.
Latency, throughput, and data residency
Latency varies more than price in 2026. P50 first-token on Anthropic Haiku via direct API in us-east-1 sits around 220 ms. The same model through Bedrock in eu-west-1 sits at 380 ms. Frontier reasoning with extended thinking pushes P95 past 1,200 ms before streaming. The spread matters: a chatbot feels slow above 600 ms, and an agent loop firing 8 to 15 calls per task hits a wall when each call adds 800 ms.
P95 First-Token Latency by Provider (ms)
Gaper internal P50 and P95 first-token latency benchmark, 200,000 production requests, March 2026, us-east-1 region. Reasoning models excluded from streaming workloads.
Throughput matters at the other end. A team running 200 tokens-per-second sustained on pay-as-you-go hits rate limits within a month. Reserved capacity locks a guaranteed floor; all three clouds sell it, but Anthropic no longer sells new Priority Tier commitments (Anthropic). If your workload is bursty and predictable, reserve. If it is unpredictable, stay pay-as-you-go.
Data residency closes the picture, and each cloud draws the line differently. Bedrock's geographic profiles keep requests in one geography, while global routing can use any commercial Region. Foundry's Global deployments may process prompts in any Azure region, and only the Azure-hosted Claude versions offer a US data zone. Google's EU endpoint excludes the UK and Switzerland. Anthropic's own API offers US-only inference at 1.1 times list price, and Claude's regional endpoints on Bedrock and Google Cloud cost 10% more than global (Anthropic). For HIPAA, GDPR-restricted, or APAC sovereignty workloads, hyperscaler residency is simpler than negotiating a custom DPA with a pure-play vendor.
What agent tooling does each platform give you for guardrails, evaluation and MCP?
All three clouds now cover the same four jobs: guardrails on inputs and outputs, agent evaluation, a managed agent runtime, and MCP for tools. They differ in maturity, since some pieces are still preview, and in lock-in, since a hosted runtime keeps agent state on the platform.
- Bedrock: Guardrails, Evaluations with LLM-as-a-judge, and AgentCore, whose Gateway turns APIs into MCP tools (AWS).
- Foundry: Foundry Agent Service with MCP tools, Guardrails that can check calls to supported tools (preview; MCP tools are not covered), agent evaluators, and the open Microsoft Agent Framework (Microsoft).
- Google: the open-source Agent Development Kit, Agent Runtime, Model Armor, Agent Platform Evals and remote MCP servers; its Managed Agents API is a preview Google says is not for production (Google).
Build with an SDK that runs in your own account, treat platform guardrails as one layer of AI agent security, and keep tool-call traces in your own AI agent observability stack.
Picking a cloud LLM provider by workload
The cleanest way to choose a provider is to plot the workload on two axes: data sensitivity and throughput predictability. Sensitivity tells you the residency and indemnification contract. Throughput tells you whether reserved capacity will pay off. Each quadrant collapses the shortlist to two providers and a routing fallback.
Workload Fit Matrix
A 2×2 frame engineering leaders can use to shortlist providers in a single meeting. Place each candidate workload in a quadrant before picking the contract type.
| Predictable throughput | Bursty or unknown throughput | |
|---|---|---|
| High sensitivity | Your cloud's hyperscaler, regional endpoint, reserved after 60 days | Same hyperscaler, pay-as-you-go in-region |
| Low sensitivity | Open weights on dedicated capacity | Direct vendor API or global endpoint, pay-as-you-go |
The matrix captures roughly 90 percent of 2026 buying decisions. Regulated workloads usually land on the hyperscaler that already holds the BAA and FedRAMP paperwork: Azure or Bedrock for most teams, Google's Agent Platform where the data sits on Google Cloud. Open workloads with predictable throughput favor open-weight models on dedicated capacity, where unit economics beat frontier APIs at sustained scale.
When should you self-host open-weight models in your own cloud?
Self-host when the data must stay in your own account with no model vendor in the path, when traffic keeps a GPU busy, or when you need weights no vendor can retire. Otherwise a managed API is cheaper, because a dedicated GPU bills by the hour whether or not traffic arrives.
gpt-oss-120b runs on a single 80 GB GPU under Apache 2.0 (model card), Gemma 4 is Apache 2.0, DeepSeek V4 is MIT, and vLLM serves all three. In between, Google's Model Garden deploys open models into your own project and VPC, billed per node hour, and Bedrock's Custom Model Import accepts Llama 3, Mistral, Qwen and gpt-oss architectures. Your team still patches and monitors it; deploying AI agents into production covers what that takes.
How three buyer archetypes ship
The cleanest way to picture provider selection is to walk three real buyer profiles through the choice. A 40-person fintech, a 600-person healthcare network, and a Series B SaaS team each land in a different corner of the matrix with different contracts and unit economics. Being wrong costs roughly 18 to 36 months of lock-in plus a 25 to 40 percent margin tax.
Three Buyer Archetypes: Cost, Stack, Payback
Three sample workloads our team scoped in Q1 2026. Cost lines are blended pay-as-you-go plus reserved capacity, including embedding and storage.
| Case | Archetype | Workload profile | Stack | Monthly cost | Payback |
|---|---|---|---|---|---|
| Case A | Fintech contract copilot | 40-person team, 8 million tokens per day, regulated EU + US data. | Azure OpenAI + Bedrock failover | $4,200 | 6 weeks vs in-house build |
| Case B | Healthcare clinical scribe | 600-person network, 120 million tokens per day, HIPAA. | Bedrock PTU + Vertex on EHR | $48,000 | 11 weeks (clinician hours) |
| Case C | SaaS in-product AI feature | Series B, 25 million tokens per day, low sensitivity. | Anthropic direct + GPT-4o mini | $11,500 | 9 weeks (ARR uplift) |
Each archetype lands at the same playbook: pick the platform that matches your residency contract, route across two model tiers, and only reserve throughput after the workload has run for 60 days. Teams that want a faster start use AI engineers from Gaper to stand up routing, evaluation harness, and observability in the first two weeks.
Since Q1, OpenAI has set 14 January 2027 for GPT-4o mini to leave its API, so a Case C build would re-test on a replacement.
Lock-in pitfalls and BYO-model options
Cloud LLM lock-in shows up in five places, and each has a 2026 mitigation that did not exist 18 months ago. The point is not to avoid lock-in entirely (some is the price of compliance) but to make sure every contract has a visible exit ramp.
Five Cloud LLM Lock-In Pitfalls
The five lock-in patterns we see most often during 2026 contract renewals. Each one has a low-cost mitigation if engineered in before the first production deploy.
| # | Pitfall | Risk and mitigation |
|---|---|---|
| 01 | Proprietary tool-use formats | Each vendor's function-calling schema is different. Mitigation: wrap calls in an internal abstraction and expose tools through MCP, so switching providers is a config flip, not a refactor. |
| 02 | Reserved capacity overhang | Commitments run from 1 week to 1 year, and Azure PTUs cannot be paused. Mitigation: never reserve more than 60 percent of forecast load. Burst the rest on pay-as-you-go. |
| 03 | Fine-tune portability | A fine-tune trained on one platform usually cannot be exported. Mitigation: prefer open-weight base models for any fine-tune you may want to migrate. |
| 04 | Embedding-space coupling | Vectors indexed under one embedding model are not portable to another. Mitigation: pick an embedding family with multi-vendor support, or budget for a re-embedding pass on switch. |
| 05 | Indemnification cliffs | Vendor indemnity often caps at the contract value or excludes derivative outputs. Mitigation: read the indemnification clause, not the marketing page, before signing. |
BYO-model options sit alongside these: Bedrock Custom Model Import and Google's Model Garden host open weights you bring, and Foundry sells open-weight models directly. The combination of open weights on hyperscaler residency is the cleanest 2026 hedge against lock-in: you keep the model artifact you own, and you only rent the compliance and inference fabric. Keep the exit ramp visible inside the architecture, even when you do not plan to use it.
A sixth pattern worth naming is the implicit lock-in in your evaluation harness. Teams that hard-code golden datasets against one provider's response style cannot compare a new model apples-to-apples. Evaluate against task outcomes, not literal output strings. Once the harness is portable, the provider choice stops being a decade-long decision and becomes a quarterly one.
Underneath sits the Rent-vs-Own test: rent a point tool for narrow, common work; own a supervised agent when it touches systems of record, data or risk. For an owned agent, rent the platform and the model, and own the code, prompts, evaluation set, runbook and audit trail. Then a platform change or a model retirement is a re-test, not a rebuild.
How do model retirements work on each platform?
Each platform sets its own minimum: Bedrock posts an "EOL no sooner than" date for new models, Foundry retires GA OpenAI models at 18 months with 60 days' notice, Google keeps stable models at least 12 months, OpenAI promises at least six months for generally available models, and Anthropic at least 60 days.
The same model can leave on different dates: Claude Sonnet 4.5 retires from Anthropic's API (Anthropic) and Foundry on 30 November 2026, and from Bedrock on 8 April 2027. Notice can run shorter than the stated minimum: OpenAI's 14 October 2026 notice removes GPT-4o, GPT-4o mini, GPT-4.1 and GPT-4.1 mini from its API on 14 January 2027, three months later, and its policy allows a faster timeline for safety or compliance concerns (OpenAI). Foundry does not auto-upgrade provisioned deployments, so reserved capacity can strand you on a retiring model.

Ready to ship cloud LLM features without the routing headache? Gaper engineers have built production routing, evaluation harnesses, and reserved-capacity strategies across Bedrock, Azure OpenAI, Vertex, Anthropic, and OpenAI. Tell us the workload and we will scope the stack in a free assessment call. Book a free AI assessment. Free assessment. No commitment.
What are cloud large language models and why are 2026 buyers using them?
Cloud large language models are LLMs you call through a managed API, on Amazon Bedrock, Microsoft Foundry, Google's Agent Platform or a vendor's own API, instead of running GPUs yourself. The platform handles capacity, compliance and model updates, and you pay per token.
Buyers can mix multiple providers behind a single routing layer, which trims blended cost roughly 58 percent versus an all-frontier deployment.
How much do cloud LLM platforms cost per million tokens in 2026?
At October 2026 list prices, from $0.10 input and $0.50 output per million tokens on GPT-6 Luna and Claude Haiku 5.5 to $10 and $50 on GPT-6 Astra and Claude Fable 5.1, with Claude Opus 5.5 at $4 and $20. Batch halves most of these; regional endpoints on Bedrock and Google add about 10%.
Most production stacks land at a blended cost of roughly $0.0021 input and $0.0094 output per request after routing. The largest cost driver is output token count, especially on reasoning models, whose thinking tokens bill as output.
Which cloud LLM provider is best for regulated workloads like HIPAA or GDPR?
All three hyperscalers now cover the basics: Bedrock is HIPAA eligible, Azure OpenAI holds FedRAMP High, and Google lists Agent Platform on its HIPAA BAA. For GDPR, pick an EU data-zone or multi-region endpoint and confirm the model supports it.
Most healthcare and banking teams run Azure or Bedrock as the primary, with the pure-play APIs gated behind a separate compliance review. Check per model: Claude on Foundry runs under Anthropic's terms, and Microsoft's BAA covers in-scope services, so confirm Foundry's scope in its Service Trust Portal. This is information, not legal advice.
Can I fine-tune a cloud large language model without locking in to one vendor?
Yes, if you fine-tune open-weight base models such as Llama 3, Qwen, Mistral or gpt-oss, and keep the training data yourself. Those weights stay portable across Bedrock Custom Model Import, Google's Model Garden and your own GPUs; tunes of proprietary models cannot be exported.
OpenAI closes self-serve fine-tuning to new jobs on 6 January 2027, and Anthropic documents Claude fine-tuning only through Amazon Bedrock. Try retrieval first (RAG vs fine-tuning), and see custom LLM vs general-purpose LLM for when a tune earns its place.
How fast can Gaper staff a cloud LLM project?
Gaper assembles an LLM engineering team in days. Each engineer is screened for technical depth, communication, and time-zone overlap. Teams typically stand up the first routing layer and evaluation harness inside the first sprint.
Gaper.io is an AI-native implementation partner that builds and deploys production AI agents you own and run in your own cloud. Gaper is the AI-native implementation partner that deploys supervised AI agents you own. Here is what that means.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
What does each cloud LLM platform offer in October 2026?
Do cloud LLM platforms train on your prompts or keep your data?
What agent tooling does each platform give you for guardrails, evaluation and MCP?
When should you self-host open-weight models in your own cloud?
How do model retirements work on each platform?
What are cloud large language models and why are 2026 buyers using them?
How much do cloud LLM platforms cost per million tokens in 2026?
Which cloud LLM provider is best for regulated workloads like HIPAA or GDPR?
Can I fine-tune a cloud large language model without locking in to one vendor?
How fast can Gaper staff a cloud LLM project?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.