
AI MVP Development: How to Build a Real AI Prototype, Not a Demo
AI MVP development, step by step: demo vs MVP, eval sets first, six stages with exit criteria, what drives cost and what changes in production.
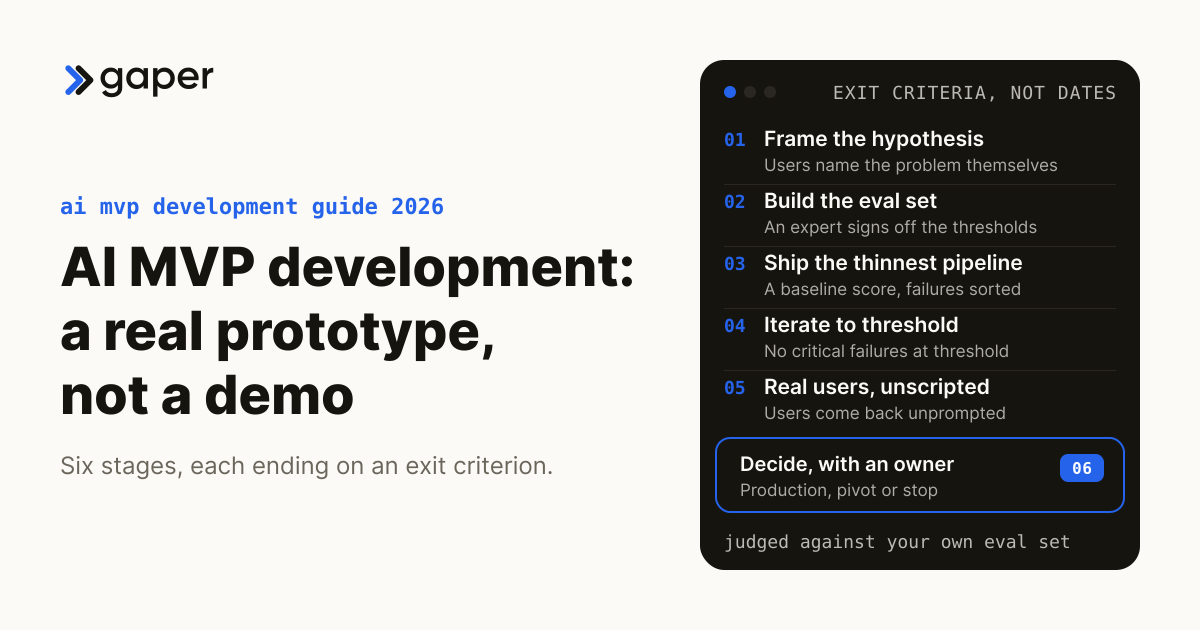
AI MVP development is building the smallest version of an AI product that real users can rely on with their own unscripted inputs, judged against an evaluation set and a success metric you fix before you build. A demo shows the idea working once; an MVP shows it working often enough that people come back. Build it in stages with exit criteria, start on a hosted model, and move to production only when the numbers and the users say so.
What is the difference between a demo, a proof of concept, a prototype and an MVP?
A demo shows an idea on hand-picked inputs, and a proof of concept tests one technical question, such as whether a model can extract the right fields. A prototype puts a working flow in front of users, while an MVP is the smallest version people use on real work, measured against a success metric set in advance.
Eric Ries defined the MVP as the version that yields the most validated learning about customers for the least effort (Startup Lessons Learned, 2009). For AI, that learning has two halves: do users want it, and is the model good enough on inputs nobody rehearsed?
| Demo | Proof of concept | Prototype | MVP | |
|---|---|---|---|---|
| Question it answers | Can this look right? | Can the model do the hard part? | Can users work with it? | Will users rely on it? |
| Inputs | Hand-picked | A test set for one task | Representative samples | Real user inputs, unscripted |
| Who drives it | The builder | An engineer | Users, with guidance | Users, alone |
| Measured by | Reactions in the room | Pass rate on one task | Task completion and feedback | Eval score against a threshold, plus repeat use |
A real prototype makes live model calls on inputs like the ones users will send, works without the builder in the room, logs its errors and latency, and comes with a written list of what it cannot do yet.

At a glance: the four stages side by side, plus the four tests a prototype has to pass before it counts as real.
Why do AI prototypes stall before they become products?
AI prototypes tend to stall because nobody defined good enough, so output quality becomes an argument instead of a number, the scope is too wide to measure, and the system never learns from use. Meanwhile costs climb and the value stays unclear.
Gartner predicted in June 2025 that over 40% of agentic AI projects will be canceled by the end of 2027, citing escalating costs, unclear business value or inadequate risk controls (Gartner, June 2025).
Quality is the most cited wall. In LangChain's State of Agent Engineering survey (a vendor survey of 1,340 mostly technology respondents, late 2025), 32% named quality as a top barrier to production (LangChain, 2025). MIT NANDA's preliminary 2025 research named the core barrier as learning, since most systems do not retain feedback or improve over time, and found the startups doing well picked narrow, high-value use cases and integrated deeply into customers' workflows (MIT NANDA, The GenAI Divide, July 2025).
For founders, that becomes five familiar mistakes:
- Building in stealth, so feedback arrives late.
- Treating the fundraising demo as the MVP.
- No evaluation set, so each change is judged by the last example tried.
- Scope too wide to score, such as "an assistant for lawyers".
- Integration left until last, so it only works in a sandbox.
How do you define good enough before you build an AI MVP?
Write the success metric and build the evaluation set first. Pick the one number that says the product does its job, set a threshold to ship and a floor at which you stop, and collect real inputs with correct outputs labelled by someone who knows the domain. Every later change is judged against that set.
Anthropic's builder guidance makes the same point: success criteria should be specific and measurable, and evaluations should mirror the real mix of tasks, edge cases included (Anthropic, 2026).
Public benchmarks will not do this job for you; only your own cases show whether a model is good enough. Yet just over half (52.4%) of LangChain's 2025 respondents run offline evaluations on test sets (LangChain, 2025).
| Element | What to write down |
|---|---|
| User and job | Who uses it, and the one job it does for them |
| Success metric | The number that says it works, such as the share of outputs an expert accepts without edits |
| Ship threshold and stop floor | The score that earns real users, and the score at which you change course |
| Critical failures | Errors that block shipping on their own, such as an invented citation |
For a full test plan, see how to evaluate AI agents.
Reference build: illustrative, not a client engagement. A contract review product a startup sells to in-house legal teams. Job: for each customer, flag supplier contract clauses that depart from that customer's playbook and draft a suggested redline. Eval set: de-identified sample contracts labelled clause by clause by a lawyer, plus scanned and incomplete ones. Critical failure: missing a clause the playbook marks as must-review. Oversight: every redline is agent-drafted and lawyer-approved. Measured by: the share of flags accepted without edits, missed must-review clauses, and whether early customers' lawyers return to it unprompted.
What are the six stages of an AI MVP plan?
Frame the hypothesis, build the eval set, ship the thinnest working pipeline, iterate until it clears the threshold, put it in front of real users, then decide: production, pivot or stop. Each stage ends on an exit criterion rather than a date, so nobody moves on because the calendar says so.
Timelines depend on the integrations and approvals the workflow needs, so they are scoped up front.
| Stage | What you do | Exit criterion |
|---|---|---|
| 1. Frame the hypothesis | Write down the user, the job, today's workaround and why AI changes the economics; talk to target users | Users describe the problem in their own words and say what they would stop doing if this worked |
| 2. Build the eval set | Collect real inputs, label correct outputs with a domain expert, set the metric, threshold and floor | Product owner and domain expert sign off the set and thresholds |
| 3. Ship the thinnest pipeline | A hosted model through an API, one prompt, retrieval only if the job needs your data, every run logged | A baseline score, with failures sorted into categories |
| 4. Iterate to threshold | Fix the largest failure category first: prompt, retrieval, tool design, then model choice | At or above the ship threshold, with no critical failures |
| 5. Real users, unscripted | Staging deployment, logging, human approval on anything risky, no builder in the room | Users come back unprompted, and every new failure is in the eval set |
| 6. Decide | Compare eval score, usage and cost per successful task with the hypothesis | A written decision (production, pivot or stop) with a named owner |
If the product will process health, financial or tax records supplied by customers, check before you collect eval data whether rules such as a HIPAA business associate agreement or, for tax return information, IRC section 7216 consent apply to you, because they can attach from the first real record. This is information, not legal advice.
Do you need to fine-tune a model for an AI MVP?
Usually not at first. Start with a hosted model, a strong prompt and retrieval over your own data, and fine-tune only when the eval set shows a gap prompting and retrieval cannot close, or when cost at volume calls for a smaller model.
Retrieval fixes missing knowledge; fine-tuning changes behavior and format, and the RAG vs fine-tuning comparison covers when each pays off. Data rules are a separate question: if they keep inputs away from third-party APIs, an open-weight model hosted in your own environment, fine-tuned or not, keeps inputs, weights and logs under your control.
How much does AI MVP development cost?
We found no independent, published benchmark for AI MVP cost. The bill is driven by people time, the number of integrations, data preparation and labelling, evaluation work and model usage.
The median annual wage for US software developers was $135,980 in May 2025 (BLS, 2025). For full-time private industry workers in professional and related occupations, the group that includes software developers, benefits were 32.0% of employer compensation costs in June 2026 (BLS, September 2026). Applying that share to the May 2025 wage puts a full-time developer at roughly $200,000 a year in wages and benefits (our arithmetic).
Cheap tokens do not make a cheap product. In McKinsey's State of AI 2026 survey (1,719 respondents, May to June 2026), one in five said operating costs, tokens included, limit their organization's AI use, and senior fellow Michael Chui notes that for agentic coding and complex reasoning, tokens consumed have grown even faster than per-token costs have fallen (McKinsey, August 2026).
| Cost driver | What pushes it up | What keeps it down |
|---|---|---|
| Team time | Extra roles, rework from unclear scope | One narrow job, eval set first |
| Integrations | Every system the product reads or writes | Start with one, read-only |
| Data preparation | Scattered data that needs expert labelling | Label a focused eval set before any training set |
| Model usage | Long inputs, the largest model for every step, agent loops | Smaller models for easy steps, caching, usage limits |
Track cost per successful task from stage 3, not total spend; it shows whether the product can carry a price. For agents that work inside a customer's systems, our guide to AI agent development cost breaks the drivers down further. Gaper publishes no price bands for product MVPs; each is scoped against its eval set and integrations, so scope your AI MVP in a free AI assessment.
What changes when an AI MVP goes to production?
Almost everything around the model. The eval set becomes a regression suite that runs on every change, logs become monitoring with alerts, risky actions get approval gates and permissions, costs get budgets, and someone owns model upgrades.
| Area | At MVP | In production |
|---|---|---|
| Evaluation | Eval set run before changes | Regression suite on every prompt, tool or model change, plus checks on live traffic |
| Observability | Run logs | Tracing, dashboards and alerts |
| Human oversight | The builder reviews outputs | Approval gates on material actions, escalation paths |
| Model lifecycle | Whichever model passes | Pinned versions, retesting before any swap |
| Data terms | De-identified samples | Contracts covering training, retention and region |
Model retirement is easy to miss. Anthropic notified developers on 30 September 2026 that Claude Sonnet 4.5 would retire from its API on 30 November 2026 (Anthropic, 2026), and each retirement means rerunning the eval set on the replacement.

At a glance: how evaluation, observability, oversight, model lifecycle and data terms change between MVP and production.
Who do you need on an AI MVP team?
Three roles cover most AI MVPs: a product owner who holds the hypothesis and makes scope calls, an AI engineer who owns model choice, prompts and evals, and a backend engineer who owns data, integrations and deployment. Add a domain expert to label the eval set, and design help once users are in the loop.
| Role | Owns | Without it |
|---|---|---|
| Product owner (often the founder) | Hypothesis, scope, user conversations | Features nobody asked for |
| AI engineer | Model choice, prompts, retrieval, eval set | A system overbuilt, or trusted beyond its ability |
| Backend engineer | Data, integrations, deployment, logging | It works in a notebook and nowhere else |
| Domain expert | Labels, edge cases, judging outputs | Nobody can say what correct looks like |
To price the salaried route for the AI roles, try the AI engineer salary calculator.
When does an implementation partner beat hiring for an AI MVP?
Hire when AI is the long-term core of your product and you can recruit and keep the people. Use a partner when you need to prove the product before committing headcount, when nobody in-house has taken an AI system through evals to production, or when the work is one bounded job. Either way, you should own the code.
The research compares buying with building, not partners with hires. In MIT NANDA's preliminary 2025 interviews with 52 organizations, AI tools bought from or co-developed with external vendors reached deployment about 67% of the time, against about 33% for fully internal builds; the authors note the figures are self-reported and the gap may reflect the organizations rather than the approach (MIT NANDA, July 2025). In McKinsey's 2026 State of AI report, senior partner Lieven Van der Veken notes that more leaders now ask what it takes to build AI tools themselves, and that leading organizations engage partners "from a position of agency", choosing deliberately where to buy and where to build (McKinsey, August 2026).
So an implementation partner should leave you more capable, not more dependent. Before you sign, ask who owns the code, prompts and eval set, whether your team can run the system alone, and whether the partner will tell you when not to build. If AI direction has no owner on your leadership team, Gaper also provides a fractional Chief AI Officer.
Is an AI MVP the same as an AI agent pilot?
No, an AI MVP tests whether customers want a product and can rely on it, while an AI agent pilot tests whether one internal workflow can run with an agent inside your own operations. The methods overlap, evals first and real inputs early, but the users, success metrics and the decision at the end are different.
If you are automating your own back office rather than building a product, run an AI agent pilot instead.
How Gaper scopes and builds an AI MVP you own
Gaper is the AI-native implementation partner that deploys supervised AI agents you own. We are not a staffing agency: you get production agents and the code, not contractors. For an AI product, we build the agent at the core of the MVP, with the eval set and controls it needs for production.
The work follows the Gaper method:
- Assess. Is AI the right tool, and is a hosted model with a good prompt enough? If an existing tool covers the job, we say so.
- Scope. The success metric, thresholds, eval set and integrations, plus a Gaper Ownership Map labelling every step of the product's flow as Automated, Agent-drafted, human-approved, or Human-owned.
- Build. Our forward-deployed engineers embed with your team, scope one workflow and build the agent in your repo and your cloud, with evals, guardrails and human approval on risky actions. Where the eval set or your data rules call for it, we fine-tune or self-host open-weight models in your environment.
- Supervise. Real users, logged runs, approval gates on anything material, and every new failure added to the eval set.
- Hand over. You own the code, prompts, evaluation set, runbook and audit trail. Your team can operate it without us, or we operate it under an SLA.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
What is the difference between a demo, a proof of concept, a prototype and an MVP?
Why do AI prototypes stall before they become products?
How do you define good enough before you build an AI MVP?
What are the six stages of an AI MVP plan?
Do you need to fine-tune a model for an AI MVP?
How much does AI MVP development cost?
What changes when an AI MVP goes to production?
Who do you need on an AI MVP team?
When does an implementation partner beat hiring for an AI MVP?
Is an AI MVP the same as an AI agent pilot?
Enterprise Automation Beyond Chatbot Theater: How AI Agents Deliver Real Business Impact
Nov 5, 2026AIEnterprise Automation Beyond Chatbot Theater: How AI Agents Deliver Real Business Impact
Nov 5, 2026AIChatbot ROI: The Real Reason Your Bot Isn't Saving Money
Most chatbots stall before they ever pay back. Here's why chatbot ROI breaks at the pilot-to-production line, and what it takes to fix the math.
Apr 15, 2026Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.