
Llama 3.1 to Llama 4 in 2026: A Migration Guide for Business Teams
Llama 3.1 to Llama 4 in 2026: what changed, Meta's new Muse models, license terms, cloud retirement dates and when a business team should migrate.
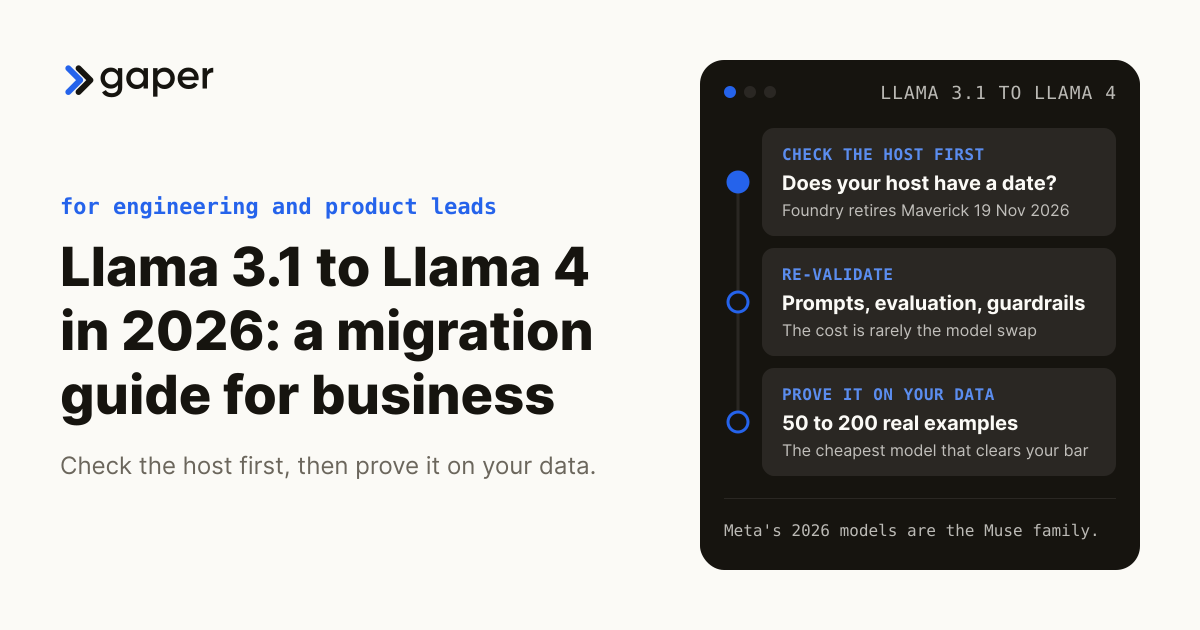
Move from Llama 3.1 to Llama 4 only if its efficiency or long context helps a real workflow, and prove it on your own data first. In October 2026 the more urgent date is hosting: Amazon Bedrock ends its remaining Llama models on 30 March 2027, Microsoft Foundry retires Llama 4 Maverick on 19 November 2026, and Meta's newest models ship under the Muse name. For most business teams the answer is a hosted or managed endpoint picked by a small evaluation, not a GPU purchase.
TL;DR: Llama 3.1 to Llama 4 for a normal business
If you run a 10 to 200 person firm, here is the short version.
- Model choice is the least important decision you will make. The workflow around the model, the data plumbing, the evaluation, and the human approval gates are where the value and the risk live. An implementation partner earns its keep there, not on picking a model.
- Llama 4 is a Mixture-of-Experts (MoE) model. Scout and Maverick both activate 17 billion parameters per token, out of ~109B and ~400B total, which makes them cheaper to serve than dense models of the same size.
- Llama 4 is the newest Llama, not Meta's newest model. Meta's 2026 models are the Muse family, and several clouds are retiring Llama endpoints.
- For almost every SMB, self-hosting makes no economic sense. Owning GPUs only beats per-token pricing at billions of tokens a month. Even with a confidentiality duty, a managed open-weight endpoint usually wins.
- Do not choose a model from a benchmark table. Choose with a small evaluation on your own data.
A note on scope. This page began as a Llama 3.1 article and is now a migration guide; model, license and hosting facts were checked at vendors' own pages on 29 October 2026. The accounting and insurance sections are general information, not legal, tax, or professional advice; a licensed professional must review anything client-facing in those fields.
What changed from Llama 3.1 to Llama 4
Llama 3.1 launched on 23 July 2024 in 8B, 70B and 405B sizes with a 128K-token context window. The 405B model competed with the GPT-4 generation, and the 8B and 70B variants became the base for thousands of production systems.
Llama 4 arrived on 5 April 2025 and changed the architecture from dense to Mixture of Experts (MoE). In Llama 3.1 405B, all 405 billion parameters run for every token. In an MoE model, a router sends each token to only a few of many "experts," so Scout and Maverick each activate about 17 billion parameters per token. That is the efficiency trick: near-large-model quality at small-model serving cost.
For a business, the migration effort is rarely the model swap. It is re-validating your prompts, your evaluation, and your guardrails against the new model's behavior.
Should I migrate from Llama 3.1 to Llama 4?
Only if Llama 4's efficiency or context actually helps your workflow, or your host is retiring Llama 3.1. If Llama 3.1 works for you today, "it works" is a valid reason to stay. The migration cost is re-validating prompts, evaluation, and guardrails, not the model swap.
Check the host first. Amazon Bedrock ended Llama 3.1 405B on 7 July 2026 and ends 3.1 8B and 70B on 30 March 2027; Microsoft Foundry retired Llama 3.1 405B and 8B on 13 June 2026. If your endpoint has a date, evaluate Llama 4, a Muse open-weight model and a hosted frontier API before you pick.
What is Mixture of Experts and why does it matter?
MoE splits a model into many "experts" and routes each token to only a couple of them, so a large-total model runs at small-model cost per token. It is why Llama 4 can be big and still relatively cheap to serve.
The catch: every expert still sits in memory, so Scout needs hardware sized for 109B parameters. MoE cuts compute per token, not the size of the machine.
The Llama 4 models: Scout, Maverick, and the one that never shipped
- Llama 4 Scout (
meta-llama/Llama-4-Scout-17B-16E-Instruct): 17B active / ~109B total, 16 experts. Meta says it fits on a single H100 with Int4 quantization and advertises a 10 million token context window, though usable context is bounded by your hardware memory. - Llama 4 Maverick (
meta-llama/Llama-4-Maverick-17B-128E-Instruct): 17B active / ~400B total, 128 experts, 1 million token context. The higher-quality variant for reasoning and multimodal work, heavier to serve (Meta says it fits on a single H100 host, which means eight GPUs). - Llama 4 Behemoth: previewed as a ~2-trillion-parameter model and never publicly released.

Both released models are natively multimodal (text and image in) and open-weight under Meta's community license, which is not a fully open-source license. Three terms in the Llama 4 license and Acceptable Use Policy matter to a business:
- 700 million users. If your products had more than 700 million monthly active users on the Llama 4 release date, you need a separate license from Meta.
- The EU clause. For the multimodal Llama 4 models (Scout and Maverick), the license rights are not granted to individuals domiciled in the EU or companies with their principal place of business there; end users of a product built on them are not affected. EU-headquartered firms should take legal advice.
- Attribution. Products must show "Built with Llama", and a fine-tuned model you distribute must start its name with "Llama".
What Meta offers in October 2026
No Llama model has shipped since Llama 4: the newest repositories in Meta's Hugging Face organization date from April 2025, and llama.com redirects to Meta's Muse developer site, which lists no Llama. Meta's hosted Llama API preview is gone too: its site redirects the same way and Meta's notice is no longer online; Promptfoo's provider docs date the shutdown 6 July 2026. Llama weights stay on Hugging Face.
Meta Superintelligence Labs now ships under the Muse name. Muse Spark (8 April 2026) and Muse Wonder (12 October 2026) are hosted on the Meta Model API, and Muse Spark also runs in Meta AI. Two others ship open weights:
| Model | Released | Size | License | Built for |
|---|---|---|---|---|
| Muse Glimmer | 10 Aug 2026 | 30B | Apache 2.0 | Local agents on one consumer GPU |
| Muse Spark Open | 15 Oct 2026 | 816B total, 42B active, 1M context | Muse Model License | Coding and agentic work |
Meta calls Muse Spark Open the most capable US open-weight model to date. Beyond Meta's usage policy, its license adds two conditions: show "Built with Muse Spark Open", and, if you and your affiliates take more than 20 million US dollars in revenue over 12 months, sign a separate agreement with Meta before selling the model to others as an API. Internal use and features inside your own product are exempt from the second.
Where Llama 4 runs, as of 29 October 2026:
| Host | Llama 4 status |
|---|---|
| Amazon Bedrock | Scout and Maverick Legacy since 30 Sep 2026 (no new customers); end of life 30 Mar 2027 |
| Microsoft Foundry | Maverick retires 19 Nov 2026; Scout 31 Jan 2027 |
| Gemini Enterprise Agent Platform (formerly Vertex AI) | Scout and Maverick GA as managed APIs; Llama 3.3 70B endpoint retirement dated 21 Oct 2026 |
| Groq | Maverick shut down 9 Mar 2026; Scout 17 Jul 2026 on free and developer tiers |
| Inference providers | Scout still served, for example by DeepInfra; Maverick on fewer hosts |
What is the difference between Llama 4 Scout and Maverick?
Both activate 17B parameters per token. Scout has ~109B total across 16 experts and is the efficient workhorse (fits a single H100 with Int4). Maverick has ~400B total across 128 experts and is the higher-quality, heavier variant.
Scout is also easier to keep running: more providers serve it, and it outlasts Maverick on Microsoft Foundry.
When will Llama 4 Behemoth be released?
It was previewed, delayed repeatedly through 2025, and never publicly released. In October 2026 it is absent from Meta's Hugging Face organization and developer pages, and Meta's new work ships as Muse. Do not plan around it.
Why you should not choose a model from a benchmark table
At release, Meta submitted a version of Maverick to the LMArena leaderboard (blind human preference rankings, renamed Arena in January 2026). That version, Llama-4-Maverick-03-26-Experimental, "optimized for conversationality," scored an ELO of 1417 and placed second (TechCrunch, 6 April 2025). But it was not the one Meta released. The public weights landed around 32nd, below models that were months old (TechCrunch, 11 April 2025). LMArena said Meta's interpretation of its rules "did not match what we expect from model providers," and changed its policy (April 7 to 8, 2025, as quoted by Simon Willison).
The lesson: a benchmark number can be true and useless at the same time. A score comes from a specific version, prompt style and test that may look nothing like your work, and saturated tests like MMLU and HumanEval rank top models within noise.
The practical alternative: a small evaluation harness on your own data
Test candidates on your actual work. You do not need an ML team, and it takes an afternoon:
- Collect 50 to 200 real examples from the workflow you want to automate (invoices, support tickets, listing descriptions), paired with the correct or acceptable output.
- Write down your acceptance criteria in plain language, for example "correct vendor, amount and GL category; flags anything ambiguous."
- Run each candidate model (Scout, Maverick, a Muse open-weight model, a hosted frontier API) on the same examples with the same prompt.
- Score the outputs against your criteria. Pass/fail per example plus a note on failures is enough to start.
- Pick the cheapest model that clears your bar, and keep the harness. Re-run it whenever a model updates, your host retires one, or your data drifts.
Fifty labeled examples from your own workflow beat every benchmark table combined. Building this harness is exactly the work an implementation partner should be doing with you, and it is the honest core of a model decision. Gaper is the AI-native implementation partner that deploys supervised AI agents you own.
How do I tell if a model is good enough for a specific task?
Build a small evaluation harness: 50 to 200 real examples from your workflow, plain-language acceptance criteria, run each candidate model, score pass or fail. Pick the cheapest model that clears your bar. This beats any benchmark table.
Is Llama 4 better than a proprietary API model?
For some tasks yes, for many no, and it depends on your task, not on a leaderboard. Llama 4's own launch (the LMArena episode above) is a reminder that leaderboard rank and real-world quality can diverge sharply. Test on your data.
Open weights buy control over where the model runs and when it changes; a proprietary API buys the strongest models with nothing to operate. Our guide to custom versus general-purpose LLMs weighs that trade on cost, data and lock-in.
The honest self-host question for an SMB
Vendors selling GPUs or "private AI" say self-hosting an open model saves money. For a small or mid-sized firm, it almost never does.
Self-hosting is a fixed cost. To serve Llama 4 you rent GPUs by the hour whether you use them or not. AWS on-demand rates (AWS price list, 28 October 2026):
| Path | Rough monthly cost (on-demand, us-east-1) | Notes |
|---|---|---|
| p5.48xlarge (8x H100) | ~$40,000 (about $55/hr) | Full-precision serving; fell from ~$98/hr after AWS's June 2025 GPU price cut |
| p5.4xlarge (1x H100) | ~$5,000 (about $6.88/hr) | The single H100 Meta quotes for Int4 Scout |
| g5.48xlarge (8x A10G) | ~$11,900 (about $16/hr) | Older GPUs, tighter memory |
| g6e.xlarge (1x L40S) | ~$1,360 (about $1.86/hr) | Single small GPU, quantized models only |
A hosted API is a variable cost. Llama 4 Scout runs $0.10 per million input tokens and $0.30 per million output at DeepInfra; Maverick is $0.24 input and $0.97 output on Amazon Bedrock in us-east-1 (AWS price list, 28 October 2026; Legacy, existing customers only). A few million tokens a month costs single-digit dollars.
Now the crossover. To justify the cheapest single-GPU box (~$1,360/month) against ~$0.30 per million tokens, you would need on the order of 4 to 5 billion tokens a month. A 40-person insurance agency generates a rounding error against that, so self-hosting at SMB volume buys a full-time infrastructure problem to save nothing.

So when is open-weight the right call for an SMB?
Three honest conditions:
- A hard confidentiality or data-residency obligation. A carrier contract, a client agreement, or a regulation that forbids sending data to a third-party API.
- A regulator or contract that bans third-party processing of the specific data involved.
- Genuinely high volume in one narrow, repetitive task, where per-token pricing does add up.
Even then, the answer is usually the third path: a managed open-weight endpoint (Amazon Bedrock, Google Cloud, Microsoft Foundry, or an inference provider). That is what most SMBs mean by "we need to self-host." If you are not sure which side of the line you are on, a free AI assessment is the place to settle it.
Should a small business self-host Llama 4 or use an API?
For almost every SMB, use a hosted API or a managed open-weight endpoint. Self-hosting only pays off at billions of tokens per month or under a hard confidentiality or data-residency obligation, and even then a managed endpoint usually beats running your own GPUs.
In 2026, also pick a host whose retirement date is past your planning horizon.

What does it cost to run Llama 4 at small volume?
Through an API, a few million tokens a month costs single-digit dollars (Scout is $0.10 per million input and $0.30 per million output at DeepInfra in October 2026). Self-hosting starts in the four-to-five-figure range per month regardless of usage, which is why it rarely makes sense at SMB volume.
Meta's newer open-weight models cost more when hosted: Together AI lists Muse Spark Open at $1.25 input and $4.25 output per million tokens, and Muse Glimmer at $0.35 and $1.50 (checked 29 October 2026).
Does my client data stay private?
With a hosted API, read the provider's data-use terms; reputable providers do not train on your data by default, but you must confirm it. A managed open-weight endpoint gives stronger data controls and, where needed, a business-associate-style agreement.
Confidentiality is a contract-and-configuration question, not a reason to buy a GPU. See AI agent data privacy for enterprises for keeping client data governed inside an agent.
SMB deployment patterns by vertical
These are illustrative deployment patterns, not case studies. They describe what these workflows look like in a typical small firm. They do not reference specific Gaper clients, and they contain no invented metrics or outcomes.
Marketing agency: client reporting and campaign QA
Firm profile: 15 to 60 people running paid and lifecycle campaigns. Before: an account manager pulls performance data monthly, writes client commentary, and eyeballs for anomalies. After: data pull and first-draft commentary become agent-drafted; anomaly flagging is agent-owned; the client-facing narrative is human-owned. The approval gate: a human reads every client-facing paragraph before it sends. Model choice: a hosted frontier API, because client-facing prose quality matters more than fractions of a cent. What breaks: a confident narrative attached to a misread metric, which is why a person reads the paragraph. What it takes: connectors to the ad and analytics platforms, a brand-voice sample, a couple of weeks to first value. This is squarely AI agents for marketing territory.
Accounting and bookkeeping firm: categorization and close prep
Firm profile: 10 to 80 people on QuickBooks or NetSuite. Before: staff categorize transactions, chase documents, and prep the close by hand. After: categorization and document intake become agent-owned behind a confidence threshold; close entries are agent-drafted, human-approved; anything material stays human-owned. The approval gate: an exception queue plus a reviewer sign-off before books close. Model choice: a managed open-weight endpoint, because client financial data carries a real confidentiality obligation, and a managed endpoint gives you data controls (and, where needed, a business-associate-style agreement) without a GPU in the office. What breaks: a silent misclassification that compounds across a quarter, the reason the exception queue exists. What it takes: ledger integration, a labeled sample of the firm's own transactions, licensed review of the workflow. See AI agents for accounting; a finance agent like AccountsGPT fits this shape.
Insurance agency or broker: submission and document intake
Firm profile: 10 to 100 people handling submissions, ACORD forms, renewals, and certificates. Before: CSRs re-key PDFs into the agency management system and assemble paperwork. After: intake and field extraction become agent-owned; renewal and certificate drafts are agent-drafted, human-approved; anything touching coverage terms is human-owned. The approval gate: hard-coded field validation against the source document, plus a licensed producer signing off on anything that touches coverage limits, effective dates, or terms. Model choice: a hosted API is fine for extraction, but if a carrier contract forbids third-party processing of insured data, move to a managed open-weight endpoint in the agency's own cloud, a data-residency decision, not a cost one. What breaks: a hallucinated coverage limit or effective date reaching a binding document, an errors-and-omissions exposure. This is the vertical where the discipline below (what we refuse to automate) matters most. What it takes: AMS integration, the carrier's document formats, and legal review of the validation rules.
Real estate brokerage or property management: listings, disclosures, and tenant communication
Firm profile: a brokerage or property manager with a few dozen to a few thousand doors. Before: agents prepare listings and disclosures, abstract leases, triage maintenance, and draft tenant messages by hand. After: lease abstraction and maintenance triage become agent-owned; listing copy, disclosures, and tenant messages are agent-drafted, human-approved; anything public-facing is human-owned. The approval gate: a compliance review on all public-facing and tenant-facing language. Model choice: a hosted API, because volume is low and the risk is in what the model writes, not where it runs. What breaks: fair-housing exposure in a generated listing or tenant message, a legal risk with real penalties and no obvious warning sign. That is why every public-facing line gets human compliance review.
Notice the different answers: frontier API for marketing, managed open-weight endpoint for accounting, a conditional private endpoint for insurance, plain hosted API for real estate. If a vendor tells all four to "self-host Llama," they are selling you infrastructure, not solving your problem.
What we refuse to automate
Naming the lines is what makes the rest trustworthy, and in these verticals the lines are not optional:
- No coverage terms without a licensed producer. In insurance, anything touching a limit, an effective date, or policy language is human-owned and human-signed.
- No public-facing or tenant-facing copy without compliance review. Fair-housing and advertising rules apply to what the model writes, not to who wrote it.
- No books closed on unreviewed AI categorization. An exception queue and a human sign-off stand between the agent and the ledger.
- No hallucinated value reaching a document of record. Field validation against the source is hard-coded, never model-judged.
How to actually deploy Llama 4 (for the technical reader)
For whoever sets it up. If that is not you, skip to the hardware question below.
Local testing with Ollama
Good for trying the model first. Even quantized, Scout is a large download (67 GB for Ollama's Scout tag, 245 GB for Maverick) and needs substantial memory; a laptop is for testing, not production.
# Install Ollama (macOS/Linux)
curl -fsSL https://ollama.com/install.sh | sh

# Pull and run Llama 4 Scout (tag checked against ollama.com/library/llama4, Oct 2026)
ollama run llama4:scout

# Serves an OpenAI-compatible API at localhost:11434; point your OpenAI SDK at that base URL.
Self-serving with vLLM
For teams with a genuine reason to self-host. Flags change, so check vLLM's docs.
pip install vllm

# Serve Llama 4 Scout (gated weights: accept Meta's license on Hugging Face first).
# Full bfloat16 needs several GPUs; Meta's single-H100 figure is for Int4.
vllm serve meta-llama/Llama-4-Scout-17B-16E-Instruct \
  --tensor-parallel-size 8 \
  --dtype bfloat16 \
  --max-model-len 131072 \
  --port 8000

# The 10M-token context is memory-bound: set --max-model-len to what you need.
Managed open-weight endpoints (what most teams should use)
If you need open weights but not a cluster, use Amazon Bedrock, Google Cloud's Agent Platform, Microsoft Foundry, or an inference provider: an OpenAI-compatible endpoint, data controls, no GPUs to babysit. Check the retirement dates in the table above, and compare platforms on residency, pricing and lock-in in our guide to cloud large language models.
Fine-tuning
Most SMBs do not need to fine-tune; good prompting and retrieval over your own documents usually get there faster and cheaper. If you genuinely need the model to learn a format or a domain vocabulary, fine-tune a small variant, and read RAG vs fine-tuning first, because retrieval is often the right answer instead.
Can I run Llama 4 on consumer hardware?
You can run a quantized Scout for testing on a strong workstation, but it is a large model (Ollama's Scout download is 67 GB) and a laptop is for experimentation, not production. Maverick is heavier still.
Meta built Muse Glimmer for local use: it says the 30B model shrinks to under 20 GB at about 4-bit precision and runs within a 24 GB or 32 GB GPU memory budget.
How Gaper shows up
Gaper is an AI-native implementation partner. For an SMB, the work is not "which model," it is everything around it:
- Choosing the deployment path honestly. Sometimes that means telling you not to self-host, and not to over-buy. If a hosted API is right, we say so.
- Building the evaluation harness on your data so the model choice is evidence, not a benchmark screenshot.
- Wiring the workflow into the tools you already use (your ledger, your AMS, your ad platforms, your PMS), with a quarterly cadence to re-check quality as data and models drift.
- Setting the approval gates the vertical requires, and serving it behind an OpenAI-compatible layer so you are never locked to one model.
- Handing you something you own. Not rented engineers, a governed workflow your team runs.
Where we have a product it maps cleanly: AccountsGPT for finance and bookkeeping workflows, Stefan for marketing operations. Where we do not, we build a supervised agent to fit. For the build decision, see build vs buy AI agents and AI agent development cost.
In a free AI assessment we will tell you honestly whether you need Llama at all, and map the one workflow worth automating first. Free, 30 minutes, no obligation.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
Should I migrate from Llama 3.1 to Llama 4?
What is Mixture of Experts and why does it matter?
What is the difference between Llama 4 Scout and Maverick?
When will Llama 4 Behemoth be released?
How do I tell if a model is good enough for a specific task?
Is Llama 4 better than a proprietary API model?
Should a small business self-host Llama 4 or use an API?
What does it cost to run Llama 4 at small volume?
Does my client data stay private?
Can I run Llama 4 on consumer hardware?

Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.