Custom LLM vs General-Purpose LLM
When to build a custom LLM in 2026: fine-tuning, RAG and open weights against GPT-6, Claude 5.5 and Gemini 3 on cost, data, ownership and lock-in.
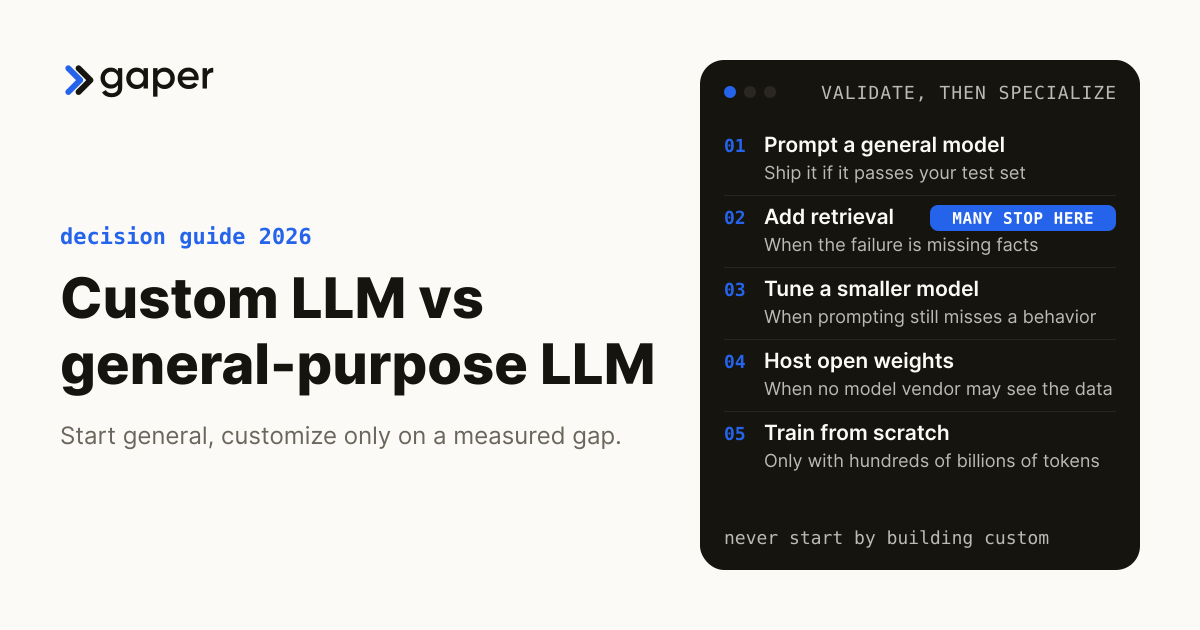
For most companies in October 2026, a general-purpose model such as GPT-6.1 Sol, Claude Sonnet 5.5 or Gemini 3.8 Flash, grounded in your own documents through retrieval (RAG), beats a custom LLM on cost, flexibility and upkeep. Build a custom model only when your own evaluation set shows a gap that prompting and retrieval cannot close, and you hold the labelled data, the right to train on it and a plan to keep the model alive after its base model retires.
Quick Verdict: Custom LLM vs General-Purpose LLM
- Choose general-purpose LLMs if: you need a versatile tool for many tasks, want to start from what already works, and speed to market matters more than domain precision.
- Choose custom LLMs if: you have a narrow, stable task that a tuned model handles measurably better on your evaluation set, data that no AI model vendor may see, or a proprietary corpus no base model has seen.
- Choose a hybrid approach if: you want GPT-6 Astra, Claude Opus 5.5 or Gemini for general work, retrieval over your own documents, and a small tuned model only for the narrow steps that need one. This is the pattern we recommend most often.
Updated 13 October 2026: every model name, price and fine-tuning option was rechecked on the vendors' own pages, replacing GPT-4.5, Claude Opus 4.6, Gemini 3 Pro and cost and timeline ranges we could not source.
Two different decisions hide behind "custom LLM vs general-purpose LLM". Find yours first.
| If you are | What decides it | Start with |
|---|---|---|
| Evaluating models for a product | Quality on your own test set, cost per call, latency, and whether the vendor still lets you tune the model | The head-to-head comparison, then the cost comparison |
| Deciding what your firm should own | Data rights, retention, who can change the model after launch, and what you keep if you leave a vendor | Why custom model projects stall, then the four approaches compared |
Definition: AI-native implementation partner. A firm that builds, deploys and supervises production AI agents inside your existing systems, then hands over the code, prompts and runbook so you own what runs. It ships working agents, not advice or billable hours. Gaper is the AI-native implementation partner that deploys supervised AI agents you own. What an AI-native implementation partner does, and when you should not hire one.
Table of Contents
- General-Purpose vs Custom LLMs: The Core Tradeoff
- General-Purpose LLMs: Strengths and Limitations
- Custom LLMs: When and Why to Build
- Custom vs General-Purpose: Head-to-Head Comparison
- The Decision Framework: Build, Buy, or Both?
- Why Custom Model Projects Stall
- Prompting vs RAG vs Fine-Tuning vs a Custom Model
- Cost Comparison: Custom vs General-Purpose
- How to Build a Custom LLM in 2026
- Gaper Builds Both Custom and Hybrid AI Solutions
- Buyer questions, answered
General-Purpose vs Custom LLMs: The Core Tradeoff
Every CTO, operations lead and managing partner building an AI plan in 2026 faces the same question: use an off-the-shelf general-purpose LLM, build a custom model on your own data, or combine the two?
General-purpose LLMs such as OpenAI's GPT-6 Astra, Anthropic's Claude Opus 5.5 and Google's Gemini 3.1 Pro and 3.8 Flash are trained on very large, broad datasets. They excel at breadth: drafting a client letter, debugging Python, summarizing a contract and analyzing a financial report in one conversation.
Custom LLMs start from a base model, often an open-weight one such as Meta's Llama 4, Mistral Large 3, OpenAI's gpt-oss-120b or Google's Gemma 4, and are fine-tuned, distilled or trained further on your own data, so they handle your terminology, formats and edge cases more consistently than a general model does.
Strictly, retrieval-augmented generation (RAG) changes the system around the model, not the model itself, but many buyers searching for a custom LLM need retrieval first, so we cover it here.
The choice is rarely binary. In our view the strongest production systems combine the two: a general model for broad tasks and reasoning, retrieval for your facts, and a tuned model only where a narrow task justifies it. The real question is where to draw the line between general and custom in your own stack.
General-Purpose LLMs: Strengths and Limitations
General-purpose large language models are the most accessible path to AI. OpenAI, Anthropic and Google each sell a full lineup through their own APIs and the major clouds, and the models work across a very wide range of tasks without customization.
The Leading General-Purpose Models in 2026
| Model | Provider | Context Window | Best For (the vendor's own positioning) | List price per 1M tokens, input / output |
|---|---|---|---|---|
| GPT-6 Astra | OpenAI | 1,050,000 tokens, up to 922,000 of them input | Complex reasoning and coding; OpenAI's suggested starting point | $10 / $50 ($20 / $75 for prompts over 272,000 tokens) |
| Claude Opus 5.5 | Anthropic | 1,000,000 tokens | Long-running agentic coding and knowledge work; Anthropic's suggested starting point | $4 / $20 |
| Gemini 3.1 Pro (preview) | 1,048,576 input tokens | Multimodal understanding, agentic work and coding | $2 / $12 for prompts up to 200,000 tokens | |
| Gemini 3.8 Flash | 1,048,576 input tokens | Long-horizon software engineering, agents and enterprise workflows | $0.75 / $3.75 through 31 December 2026, then $1.50 / $7.50 |
Sources, checked 13 October 2026: OpenAI models, OpenAI pricing, Anthropic models, Gemini models and Gemini pricing. Cheaper tiers: GPT-6.1 Sol and Claude Sonnet 5.5 list at $2 input and $10 output, and GPT-6 Luna and Claude Haiku 5.5 at $0.10 and $0.50. Above 272,000 input tokens, OpenAI's prices for these models double on input and rise 1.5 times on output (GPT-6.1 Sol goes to $4 and $15), and Haiku's price rises for prompts over 100,000 tokens. Anthropic's top tier, Claude Fable 5.1, lists at $10 input and $50 output for demanding reasoning and long-horizon agentic work, and Anthropic recommends Opus 5.5 for most workloads. For data terms, residency and agent tooling side by side, see AI giants compared: Google vs OpenAI vs Anthropic.
Strengths of General-Purpose LLMs
Why Teams Choose General-Purpose
- Zero training cost: no training data, GPU cluster or ML infrastructure needed to start.
- Fast start: an API key and a prompt produce a first result you can test against real cases.
- Broad versatility: thousands of task types without retraining.
- Continuous improvement: vendors ship better models, and retire old ones: Anthropic's deprecations page, checked 13 October 2026, retires Claude Sonnet 4.5 from its API on 30 November 2026 (Anthropic deprecations). Re-run your evaluation set on each replacement.
- Rich ecosystems: SDKs, integrations and Model Context Protocol (MCP) support at all three vendors.
- Low switching risk: another model means a re-test, not a rebuild, as long as your prompts and test cases live in your own repository.
General-purpose models are the right starting point for almost every AI initiative, and the vendors agree: Google's tuning guide says to find the best prompt before tuning, and OpenAI's fine-tuning guide says to set up evals first (Google tuning overview, OpenAI supervised fine-tuning). Prototype, test against your own cases, and customize only where a general model falls short.
Limitations of General-Purpose LLMs
Where General-Purpose Falls Short
- No proprietary knowledge: these models know nothing about your data, processes or terminology until you supply it through the prompt or retrieval.
- Data handling depends on terms and configuration: API calls send your data to the vendor. All three big vendors offer a BAA, a zero data retention path and regional processing, though not on every model, so for HIPAA, SOX or client-confidential work the job is checking terms model by model.
- Generic responses: competent, but short of the specificity domain experts expect until you add examples or retrieval.
- Cost grows with use: spend rises with every token, and reasoning tokens bill as output. The cost comparison prices a month of traffic.
- No competitive moat in the model: every competitor can call the same model. Your moat is your data, your workflow and your evaluation set.
- Hallucination risk: without grounding in your data, a model can give plausible but wrong domain answers.
These limits are not dealbreakers. For internal productivity, such as drafting emails, summarizing meetings or first drafts, a general model with little setup is usually enough. The limits matter when you need precision on your own facts, strict data control or a narrow behavior the model keeps missing.
Custom LLMs: When and Why to Build
A custom LLM is any language model adapted to your domain, data or business requirements, from lightweight fine-tuning of an existing model to training one from scratch. The common thread is that you change the model's weights, or hold them yourself, rather than only the prompt around it. The methods table starts with RAG anyway, because it is the usual first step.
Methods for Building Custom LLMs
| Method | What you pay for (list prices, 13 October 2026) | What sets the timeline | Best For |
|---|---|---|---|
| RAG (Retrieval-Augmented Generation) | Embeddings (OpenAI's text-embedding-3-small lists at $0.02 per million tokens), a vector store, and retrieved text billed as input on every call | How clean, current and permissioned your source documents are | Adding company knowledge to a general model without training |
| Fine-tuning | Training billed per token times epochs ($10 per million training tokens on Gemini 3.5 Flash, $3 on Gemini 3.1 Flash-Lite), then tuned calls at 1.5 times the base price on Gemini 3 and later, and 1.5 to 2 times on OpenAI's GPT-4.1 and GPT-4o models | Labelled examples, and an evaluation set that proves the tune beats the baseline | Adapting model behavior, format, tone and narrow domain skills |
| Knowledge Distillation | Teacher-model calls to generate training answers, then a fine-tuning run on a smaller student model; Amazon Bedrock automates both steps | How good the teacher's answers are on your prompts, and how you check them | Creating a smaller, faster model from a larger teacher model |
| Training from Scratch | Large-scale GPU compute, a corpus and a dedicated team. For scale: BloombergGPT (2023), a 50 billion parameter model trained on 569 billion tokens drawn from a corpus of 363 billion financial tokens and 345 billion general tokens | Collecting the corpus and securing the compute | Unique architecture needs, massive proprietary datasets, full control |
Sources: OpenAI pricing, Google Agent Platform pricing, Amazon Bedrock model customization and the BloombergGPT paper (Wu and others, 2023).
Reference build: illustrative, not a client engagement. A clause classifier for a law firm: a small model fine-tuned on the firm's own labelled contract clauses tags each clause against the playbook, a general model drafts the summary through retrieval over the firm's precedents, and a lawyer decides every flag. Metric to track: clauses the reviewing lawyer relabels.
Strengths of Custom LLMs
- Domain consistency: a model tuned on your labelled examples can follow your terminology, formats and edge cases more reliably than prompting alone. Google's guide says supervised tuning helps most where the language or content differs sharply from the base model's training data (Google supervised tuning). Prove the gain on your own evaluation set.
- Data privacy and compliance: a self-hosted open-weight model runs on your own hardware or cloud account, so patient records, client files and trade secrets never reach a model vendor, though a cloud host still counts as a service provider under your contracts. A tune through a vendor API runs under the vendor's terms.
- A moat, if the data is the moat: competitors cannot copy a model tuned on your data, but a newer general model can overtake it, so the durable asset is the labelled data and test cases, not the weights.
- Lower per-call cost, sometimes: OpenAI notes that a tuned model can work with shorter prompts or let a smaller, cheaper model do the task. The tuned calls themselves cost more than base calls (see the methods table), and self-hosting swaps per-token prices for GPU hours.
- Full control: with your own weights you decide when to update, what data goes in and which guardrails apply, and no vendor retires the model under you.
Limitations of Custom LLMs
- Upfront cost is mostly people and data: the vendor's training charge can be small, as the cost comparison shows, but labelling, the evaluation set and the experiments are not. Training from scratch adds large-scale compute on top.
- Time goes into data, not training: collecting, cleaning, labelling and clearing the rights to your data sets the pace far more than the training run does.
- Requires ML skills: data engineering, ML engineering to run and evaluate training, and MLOps to deploy and monitor the model. Those skills are expensive to build in-house.
- Maintenance overhead: retraining as your domain evolves, a rebuild when an API tune's base model retires, and ongoing drift detection, evaluation pipelines and data curation.
- Narrow capabilities: a model tuned for contract analysis will not write your marketing copy. You trade breadth for depth.
Custom vs General-Purpose: Head-to-Head Comparison
The matrix compares the factors that matter. Where a cell states a fact, it comes from the vendors' documentation as of 13 October 2026; where it states a judgment, it is ours.
| Factor | General-purpose LLM | Custom LLM (fine-tuned or trained) |
|---|---|---|
| Upfront work | A prompt, an API key and an evaluation set | Labelled data, training runs and an evaluation set before the first useful answer |
| Data you supply | Your documents for retrieval, if the task needs your facts | Labelled input and output pairs for a tune; a very large corpus for training from scratch |
| Accuracy on your domain | Strong on general tasks; grounded by retrieval for your facts | Can be more consistent on a narrow, stable task, if your test set shows it |
| Data privacy controls | BAA, zero data retention path and regional processing at all three big vendors, not on every model | Full control only when self-hosted; an API tune runs under the vendor's terms |
| Cost structure | Per token, rising with use | Training, then tuned calls priced above the base model, or GPU hours when self-hosted |
| When the vendor retires a model | Re-run your test set on the replacement | An API tune ends with its base model, so you retrain on a new base |
| Who can change it | You change prompts and retrieval at will; the vendor changes the model | You change everything, and you maintain everything |
| Breadth | Thousands of task types | Narrow by design |
General-purpose LLMs win on speed to a first result, cost of entry and convenience. Custom LLMs can win on consistency for a narrow task and on control when you hold the weights. Neither is universally superior.
The Decision Framework: Build, Buy, or Both?
Usually both, in order: start with a general model and a careful prompt, add retrieval when facts are missing, and build custom only where your evaluation set shows a gap that neither closes. OpenAI says to set up evals before tuning, and Google says to find the best prompt first and tune only if required.
Walk through each question to find your recommended path.
- Do you have an evaluation set? If not, build one first: real cases with known correct answers, without which no option below can be compared with another. How to evaluate AI agents shows how.
- Does a general model with a careful prompt pass it? If yes, ship that, with human approval on anything material, and stop here.
- Is the failure missing knowledge, such as policies, client facts or product data? Add retrieval and re-test.
- Is the failure behavior, such as a format, tone or narrow classification that careful prompting still misses? Fine-tune, preferably a smaller model, on data you have the right to use.
- Must the model run where no AI model vendor can see the data, or must you hold the weights? Tune an open-weight model and host it on your own hardware or cloud account.
- Do you hold a corpus on the scale of hundreds of billions of tokens, for a task no base model serves? Only then consider training from scratch.
The rule underneath: never start by building custom. Measure where general models miss your accuracy, latency or compliance bar, then customize only where your test set shows the gain. We call this validate, then specialize.
Whether to buy a product at all is a separate call, settled by the Rent-vs-Own test: rent a point tool for narrow, common work, and own a supervised agent when it touches systems of record, data or risk. Build vs buy AI agents works through it.
Reference build: illustrative, not a client engagement. An engagement-letter assistant for a CPA firm: a general model drafts each letter from the firm's approved clause library through retrieval, with no tuning at all, and a partner approves every letter before it goes out. Metric to track: clauses the partner edits before sending.
Accounting firm? See which of your workflows an agent can run end to end, which need approval and which stay human in the accounting workflow automation matrix.
Why Custom Model Projects Stall
A custom model can pass the test that justified it and still stall in production. Reasons 1 to 3 come from vendor documentation checked on 13 October 2026, reason 5 from the regulation's text, and reason 4 is our own view.
1. The base model retires under the tune. OpenAI keeps a fine-tuned model running only until its base model is deprecated, and its schedule set 23 October 2026 as the shutdown date for fine-tuned GPT-4 and GPT-4.1 nano models (OpenAI deprecations). Google set 20 October 2026 as the retirement date for its tunable Gemini 2.5 models on Agent Platform (Google model versions), and Bedrock's tuned Claude models ended with Claude 3 Haiku (reason 2). Every tune needs a plan to retrain on the next base model.
2. The tuning platform closes. OpenAI is winding down self-serve fine-tuning: it closed to organizations that had never fine-tuned on 7 May 2026, to those with no recent fine-tuned inference on 2 July 2026, and closes to new jobs for everyone on 6 January 2027. Anthropic offers no fine-tuning on its own API, and the only Claude model Amazon Bedrock let customers fine-tune, Claude 3 Haiku, reached end of life on Bedrock on 10 September 2026 (Bedrock model lifecycle). No Claude model can be fine-tuned today.
3. The newest models are not tunable. None of OpenAI's three featured models, GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna, supports fine-tuning, and Google's supervised tuning guide lists Gemini 3.5 Flash, 3.1 Flash-Lite and Gemini 2.5 models with a 20 October 2026 retirement date, not 3.8 Flash or 3.1 Pro (Google supervised tuning). A tune starts behind the newest general model.

4. Nobody built the evaluation set. Without one you cannot show that the custom model beats the general baseline, or notice when it stops doing so.
5. The data is not cleared for training. Labels, licences and consent come before any training run. For accounting firms, the Section 7216 regulations allow a use or disclosure of tax return information outside the permitted purposes only with the taxpayer's written consent, given before the use (26 CFR 301.7216-3), so check any training use against them first. Owning the model changes control, not the consent duty; Section 7216 and AI tools covers the detail. This is information, not legal advice.
Prompting vs RAG vs Fine-Tuning vs a Custom Model
Four ways to make a model fit your work, side by side on the terms that decide what you own. For the narrower choice between retrieval and tuning, see RAG vs fine-tuning.
| Approach | Cost (list prices, 13 October 2026) | Data needed | Who owns what | Lock-in |
|---|---|---|---|---|
| Prompting a general model | Tokens only, such as $2 input and $10 output per million on GPT-6.1 Sol or Claude Sonnet 5.5 | Instructions, a few worked examples and an evaluation set of real cases | You own the prompts and the evaluation set; the vendor owns the model | Low: a model retirement means a re-test, not a rebuild |
| RAG | Tokens, embeddings, a vector store, and retrieved text billed as input on every call | Your documents, current, deduplicated and permissioned per user | You own the documents, the index and the retrieval code | Moderate: a new embedding model means re-embedding the corpus; the generating model can change freely |
| Fine-tuning through a vendor | Training per token times epochs, then tuned calls above the base price (see the methods table) | Labelled input and output pairs, tens to hundreds (step 1 of the roadmap below gives the vendors' figures) | You own the training data; the tuned model stays on the vendor's platform | High: the tune lives only as long as its base model, and OpenAI's tuning platform is closing |
| A custom model on open weights, tuned or trained | GPU hours for training and serving, whether or not traffic arrives, plus the people who run it | The same labelled pairs for a tune; a very large corpus for training from scratch | You hold the weights, under the base model's licence (Apache 2.0, MIT, or Meta's Llama 4 community licence) | Lowest on any model vendor, highest on your own team, which must patch, retrain and serve it |
Sources: Google tuning overview, OpenAI pricing and model licences on Hugging Face.
Each row down gives you more control and more to maintain, and many workflows get what they need from the first two.
Reference build: illustrative, not a client engagement. A fine-tuned open-weight transaction-coding model, hosted in an accounting firm's cloud account.
What it is for: coding each client's bank-feed transactions to that client's chart of accounts, tuned only if evals show a prompted general model with retrieval miscodes them.
What Gaper would build: a parameter-efficient (LoRA) fine-tune of an open-weight model such as gpt-oss-20b, which OpenAI's 2025 Hugging Face model card positions for local or specialized use cases, served with vLLM on a GPU in the firm's account, so ledgers never reach a model vendor, though the cloud host and Gaper still count as service providers.
Data it needs: past transactions paired with the reviewer-confirmed account, deduplicated and cleared for training under the firm's engagement terms and, where any of it is tax return information, Section 7216 (reason 5 above).
How evals gate it: the tune goes live only if it beats the prompted general model with retrieval on a test set of reviewed transactions it never trained on, and every retrain or new base model is retested.
Gaper Ownership Map: the model drafts each code and a bookkeeper approves it before anything posts (Agent-drafted, human-approved); month-end close and client advice stay Human-owned.
What the firm owns: the code, runbook and audit log. It holds the tuned weights under the base model's Apache 2.0 license, and the training and evaluation sets under its clients' terms.
Measure it on: the share of suggested codes the bookkeeper changes before posting.
Cost Comparison: Custom vs General-Purpose LLMs
The two sides bill differently: a general model by the token, a custom one by training, tuned calls and the people who keep it alive. The figures below are our arithmetic at list prices checked on 13 October 2026, with no caching, batch, regional or long-prompt adjustments; check the vendor's page before committing.
A month of general-purpose traffic: 10 million tokens a day, about 300 million a month, 80 percent input and 20 percent output.
| Model | Monthly token cost at list price |
|---|---|
| OpenAI GPT-6 Astra | $5,400 |
| Anthropic Claude Opus 5.5 | $2,160 |
| OpenAI GPT-6.1 Sol or Anthropic Claude Sonnet 5.5 | $1,080 |
| Google Gemini 3.8 Flash | $405 through 31 December 2026, then $810 |
| OpenAI GPT-6 Luna or Anthropic Claude Haiku 5.5 | $54 |
Token counts for the same text differ by vendor; Anthropic says the tokenizer in Claude 4.7 and later produces about 30 percent more tokens than its earlier one, so count tokens on a sample of your own prompts before comparing (Anthropic pricing).
One fine-tuning run: 2,000 labelled examples of 1,500 tokens each, trained for 3 epochs, is 9 million training tokens.
| Where you tune | Training charge at list price |
|---|---|
| Gemini 3.1 Flash-Lite on Google's Agent Platform | $27 |
| Llama 4 Scout on Google's Agent Platform (managed tuning) | $51.93 |
| Gemini 3.5 Flash on Google's Agent Platform | $90 |
| GPT-4.1 on OpenAI (existing fine-tuning customers only, until 6 January 2027) | $225 |
Two things stand out. The training charge is the small number next to the labelled data, the evaluation set and the retraining every time a base model retires. And a tuned model is not automatically cheaper to run, because tuned calls cost more than base calls; the saving comes only from moving the task to a smaller model or a much shorter prompt.
Self-hosting changes the bill again. OpenAI says gpt-oss-120b fits on a single H100 GPU (OpenAI), so a self-hosted model's floor is that GPU, paid around the clock whether or not traffic arrives, plus the engineers who keep it patched and served.
The cost that is easiest to underestimate is maintenance: ongoing data curation, retraining whenever drift or a base model retirement demands it, evaluation pipelines, monitoring, and someone accountable for all of it.
How to Build a Custom LLM in 2026
If a custom model is worth the investment, here is the roadmap. The steps are the same for fine-tuning and for training from scratch; only the scale differs.
1. Data Preparation and Curation
This is the most important step, and the easiest to underestimate. Collect, clean, deduplicate and label your domain data, and confirm you have the right to train on it. You may need fewer examples than you expect: OpenAI requires at least 10 for supervised fine-tuning, reports improvements from 50 to 100, and advises rethinking the task or prompt if 50 good examples change nothing (OpenAI supervised fine-tuning). Google suggests 100 or more for Gemini, and stresses quality over quantity and examples that match what the model will see in production. Training from scratch needs far more, as the BloombergGPT row in the methods table shows.
2. Base Model Selection
Choose your foundation. Open-weight options on Hugging Face on 13 October 2026 include Meta's Llama 4 Scout and Maverick, under Meta's community licence, which requires a separate licence from Meta for any licensee that had more than 700 million monthly active users when Llama 4 was released, and puts "Llama" at the start of any distributed model tuned from them; OpenAI's gpt-oss-120b and gpt-oss-20b, Google's Gemma 4, and Mistral Large 3 and Mistral Small 4, all under Apache 2.0; and DeepSeek V4.1 Flash under MIT. Through a vendor, Google's tuning guide lists Gemini 3.5 Flash (supported until at least 19 May 2027) and 3.1 Flash-Lite (until at least 7 May 2027) on its Agent Platform; the Gemini 2.5 models it also lists have a 20 October 2026 retirement date on the platform (Google model versions). OpenAI tunes GPT-4.1 and GPT-4o models for active existing fine-tuning customers only, and Anthropic offers no tuning on its own API. Self-hosting gives you full control but needs GPU infrastructure; API tuning is simpler but ties the model to the vendor's platform and lifecycle.
3. Fine-Tuning or Training
For tuning, parameter-efficient methods change only a small part of the model. LoRA cut trainable parameters by 10,000 times and GPU memory by 3 times against full fine-tuning of GPT-3 175B (Hu and others, 2021), and QLoRA fine-tuned a 65 billion parameter model on a single 48GB GPU (Dettmers and others, 2023). Google's managed Gemini tuning is adapter-based too, with an adapter size you choose. Training from scratch needs multi-GPU clusters. Judge every run against your evaluation set.
4. Evaluation and Benchmarking
Build a test set from real cases with known correct answers, large enough that a difference you care about shows up. Measure accuracy, latency, hallucination rate and edge-case handling against the general-purpose baseline. If the custom model does not clearly win on your domain tasks, the investment is not justified; go back to step 1 and improve the training data.
5. Deployment and Infrastructure
Deploy to a managed service such as Amazon Bedrock or Google's Gemini Enterprise Agent Platform (the new name for Vertex AI), or to a self-hosted inference server such as vLLM. Configure autoscaling, rate limits and access control, and set a fallback route to a general-purpose model you have already evaluated, in case the custom model goes down.
6. Monitoring and Continuous Improvement
Production is the beginning, not the end. Detect drift, log inputs and outputs within your retention policy, and alert on latency spikes, accuracy drops and error rates. Retrain when your evals or drift monitoring say so, and whenever the base model retires.
Timeline summary: Timelines depend on the integrations and approvals the workflow needs, so they are scoped up front.
Gaper Builds Both Custom and Hybrid AI Solutions
Choosing between custom and general-purpose is half the challenge; the other half is building something that survives production. Gaper builds supervised AI agents inside your systems, with human approval on anything material, and you own what we build. We build on OpenAI, Claude, Gemini or the right model for the job, and choose by your evaluation set rather than a vendor preference.
Our designs start with a general model and retrieval, and add a tuned model only for a narrow step where the evaluation set shows it earns its place. AccountsGPT, our example accounting agent, is built the same way: it reads invoices and statements, reconciles transactions and drafts reports on the model that fits the job, with a human approving anything that posts.
Every design starts from the Gaper Ownership Map, which places each workflow step in one of three tiers: Automated; Agent-drafted, human-approved; or Human-owned, where the agent never runs it alone. If a Chief AI Officer owns your model choices, the map shows which steps a tuned model may draft and which a person still approves.
The Gaper Method: Assess, Scope, Build, Supervise, Hand Over
The method is the same whether the answer turns out to be a prompt, retrieval or a tuned model, and it runs on one workflow at a time.
- Assess: a free AI assessment to find the workflow with the most leverage and the one metric that proves it worked, and to say plainly if a product you can buy already does the job.
- Scope: place every step on the Ownership Map, make the Rent-vs-Own call, and choose prompting, retrieval or a tune against an evaluation set.
- Build: a Gaper engineer embeds with your team, forward-deployed, and builds the agent in your repo and your cloud, with evals, guardrails, connectors to your systems and human approval on risky actions.
- Supervise: the agent runs in supervised production with approval gates, confidence thresholds and an audit log, and a named owner on your side reviews the exceptions.
- Hand over: you receive the code, prompts, evaluation set and runbook, and the audit trail stays in your systems. Your team runs it, or we operate it under an agreed SLA.
Ready to test the general model first? Get a prompt, retrieval or tune recommendation for one workflow.
When should a business choose a custom LLM over a general-purpose one?
Choose a custom LLM only when your evaluation set shows a gap that prompting and retrieval cannot close, such as a narrow format or classification task, or when the model must run where no model vendor sees the data. Otherwise a general-purpose model with RAG is cheaper to run, easier to change and simpler to maintain.
What are the main methods for building a custom LLM and what do they cost?
Four: RAG, fine-tuning, knowledge distillation and training from scratch. At list prices on 13 October 2026, RAG adds embeddings from $0.02 per million tokens, tuning Gemini 3.5 Flash costs $10 per million training tokens, and training from scratch is a compute and data project few firms need.
Is fine-tuning better than RAG?
They solve different problems. Fine-tuning changes how a model behaves, its format, tone and narrow skills, while RAG changes what it knows by retrieving your documents at query time. Use RAG for missing facts, fine-tuning for behavior that careful prompting cannot fix, and both when you need each.
Should startups build custom LLMs?
Usually not at first. Start with a general model through an API, build an evaluation set, add RAG for your own knowledge, and tune only when your logs show a narrow task a smaller tuned model handles as well for less. Keep the model behind an adapter so you can switch vendors.
How much does a custom LLM cost?
The vendor charge can be small: a 9 million token tuning run lists at $90 on Gemini 3.5 Flash. The real costs are labelled data, the evaluation set, tuned calls priced above the base model, and retraining whenever the base model retires. Training from scratch costs far more.
Can I fine-tune GPT-4 or Claude?
Not for a new project. OpenAI set 23 October 2026 as the shutdown date for GPT-4, and as of 13 October 2026 it takes no new fine-tuning customers and closes tuning to all new jobs on 6 January 2027. Anthropic offers no fine-tuning on its own API, and Bedrock's only tunable Claude, Claude 3 Haiku, reached end of life there on 10 September 2026.
Google still tunes Gemini 3.5 Flash. For a tuned model you can keep, tune open weights such as gpt-oss, Gemma 4, Mistral Small 4 or DeepSeek V4.1 Flash and host them yourself.
How long does it take to build a custom LLM?
Timelines depend on the integrations and approvals the workflow needs, so they are scoped up front. For a custom model the biggest variable is data: a clean, labelled, permissioned dataset and an evaluation set move a project along faster than any choice of base model.
What data do I need for a custom LLM?
For RAG, the documents themselves, current and permissioned. For fine-tuning, labelled input and output pairs: OpenAI requires at least 10 and sees gains from 50 to 100, and Google suggests 100 or more. Training a model the size of BloombergGPT from scratch took a corpus of hundreds of billions of tokens.
Who can help me build a custom LLM?
An in-house ML team, a consultancy or an AI implementation partner. Gaper builds supervised agents on the model that passes your evaluation set, adds a tuned model only when the data justifies it, and hands over the code, prompts, evaluation set and runbook so you own what runs.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
When should a business choose a custom LLM over a general-purpose one?
What are the main methods for building a custom LLM and what do they cost?
Is fine-tuning better than RAG?
Should startups build custom LLMs?
How much does a custom LLM cost?
Can I fine-tune GPT-4 or Claude?
How long does it take to build a custom LLM?
What data do I need for a custom LLM?
Who can help me build a custom LLM?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.