
The Impact of Large Language Models on Business (2026): Use Cases That Reached Production
LLMs in business in 2026: production examples from Kaiser, Morgan Stanley, Klarna, A&O and Walmart, current model prices, real costs and a phased rollout plan.
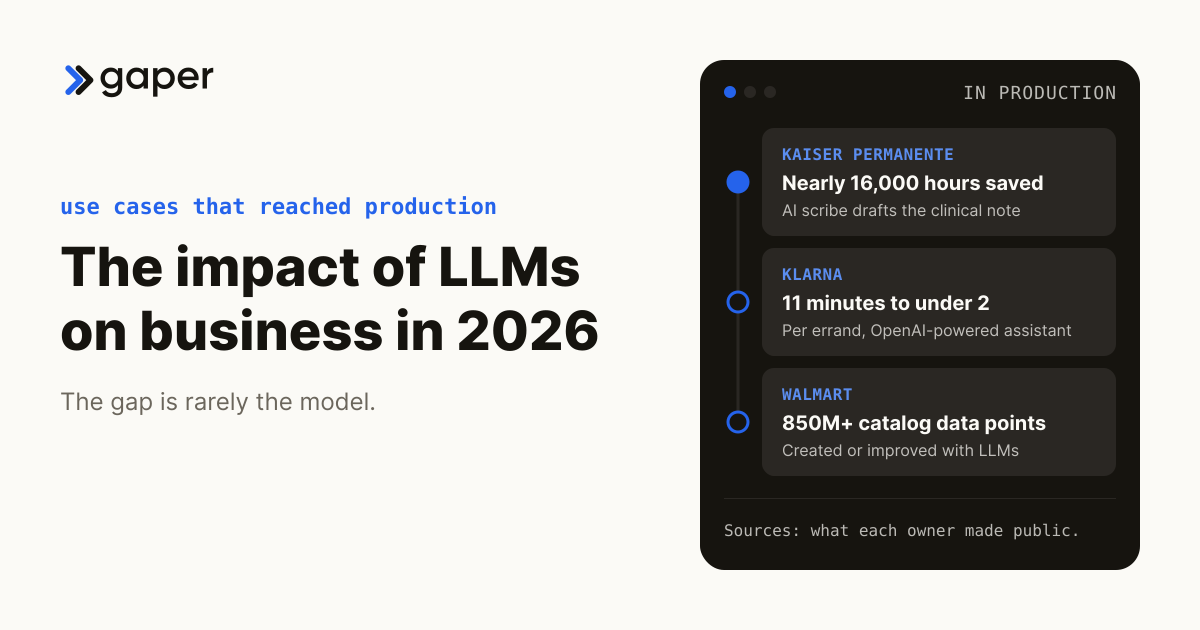
Large language models now run inside real workflows: clinical notes at Kaiser Permanente, advisor research at Morgan Stanley, support chats at Klarna, legal work at A&O Shearman and product data at Walmart. Use is almost universal, yet in McKinsey's 2026 survey only 37% of respondents attribute any EBIT impact to AI. The gap is rarely the model; it is the workflow, the data and the review step built around it.
TL;DR: 5 Key Takeaways
- Enterprise Adoption: Large language models are transforming enterprise operations by automating complex tasks, with 71% of organizations regularly using generative AI (McKinsey, March 2025).
- Measurable ROI: Named deployments publish real numbers: Kaiser Permanente physicians saved nearly 16,000 documentation hours with an AI scribe, and Klarna cut support errand time from 11 minutes to under 2. Yet only 6% of McKinsey's respondents are AI high performers.
- Critical Success Factors: Enterprise LLM implementation requires careful attention to data privacy, legacy system integration, and hallucination mitigation.
- Strategic Selection: Choosing the right architecture (proprietary vs. open-source) depends on your use case, budget, and compliance requirements. List prices run from $0.10 to $10 per million input tokens.
- Phased Roadmap: Building successful LLM solutions involves experimentation, pilot projects, capability building, and partnerships with expert implementation teams.
Table of Contents
- Understanding Large Language Models in Business Context
- Real-World LLM Use Cases Across Industries
- Customer Service and Support Automation
- Content Generation and Marketing at Scale
- Enterprise Implementation Challenges
- ROI and Business Impact Metrics
- Building Your LLM Implementation Roadmap
- LLMs for Startups: Smaller Budgets, Same Rules
- How Gaper.io Builds Enterprise LLM Solutions
- Questions, Answered
Ready to unlock AI-driven business value?
Get expert guidance on LLM implementation tailored to your enterprise.
Understanding Large Language Models in Business Context
What are LLMs?
Large language models are artificial intelligence systems trained on vast amounts of text data to understand and generate human language. Unlike earlier chatbots or search algorithms, modern LLMs can work through problems they were never explicitly trained to solve.
The key insight that separates modern LLMs from previous generations: these systems develop internal representations of concepts, relationships, and patterns across countless domains. When you feed an LLM a question about medical billing, historical analysis, or software architecture, the model draws on its learned understanding of language, logic, and domain-specific patterns to generate contextually appropriate responses.
The business conversation started with BERT (2018) and GPT-3 (2020, 175 billion parameters). In November 2026 the flagships are OpenAI's GPT-6 Astra, Anthropic's Claude Opus 5.5 and Fable 5.1, and Google's Gemini 4 Argon, with open-weight models such as Meta's Muse Spark Open for teams that run the model themselves.
For business purposes, this means you can deploy a single LLM architecture across dozens of use cases, customizing behavior through prompt engineering, retrieval from your own documents, integration with your proprietary data and workflows, and, less often, fine-tuning.
Capability is still climbing: the Stanford AI Index 2026 reports agent success on the OSWorld computer-use benchmark rising from about 12% to about 66%, against a 72.35% human baseline. Roughly one task in three still fails, so production systems keep a person on the approval step.
Moving from Research to Business
The gap between academic demonstrations and production deployment remains substantial. Research papers showcase LLMs handling complex tasks with impressive accuracy rates. But enterprise deployment introduces real-world constraints: latency requirements, cost sensitivity, regulatory compliance, integration with legacy systems, and the need for explainability and auditability.
The organizations succeeding with enterprise LLMs share a common characteristic: they treat LLM implementation as an operational problem, not merely a technology problem. This means combining machine learning expertise with domain knowledge, integrating with existing workflows and systems, and building governance structures that protect against failure modes unique to generative AI.
McKinsey's surveys show the gap. In 2025, 88% of 1,993 participants said their organizations regularly use AI in at least one function, but roughly two-thirds had not begun scaling it. In The state of AI in 2026 (1,719 respondents, published 25 August 2026), 37% attribute at least some EBIT impact to AI, about the same as a year earlier, and only 6% are high performers who attribute 5% or more of EBIT to AI. The infrastructure matters less than the organizational structure supporting it.
Economics of Deployment
The financial case for enterprise LLMs has improved dramatically. Three years ago, deploying LLMs required significant capital investment and ongoing operational costs that only the largest enterprises could justify. Today, the economics have shifted.
Cloud-based LLM APIs have made deployment accessible to organizations of all sizes. The Stanford AI Index 2025 found that the inference cost of a system performing at GPT-3.5's level dropped more than 280-fold between November 2022 and October 2024. In November 2026 the small, fast models list at about $0.10 per million input tokens (Claude Haiku 5.5, GPT-6 Luna) and the top reasoning models at $10 (GPT-6 Astra, Claude Fable 5.1).
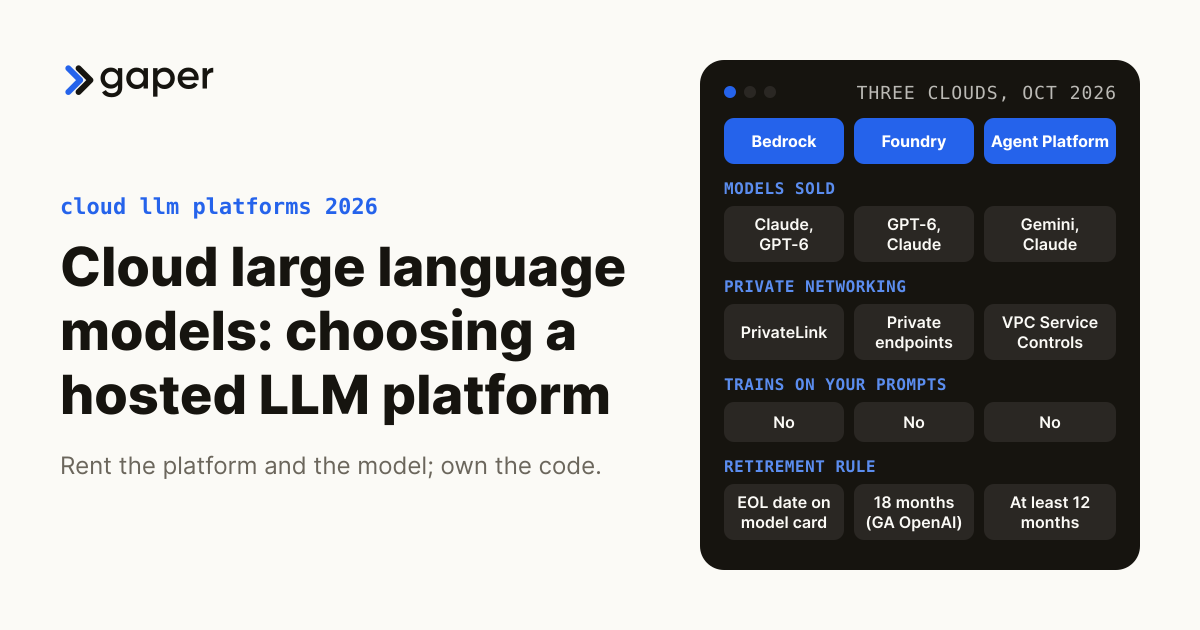
Cheap tokens do not make cost disappear: about 20% of McKinsey's 2026 respondents said AI operating costs, including tokens, had constrained their use, since reasoning models bill their thinking as output and agents loop through many calls. Our review of cloud-hosted large language models covers the infrastructure side.
This democratization has enabled mid-market enterprises to build sophisticated AI-powered applications that were previously feasible only for technology giants. The economics now favor rapid experimentation and iterative improvement rather than massive upfront planning.
Key Insight: The combination of improved economics and cloud accessibility means mid-market enterprises can now compete with tech giants in AI implementation capabilities.
Real-World LLM Use Cases Across Industries
Each industry below names one production deployment and what its owner has made public.

Healthcare
Healthcare institutions see the clearest LLM returns in administrative work.
Administrative automation represents the fastest return on investment. LLMs process clinical notes, extract relevant information, and prepare documentation for billing. They identify missing data points in patient records and flag records requiring human review.
Production example: Kaiser Permanente. The Permanente Medical Group in Northern California rolled out an ambient AI scribe that listens to the visit and drafts the clinical note for the physician to review. From October 2023 to December 2024, 7,260 physicians used it in 2,576,627 patient encounters and saved nearly 16,000 hours of documentation time, and 88% of surveyed physicians reported a positive effect on visits (Kaiser Permanente Division of Research, on its NEJM Catalyst study).
Clinical decision support represents the highest-value use case but requires the most rigorous validation and governance. In a randomized trial in JAMA Network Open (October 2024), 50 physicians given GPT-4 scored a median 76% on diagnostic reasoning against 74% without it, a difference that was not statistically significant. A model next to a clinician does not help on its own; the workflow has to be designed around it, with the clinician keeping final decision authority.
Financial Services
Banks and financial institutions face intense competitive pressure from fintech companies that are aggressively adopting LLMs. Traditional financial institutions are responding with rapid deployment across multiple functions.
Production example: Morgan Stanley. Morgan Stanley Wealth Management rolled out the AI @ Morgan Stanley Assistant, built with OpenAI, in September 2023 to answer advisors' questions from the firm's own research. By June 2024, 98% of Financial Advisor teams had adopted it, and the firm added Debrief, which takes meeting notes and drafts the follow-up (Morgan Stanley). The firm has not published a cost or revenue figure for either tool.
Regulatory compliance and risk assessment are prime use cases. LLMs analyze regulatory updates, corporate policies, and transaction patterns to identify compliance violations and suspicious activity. They process enormous volumes of unstructured text that human analysts could never review manually.
Loan underwriting and credit assessment benefit from LLMs' ability to synthesize information from thousands of data points and documents. They extract relevant financial metrics from borrower documents, assess risk factors, and prepare underwriting recommendations, while the credit decision stays with a person. Our guide to LLM-automated loan processing walks through that pipeline.
The same shift hits the mid-market through tools like AccountsGPT, which is one of Gaper's four packaged agents handling bookkeeping reconciliation, AP/AR matching, and audit-prep workpapers.
Business Impact: In finance the public numbers are adoption figures, not savings, so test any vendor's cost-reduction claim on your own workflow.
Customer Service
Customer service and support automation represents the highest-volume, most tangible impact of LLM deployment today.
Production example: Klarna. Klarna's OpenAI-powered assistant handled two-thirds of its customer service chats in its first month (Klarna, 27 February 2024). Errands took under 2 minutes instead of 11, repeat inquiries dropped 25%, and Klarna projected a $40 million profit improvement for 2024 (Klarna). In May 2025 its CEO told Bloomberg Klarna was hiring human support staff again so customers always have a person if they want one (Entrepreneur, citing Bloomberg).
Modern support assistants aren't simple keyword-matching chatbots; they understand customer intent, synthesize information from knowledge bases, and generate contextually appropriate responses. LLM-powered support systems provide 24/7 availability, respond instantly to customer inquiries, and maintain consistent response quality regardless of agent training or fatigue.
The most sophisticated implementations use LLMs to handle routine requests while intelligently routing complex issues to human agents. These hybrid systems maintain quality while maximizing automation, resulting in faster resolution times and reduced agent burnout from repetitive tasks.
Legal
Legal departments face an information overload problem that LLMs are uniquely positioned to solve. Legal research, contract analysis, and compliance review require reviewing thousands of documents while maintaining perfect accuracy.
Production example: A&O Shearman (then Allen & Overy). In February 2023 the firm rolled out Harvey, a platform built on OpenAI models enhanced for legal work, to more than 3,500 lawyers across 43 offices; in the trial before launch, around 3,500 of its lawyers had asked Harvey about 40,000 queries in their client work (A&O Shearman). We found no independent measurement of review time at a named firm; the time-saving figures come from vendors.
Due diligence acceleration represents a massive value unlock for legal firms and in-house counsel. M&A transactions require reviewing thousands of documents, identifying key provisions, flagging risks, and summarizing findings. LLMs perform this initial review automatically, surfacing documents requiring attorney review and highlighting key clauses and provisions.
Marketing
Marketing teams are deploying LLMs to scale content production, personalize customer communications, and improve campaign performance.
Production example: Walmart. On its August 2024 earnings call, CEO Doug McMillon said Walmart had used multiple large language models to create or improve over 850 million pieces of product catalog data, work he said would otherwise have needed nearly 100 times the current team to finish in the same time (Motley Fool transcript).
Campaign personalization and dynamic content are the other big use case. LLMs generate personalized email messages, product recommendations, and content variations tailored to individual customer preferences and behaviors. Published lift figures here are vendor case studies, so measure yours against a control group.
Engineering
Engineering teams building software products are deploying LLMs to accelerate development velocity and improve code quality.
Production evidence: surveys and trials. In the 2026 Stack Overflow Developer Survey (30,000+ respondents), 73% of AI coding tool users use them daily, and Claude Code and GitHub Copilot were the most used agents (Stack Overflow).
The speed evidence is mixed: developers finished one task 55% faster with Copilot in GitHub's 2022 experiment, while METR's early-2025 trial found experienced open-source developers 19% slower with AI tools; METR's February 2026 update leans toward a speedup but calls its data unreliable (METR).
But the impact extends beyond code generation. LLMs assist with code review by identifying potential bugs, security vulnerabilities, and performance issues. They generate documentation, create test cases, and help developers understand unfamiliar codebases.
| Industry | Primary Use Case | Named production example and public result | LLM Options (Nov 2026) |
|---|---|---|---|
| Healthcare | Administrative automation, clinical decision support | Kaiser Permanente AI scribe: nearly 16,000 hours saved | Claude, GPT-6, Gemini, healthcare models |
| Finance | Compliance, risk assessment, underwriting | Morgan Stanley advisor assistant: 98% of FA teams adopted | GPT-6, Claude, open-weight for sensitive data |
| Customer Service | Support automation, routing, personalization | Klarna: two-thirds of chats, errands 11 minutes to under 2 | Small fast models (Haiku 5.5, GPT-6 Luna, Flash-Lite) |
| Legal | Contract review, due diligence, research | A&O Shearman with Harvey: 3,500+ lawyers, 43 offices | Claude, GPT-6, specialized legal platforms |
| Marketing | Content generation, personalization, analytics | Walmart: 850M+ catalog data points | GPT-6, Claude, Gemini |
| Engineering | Code generation, review, documentation | 73% of AI coding tool users use them daily | Claude Code, Copilot, Codex |
Customer Service and Support Automation
Customer service represents the most mature enterprise LLM application today, with thousands of organizations generating measurable value at scale.
Traditional customer support models face inherent constraints: human agents can handle one conversation at a time, customer satisfaction varies based on agent expertise and mood, and 24/7 support requires expensive staffing across multiple time zones. LLM-powered support systems remove most of these limits for routine questions.
The implementation approach matters significantly. Simple rule-based chatbots produce frustration and customer churn. Effective LLM-powered support systems require substantial investment in knowledge base quality, training data, and prompt engineering to ensure responses are accurate, helpful, and appropriately scoped.
Organizations implementing LLM support successfully combine several approaches. First, they invest in knowledge base quality, ensuring the LLM has access to accurate, current, and comprehensive information. Second, they implement confidence thresholds that route uncertain responses to human agents rather than risk providing incorrect information. Third, they continuously monitor performance, collecting feedback from customer interactions and retraining models to improve accuracy and relevance. Our piece on regulatory compliance for chatbot LLMs covers the rules the bot has to prove it followed.
The model bill is usually the smallest line. At 50,000 conversations a month, with about 3,000 input and 400 output tokens each, November 2026 list prices come to about $25 a month on GPT-6 Luna, $500 on Claude Sonnet 5.5 and $2,500 on GPT-6 Astra. The real costs are the knowledge base, the integrations, the evaluation set and the people who handle what the bot cannot.
Gaper's own delivery numbers show where the money moves in a large rollout. For a 1,500-agent contact center, deflection alone accounts for more than half the savings. The faster-handle-time bucket is the next contributor, since agents who stay on staff still resolve cases more quickly when the model drafts their replies. Quality-assurance automation and training cuts are smaller but meaningful, especially for compliance-regulated operations. The new-cost line, often surprising to first-time operators, captures inference tokens, retrieval-infrastructure spend, and ML-engineering headcount. It typically lands between three and six percent of the gross savings, which is why the net payback period for a well-scoped rollout is under a year. Composite figures based on three anonymized 2025 deployments by Gaper-staffed engineering teams.
Content Generation and Marketing at Scale
Content represents a critical asset in modern business, yet the traditional model of human-written content has fundamental constraints: content creation is expensive, time-intensive, and difficult to scale.
LLMs enable organizations to generate large volumes of high-quality content while maintaining human oversight and editorial control. This doesn't mean replacing human writers with automated systems; rather, it means amplifying human creativity and productivity.
The most effective content generation approaches combine LLM automation with human expertise. LLMs generate drafts, outlines, and variation ideas that human editors review, refine, and customize. This division of labor lets human writers focus on strategy, creativity, and quality while LLMs handle routine content assembly and variation generation.
Email marketing represents a particularly high-impact use case. LLMs generate personalized email variations tailored to customer segments, past purchase behavior, and inferred preferences. Test each variation against a holdout group.
The critical success factor: human oversight remains essential. LLM-generated content occasionally contains inaccuracies, outdated information, or inappropriate tone. Effective content generation strategies include human review checkpoints, style guides that guide LLM behavior, and feedback loops that improve model performance over time. The EU AI Act's transparency duties for AI-generated content apply from 2 August 2026.
Takeaway: LLM-powered content generation works best as a human-AI partnership where LLMs handle drafting and variation while humans provide strategy and oversight.
Enterprise Implementation Challenges
Despite the compelling business case, enterprise LLM implementation faces significant technical and organizational hurdles. Understanding and mitigating these challenges separates successful deployments from failed pilots.
Data Privacy and Security
LLM systems must protect sensitive business data while generating value from it. This creates a fundamental tension: LLMs require data to function effectively, but exposing sensitive data to external systems introduces privacy and security risks.
Organizations addressing this challenge employ several approaches. First, they use on-premises, private cloud or regional cloud deployments rather than default public APIs when the data demands it, keeping control over sensitive data. Second, they implement data anonymization and redaction techniques that remove personally identifiable information before sending data to external systems. Third, they negotiate data processing agreements with LLM providers that guarantee data is not used for model training or retained longer than necessary.
Bias and the law sit next to privacy: skewed training data can treat some customers unfairly, and the GDPR and CCPA regulate personal data and fine breaches. The EU AI Act's obligations for high-risk systems in Annex III, such as hiring and credit scoring, apply from 2 December 2027 (Regulation (EU) 2026/1744). In the US, the 2023 AI executive order (EO 14110) was revoked on 20 January 2025. See our guide to ethical considerations in LLM development.
A Gartner survey of 353 data and AI leaders (published April 2026) found that organizations with successful AI initiatives invest up to four times more, as a share of revenue, in data quality, governance, people and change management. Data governance isn't optional; it's foundational to enterprise LLM success.
Legacy System Integration
Most enterprises operate complex ecosystems of legacy systems built over decades. Integrating LLMs with these systems represents a significant technical challenge.
Legacy systems often lack APIs or have limited programmatic interfaces. LLMs sometimes require real-time access to data stored in these systems to generate useful recommendations or decisions. Organizations solve this challenge through API development, data pipeline creation, and careful system orchestration.
Training Costs and Model Evaluation
Fine-tuning and training LLMs for specific use cases involves significant costs in computation, data preparation, and expert time.
Organizations need to carefully evaluate which use cases justify fine-tuning custom models versus using pre-trained models with prompt engineering and retrieval. OpenAI's documentation sets a minimum of 10 examples, recommends starting with 50 well-crafted ones and says to invest in fine-tuning only after evals are in place. It also says OpenAI is winding down its fine-tuning platform: it is closed to new users, and eligible existing customers can create training jobs until 6 January 2027 (OpenAI).
Evaluation is where the effort belongs. Perplexity (how well a model predicts the next word) helps in training but says little about a business task, so production teams score outputs on a fixed set of real cases with known good answers, plus human review.
Hallucination Mitigation
LLMs occasionally generate confident-sounding but completely false information. This "hallucination" problem is particularly dangerous in high-stakes domains like healthcare, finance, and legal.
Effective mitigation strategies include implementing confidence thresholds that route low-confidence responses to human review, grounding LLM responses in retrieved documents and data rather than relying on training data, and building feedback loops where human corrections improve model behavior over time.
Organizations implementing production LLM systems treat hallucination as a managed risk, not a solved problem, through rigorous governance. Red-teaming exercises identify failure modes, confidence thresholds prevent high-risk recommendations, and human oversight catches inevitable mistakes.
Transform your business with AI agents and expert engineering
See how Gaper's platform and engineering team enable rapid LLM implementation.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
ROI and Business Impact Metrics
Organizations measuring LLM implementation success should focus on business metrics rather than technical metrics. Accuracy on benchmarks matters less than impact on actual business outcomes.
| Use Case | Primary Metrics | What a named deployment has published |
|---|---|---|
| Customer Service | Cost/interaction, resolution rate, CSAT | Klarna: errands 11 minutes to under 2, repeat inquiries down 25% (2024) |
| Content Generation | Content cost, engagement metrics | Walmart: 850M+ catalog data points created or improved (2024) |
| Legal Review | Cost/document, accuracy | A&O: about 40,000 queries from about 3,500 lawyers in trial (2023) |
| Healthcare Admin | Documentation time, note quality | Kaiser Permanente: nearly 16,000 hours saved, Oct 2023 to Dec 2024 |
| Sales Forecasting | Forecast accuracy, pipeline visibility | No named, independently measured result is public |
| Software Development | Velocity, code quality | Mixed: 55% faster on one task (GitHub 2022), 19% slower (METR 2025) |
| Compliance & Risk | Violations detected, review time | Morgan Stanley: 98% advisor-team adoption; no cost figure published |
A sector view that combines public sources with Gaper engagement data gives a second lens. Representative production LLM workloads by sector, 2026.
| Sector | Flagship Use Case | Median Cycle-Time Cut |
|---|---|---|
| Developer Tools | In-IDE assistant for code, tests, review | 55 percent |
| Customer Ops | Tier-1 deflection plus agent assist | 41 percent |
| Finance Ops | Document extraction and reconciliation | 36 percent |
| Healthcare Admin | In-basket reply drafts and prior-auth letters | 28 percent |
| Content Production | First-draft copy and structured summaries | 23 percent |
Sources: GitHub Octoverse 2026, Klarna Q4 2025 earnings, Bloomberg Intelligence Banking AI Index, Epic Systems internal pilots, Gaper engagement data.
Successful organizations measure cumulative impact across multiple projects rather than viewing each implementation in isolation, because each one leaves reusable connectors and evaluation sets behind.
Pro Tip: Start with high-ROI, low-complexity use cases to build organizational momentum and expertise before tackling more complex implementations.
Building Your LLM Implementation Roadmap
Successful enterprise LLM deployment requires a phased approach that builds organizational capability while generating near-term business value.
Phase 1: Foundation and Experimentation (Months 1-3)
Identify high-impact use cases where LLMs can generate measurable business value. This isn't about finding the easiest problem to solve; it's about finding problems where LLM capabilities create unique value. Allocate dedicated resources to LLM exploration and experimentation. Select a small cross-functional team including business stakeholders, technical experts, and domain specialists. Evaluate multiple LLM options through proofs-of-concept, scored on a test set built from your own cases.
Phase 2: Pilot Implementation and Learning (Months 4-8)
Deploy LLM solutions to production for selected use cases, but in controlled environments. Implement rigorous monitoring and measurement to quantify business impact. Develop governance frameworks and quality control processes. Build internal expertise through training and knowledge sharing. Document learnings and establish reusable patterns.
Phase 3: Scale and Optimization (Months 9-15)
Expand LLM deployment across additional use cases and business units. Invest in platform infrastructure that enables efficient deployment of new LLM applications. Mature governance and control frameworks. Transition from vendor-provided support to internal capability.
Phase 4: Continuous Improvement (Ongoing)
Implement feedback loops that improve model performance. Monitor for emerging risks or compliance issues. Evaluate new LLM technologies and incorporate improvements; vendors retire models on published dates, so plan for at least one migration a year. Expand application scope as organizational capability matures.
Organizations following this roadmap consistently deliver better results than organizations attempting massive, company-wide LLM deployments without adequate planning or governance.
LLMs for Startups: Smaller Budgets, Same Rules
Startups feel LLMs from both sides: a small team can cover drafting, support and code, but big platforms can copy features overnight.
Three companies show the range: Textio has built AI for HR since 2014 and sells AI for recruiting and performance feedback; Cohere builds enterprise models (Command) and the North agent platform; Gong sells a revenue AI platform that reads sales calls.
The financial case is simple: LLMs automate tasks, reduce overheads and scale without the quality falling. The risks hit harder on a short runway:
- The data dilemma. Biased or inaccurate data skews results.
- The money pitfall. Prove the workflow on 50 real examples before you spend on scale.
- Reputation. One confidently wrong answer to a customer spends hard-won trust.
- Viability. A product built on a misbehaving model goes down with it; keep the model swappable.
In Gaper's podcast conversation with Jon Nordmark on AI and LLM solutions for enterprises, the episode notes describe generative AI as "an everyday tool for everyone from middle school kids to professionals in senior roles". The winners make that tool reliable inside one workflow first.
How Gaper.io Builds Enterprise LLM Solutions
For organizations navigating the complexity of enterprise LLM implementation, expert guidance accelerates results while reducing risk.
Gaper.io is an AI-native implementation partner that builds and deploys production AI agents for business operations. Founded in 2019 and backed by Harvard and Stanford alumni, Gaper offers four named AI agents (Kelly for healthcare scheduling, AccountsGPT for accounting, James for HR recruiting, Stefan for marketing operations) plus on demand engineering teams, and the systems it ships belong to the client.
Gaper is the AI-native implementation partner that deploys supervised AI agents you own.
Gaper's approach combines ready-built AI agents for common enterprise workflows with hands-on engineering for custom LLM development. Organizations can deploy Kelly to automate healthcare scheduling immediately, or engage Gaper's engineering teams to build specialized LLM applications aligned with unique business requirements.
The engineering teams at Gaper understand not just LLM technology, but the organizational and operational challenges of enterprise deployment. They assist with use case identification, architecture design, governance framework development, and ongoing optimization.
Gaper's view of what works comes from its own delivery record: a Gaper analysis of 41 deployments, the contact-center composite above, and three sector case studies. Composite case studies based on three Gaper engineering placements between Feb and Dec 2025. Numbers anonymized but accurate within 5 percent.
Understand how AI agents and expert engineering can transform your business operations.
Free assessment. No commitment.
| Figure | What it measures |
|---|---|
| 88% | Organizations using AI in at least one business function (McKinsey, 2025 survey) |
| 71% | Organizations regularly using generative AI in at least one function (McKinsey, March 2025) |
| 37% | Respondents attributing any EBIT impact to AI (McKinsey, 2026) |
| 6% | AI high performers, 5% or more of EBIT from AI (McKinsey, 2026) |
| 280x | Fall in GPT-3.5-level inference cost, Nov 2022 to Oct 2024 (Stanford AI Index 2025) |
What ROI do enterprises typically see from LLM deployments?
The best results come from named deployments, not averages: Kaiser Permanente saved nearly 16,000 physician documentation hours, and Klarna cut errand time from 11 minutes to under 2. Only 37% of respondents report any EBIT impact from AI (McKinsey 2026).
Survey averages hide a wide spread: McKinsey counts only 6% of respondents as AI high performers, unchanged from 2025. The return comes from the workflow you redesign, not the model you buy.
How much does it cost to implement LLMs in my organization?
Costs vary dramatically with scope. Model fees are often the smallest line: 50,000 support chats a month cost roughly $25 to $2,500 in tokens depending on the model. Integration, retrieval, evaluation and human review cost far more.
The key variable is scope: how many use cases, how much data processing, and how much customization. Gaper's contact-center composite puts the new-cost line at three to six percent of gross savings.
When should a business fine-tune an LLM versus use prompt engineering?
Start with prompt engineering and retrieval; they are faster, cheaper and enough for most tasks. Fine-tune only when a narrow, repetitive task still fails your evals, and expect to do it on an open-weight model.
What's the difference between fine-tuning and prompt engineering? Prompt engineering involves crafting instructions and context to guide an LLM toward desired behavior without modifying model weights. Fine-tuning involves training the model on task-specific examples to adapt behavior. OpenAI's guidance is to set up evals first and start with about 50 well-crafted examples, not thousands. Start with prompt engineering; graduate to fine-tuning if results are insufficient.
How do enterprises handle the LLM hallucination problem in production?
They layer defenses: ground answers in retrieved documents, route low-confidence answers to a person, require human sign-off on high-stakes decisions, and feed corrections back into the system. No single control is enough.
Effective hallucination mitigation combines multiple approaches: implementing confidence thresholds that route low-confidence responses to human review, grounding responses in retrieved documents rather than training data, implementing human oversight for high-stakes decisions, and building feedback loops where corrections improve model performance. Single-strategy approaches fail; successful systems layer multiple mitigations.
What LLM should I choose for my specific use case?
Pick the cheapest model that passes a test set built from your own cases: a small model for routing and extraction, a mid-tier model for most drafting, and a flagship only where the evals show it is needed.
Start by evaluating your constraints: Do you have strict data privacy requirements? Can you accept third-party API calls or do you need self-hosting? How customized does the model need to be for your specific domain? How much latency can you tolerate? Most organizations should start with commercial APIs (OpenAI, Anthropic, Google) for speed-to-market, then evaluate open-weight alternatives if privacy or customization becomes limiting. List prices on 8 November 2026, per million input and output tokens:
| Vendor | Flagship | Mid-tier | Small and fast |
|---|---|---|---|
| OpenAI | GPT-6 Astra, $10 / $50 | GPT-6.1 Sol, $2 / $10 | GPT-6 Luna, $0.10 / $0.50 |
| Anthropic | Claude Fable 5.1, $10 / $50; Claude Opus 5.5, $4 / $20 | Claude Sonnet 5.5, $2 / $10 | Claude Haiku 5.5, from $0.10 / $0.50 |
| Gemini 4 Argon, $2 / $10 ($4 / $20 from 1 Dec 2026) | Gemini 3.8 Flash, $0.75 / $3.75 (rises 1 Jan 2027) | Gemini 3.5 Flash-Lite, $0.30 / $2.50 |
For self-hosting or a managed open-weight endpoint, our Llama 4 migration guide covers when that is worth it.
How do I measure LLM implementation success?
Measure the business outcome the workflow exists for, such as cost per interaction, resolution rate, hours saved or errors caught, against a baseline taken before launch. Benchmark and perplexity scores do not count.
Focus on business metrics rather than technical metrics. Define success based on your specific use case: cost per interaction, resolution rate, accuracy, speed of task completion, or business outcome impact. Measure before and after implementation to quantify improvement. Track cumulative impact across multiple LLM projects rather than evaluating each in isolation.
How long does LLM implementation take?
A proof of concept on a commercial API can be done in 4 to 8 weeks. A pilot with custom data, legacy integration and governance takes 3 to 6 months, and full production 9 to 15 months.
Timeline varies based on complexity. Simple proofs-of-concept using commercial LLM APIs can be completed in 4-8 weeks. More complex implementations with custom training data, integration with legacy systems, and governance frameworks require 3-6 months for pilot projects, with full production deployment taking 9-15 months. The most important factor: start with realistic timelines and include adequate time for governance, testing, and organizational change management.
What does a phased enterprise LLM implementation roadmap look like?
It runs in four phases: Foundation and Experimentation (months 1 to 3), Pilot Implementation and Learning (months 4 to 8), Scale and Optimization (months 9 to 15), and ongoing Continuous Improvement.
Give each phase an exit test: a passing test set, then a measured result under governance, then a shared platform.
Why do some LLM deployments stall at the pilot stage?
Organizational readiness, not model quality, is the usual block: no single executive sponsor with budget authority, no evaluation harness for production prompts, and no plan to retrain the people whose work changes.
We sort enterprises into three tiers based on six observable signals: data hygiene, executive sponsorship, ML-engineering depth, evaluation discipline, governance maturity, and worker training. Moving up a tier requires three things in order: a single executive sponsor with budget authority, a published evaluation harness for every production prompt, and a workforce-retraining program that explains the new working contract to employees. Without all three, additional model spending compounds rather than fixes the problem. Gartner predicts over 40% of agentic AI projects will be canceled by the end of 2027.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
What ROI do enterprises typically see from LLM deployments?
How much does it cost to implement LLMs in my organization?
When should a business fine-tune an LLM versus use prompt engineering?
How do enterprises handle the LLM hallucination problem in production?
What LLM should I choose for my specific use case?
How do I measure LLM implementation success?
How long does LLM implementation take?
What does a phased enterprise LLM implementation roadmap look like?
Why do some LLM deployments stall at the pilot stage?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.