Ethical Considerations in LLM Development: A Supervised-by-Design Playbook (2026)
Ethical considerations in LLM development for 2026: bias, hallucination, copyright, privacy, red-teaming, oversight, and the EU AI Act and US rules.
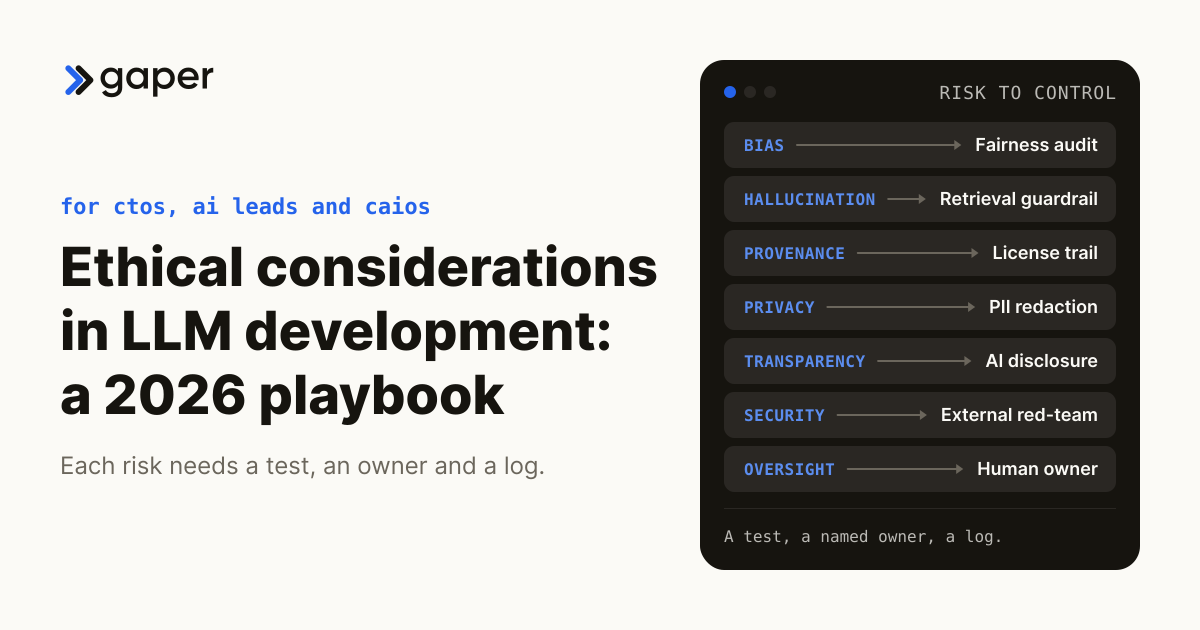
The ethical considerations in LLM development are bias, hallucination, training data provenance and copyright, privacy, transparency, security and human oversight, and each needs a test, a named owner and a log before launch. In October 2026 the EU AI Act's general-purpose model duties are enforceable, US Executive Order 14110 has been revoked and the frontier-model testing in the orders that followed is voluntary, and courts are pricing training-data shortcuts in the billions.
Ethical considerations in LLM development: the 2026 operator playbook
The ethical considerations in LLM development that decide whether a product ships safely in 2026 are bias control, hallucination guardrails, data provenance, copyright clearance, privacy handling, transparency disclosures, and red-team coverage. Most now carry a legal duty in at least one market you sell into. This playbook is for the CTOs, AI leads and Chief AI Officers who build the system, supervised by design: every material output has a human owner, a test and a record.
Key Takeaways
- EU AI Act fines reach 35 million euros or 7 percent of global revenue, whichever is higher, for prohibited practices; general-purpose model providers face up to 15 million euros or 3 percent, enforceable since 2 August 2026.
- Shortcuts get expensive: Anthropic's 1.5 billion dollar settlement with authors over pirated training copies won final approval on 20 July 2026, and appeals followed in August.
- The NIST AI Risk Management Framework is still the free, voluntary US baseline. US Executive Order 14110 no longer applies.
- A pre-deployment checklist, live monitoring and a 60-minute incident runbook cover most failure modes auditors and reporters care about.
Table of Contents
- Why ethical considerations in LLM development matter in 2026
- The seven core risk areas every LLM team must cover
- The 2026 regulatory landscape
- Liability and vendor contracts
- The pre-deployment ethics checklist
- The hidden cost of skipping ethical governance
- Monitoring, red-teaming, and incident response
- Human oversight and healthcare
- How Gaper builds ethics-ready LLM systems
- Buyer questions
Why ethical considerations in LLM development matter in 2026
Every team shipping a customer-facing LLM in 2026 is a few ethical considerations in LLM development away from a brand crisis or a fine. The EU AI Act's obligations for general-purpose model providers have applied since 2 August 2025, and enforcement of them started on 2 August 2026 (AI Act Service Desk). US Executive Order 14110, with its red-team reporting duty, was revoked on 20 January 2025 (EO 14148). The FTC ordered seven companies, OpenAI and Meta among them, to explain how they test companion chatbots for harm to children (FTC, September 2025). The cost of being wrong is no longer hypothetical.
Failure modes have matured: bias, hallucination, data leakage, and copyright disputes moved from research papers into tribunals and settlements. Air Canada was held liable in February 2024 for a bereavement fare rule its chatbot got wrong (Moffatt v. Air Canada, 2024 BCCRT 149). The New York Times has sued OpenAI and Microsoft for billions; filed in December 2023, the case is still pending (docket). Anthropic's 1.5 billion dollar authors' settlement won final approval on 20 July 2026, and notices of appeal to the Ninth Circuit were filed in August (docket).
Regulatory pressure on LLM operators, October 2026
| Market | What binds an LLM builder | Status |
|---|---|---|
| European Union | AI Act: model provider duties, prohibitions, Article 50 transparency; high-risk rules from 2 December 2027 | In force, phased |
| United States, federal | Executive orders, NIST frameworks, FTC consumer protection | Executive policy |
| United States, states | Sector and state laws, such as NYC's hiring audit rule and Colorado's automated decision law, with duties from 1 January 2027 | Varies |
| China | Explicit and embedded labels on AI-generated content since 1 September 2025 (CAC) | In force |
If you ship to a global audience, the EU rules are the ceiling you need to clear. If you only ship to the US, FTC orders and state laws set the practical rules faster than Congress. Either way, an ethics program is part of your product readiness gate. Teams building modern conversational systems should read our companion guide on regulatory compliance for chatbot LLMs for the customer service angle on the same problem.
The seven core risk areas every LLM team must cover
Most failure modes auditors flag in 2026 fall into seven buckets. Some are tightly regulated, others are mostly reputational, but every operator has to take a position on each one before launch.
Risk tier stack for LLM operators
| Tier | Risk areas | Why |
|---|---|---|
| Top | Bias in regulated decisions, PII leakage | Regulator action plus class actions |
| High | Copyright and training data provenance | Case law still forming, very large settlements |
| Elevated | Hallucination, transparency, security | Smaller judgments, fast loss of trust |
Copyright sits at high risk because the case law is still forming, but the financial exposure is enormous. Hallucination, transparency, and security failures rarely produce a single seven-figure judgment, but they erode trust faster than any other category.

Bias and fairness
Bias enters an LLM through three channels: training data skew, reinforcement learning from human feedback that codifies the labellers' preferences, and prompt patterns that overweight certain demographics. In a University of Washington test of three AI models on more than 550 real resumes, varying only the names, the models favored white-associated names 85 percent of the time and female-associated names 11 percent of the time (UW, October 2024). Operators in hiring, lending, healthcare, and insurance must run disparate-impact tests before launch and at least quarterly afterward.
Hallucination and factual reliability
Hallucination is the failure mode the press writes about. In Air Canada, the tribunal rejected the airline's argument that its chatbot was responsible for its own words and awarded about 812 Canadian dollars; the headlines were global. Overclaiming is the regulatory version: the FTC's 2025 order against DoNotPay followed a complaint that it never tested whether its "AI lawyer" worked like a lawyer (FTC). The fix is not better prompts. The fix is retrieval-augmented generation against a curated knowledge base, a confidence threshold below which the model must say "I do not know," and a clear escalation path to a human agent for any high-stakes question.
Training data provenance and copyright
If you fine-tune on third-party data, you need a license trail. In Bartz v. Anthropic (June 2025), training on books was fair use, but pirated copies in a central library were sent to trial, which led to the settlement (order). Kadrey v. Meta also found fair use, on a record the judge called weak on market harm (Goodwin). In the UK, Getty lost its secondary infringement claim against Stability AI in November 2025 (judgment) and was given permission to appeal in December (order). Providers of general-purpose models in the EU must publish a training content summary on the Commission's template of 24 July 2025 (Commission). Document every dataset, license, acquisition route and honored opt-out. Synthetic data from a licensed model is often cleaner than scraped web data, if its terms allow it.
Privacy and PII handling
User prompts often contain names, account numbers, medical history, or internal company secrets. Three rules cover most of the exposure: do not train on user prompts by default, redact PII before the prompt reaches the model, and offer enterprise customers a contractual carve-out that guarantees their data never crosses your model boundary. Collect only what the application needs, and ask whether aggregate data would do. HIPAA, GDPR, and the CCPA all carry penalties; after a breach caused by a failure to keep reasonable security, the CCPA sets statutory damages of 107 to 799 dollars per consumer per incident, or actual damages if higher (CPPA). The average breach cost a record 4.99 million dollars in IBM's 2026 report (IBM).
Transparency and AI disclosure
Tell people when they are talking to an AI, and label its output. Article 50 of the EU AI Act has required this since 2 August 2026, with machine-readable marking for systems already on the market due by 2 December 2026; the Commission published a voluntary code of practice on marking and labelling on 10 June 2026 (Commission). Publish a model card and say plainly what the system cannot do.
Security and red-team coverage
Red-team for the attacks LLMs actually face. The OWASP Top 10 for LLM Applications (2025) starts with prompt injection, sensitive information disclosure and supply chain risk, and lists excessive agency and system prompt leakage (OWASP). Test each before launch and after every model or prompt change. For agents that act inside your systems, permissions matter as much as prompts: see AI agent security.
How do you test an LLM for bias before launch?
Build a test set that mirrors your launch population, swap only protected attributes such as names, and compare outcomes per group: selection rates, scores, refusals and tone. Fix and re-test before launch, then sample production quarterly.
Use diverse, representative data, audit early, put ethicists, domain experts and engineers on the review, and retrain when fairness metrics drift. Test outcomes, not just inputs: a model can infer identity from schools, cities and word choice. For approval rights on the decisions an LLM shapes, see our guide to ethical AI decision-making.
The 2026 regulatory landscape: EU AI Act, US executive orders, NIST AI RMF
Three sources drive most LLM compliance work in 2026. The EU AI Act binds anyone who places AI on the EU market, and non-EU providers and deployers whose system's output is used in the EU (Article 2). US federal policy now runs through executive orders: frontier-model testing is voluntary, and federal LLM purchases carry contract terms. The NIST AI Risk Management Framework is voluntary, but US contractors, financial regulators, and insurers treat it as the default operator playbook. This is information, not legal advice.
| Dimension | EU AI Act | US executive orders (EO 14110 revoked) | NIST AI RMF 1.0 |
|---|---|---|---|
| Status | Binding law, amended by the Digital Omnibus (in force 27 July 2026) | EO 14179 (January 2025), AI Action Plan (July 2025), EO 14409 (June 2026) | Voluntary standard, being revised |
| Scope trigger | Placed on the EU market, or output used in the EU | Federal policy, federal LLM procurement | Any operator that adopts it |
| Maximum penalty | 35 million euros or 7 percent for prohibited practices; 15 million or 3 percent for model providers | None; federal LLM contracts carry Unbiased AI Principles terms | None directly |
| Risk classification | Prohibited, high, limited, minimal; systemic-risk models | "Covered frontier models" set by a classified benchmark | Govern, Map, Measure, Manage |
| Red-team requirement | Adversarial testing for systemic-risk models; high-risk rules from 2 Dec 2027 | A voluntary framework, to be designed, for government access up to 30 days before release | Recommended under Measure |
| Disclosure to users | AI notice and machine-readable marking | Federal LLM vendors may disclose system prompts or evaluations | Transparency principle |
EO 14179 ordered a review of every action taken under EO 14110 (EO 14179). EO 14319 limits agencies to LLMs that meet two "Unbiased AI Principles", and OMB memo M-26-04 (11 December 2025) turns them into contract terms (OMB). EO 14409 directs agencies to design a voluntary framework for "covered frontier models" and says it creates no licensing duty (Federal Register). EO 14365 set up a federal task force to challenge state AI laws in court and asked for a bill to preempt them (EO 14365).
For most US-headquartered teams, the practical play is still to build to the NIST framework first, with its Generative AI Profile (NIST AI 600-1, July 2024), then layer the EU specifics on top before any European launch. NIST says AI RMF 1.0 is being revised, with no new version yet (NIST). The 10 to the 26 operations reporting trigger went with EO 14110.
Who is liable when an LLM system causes harm?
In the cases so far, usually the business that deploys it, not the model. Air Canada could not shift blame to its chatbot, and the FTC holds companies to their AI claims. Plan for privacy, IP, discrimination, consumer protection and sector liability.
Privacy: tell users how you collect and use data (GDPR, CCPA). IP: settle who owns AI-generated content and whether it infringes copyrights or patents. Discrimination: employment and lending laws reach algorithmic outcomes, and faulty or incomplete data leaves blind spots. Accountability: name who answers for an AI decision before harm. Sector rules: HIPAA, SEC rules and autonomous vehicle rules keep changing, so check with counsel. Consumer protection: explain AI decisions and avoid deceptive claims. Negligent use counts too, so review, test and monitor every change. This is general information, not legal advice.
What should an AI vendor contract cover?
Intellectual property rights, liability, indemnification and data privacy at minimum, plus each party's role, the vendor's security measures, notice before model changes, access to logs and exit terms.
Check that vendors meet your privacy laws, keep a data governance policy, seek independent third-party reviews, and be forthcoming about incidents and corrective measures.
The pre-deployment ethics checklist
A pre-deployment checklist sits between the last sprint and the launch button, catching the failures lawyers and regulators will surface later. The version below has cleared more than 40 production LLM rollouts at Gaper, across healthcare, fintech, legal, and consumer SaaS. It maps one to one to the NIST Measure and Manage functions, and it satisfies the EU AI Act's documentation requirements for high-risk systems (obligations that now apply from 2 December 2027 for Annex III uses).
Pre-deployment ethics rule book. Eight checks, each owned by a named person, signed off before any traffic touches the production model.
- Document every training data source, its license and how it was acquired.
- Run a fairness audit on the launch population.
- Define a hallucination acceptance threshold.
- Wire PII redaction at the gateway.
- Add a user-facing AI disclosure.
- Commission an external red-team exercise.
- Publish a model card and data sheet.
- Stand up an incident response runbook.
Skipping any one of these rules is what turns a routine launch into a board-level incident two quarters later. The classic mistake is treating the checklist as a one-time gate; in practice every item needs an owner, a recurring review, and a clear escalation path.
A useful sorting frame for any new LLM feature is the two-by-two below: how reversible a wrong answer is, and how exposed it is to a regulator.
Decision matrix: how heavy a launch gate to apply
| Low regulator exposure | High regulator exposure | |
|---|---|---|
| Easy to reverse | Light gate: log inputs and outputs | Standard gate |
| Hard to reverse | Heavy gate | Max gate: the full eight-rule check |
The matrix lets product and counsel align in five minutes instead of arguing for a week. Most consumer chat features fall in the standard zone. Anything that touches credit, health, employment, or housing jumps to the max gate by default, regardless of what the engineering team thinks the user is doing.
The hidden cost of skipping ethical governance
Teams that skip the ethics work because it feels expensive usually find the savings evaporate within one product quarter. The visible costs are bounded: a few engineering weeks, a legal review, and a red-team vendor. The hidden costs after a failure are far larger and land outside the engineering budget: breach response, litigation, settlements, lost deals and press.
IBM's 2026 report puts the average breach at 4.99 million dollars, and Anthropic's settlement shows what poorly sourced training data can cost. Enterprise buyers increasingly send AI risk questionnaires before onboarding a vendor, and a weak answer stalls the deal. A working ethics program pays for itself the first time a regulator or procurement officer asks for documentation.
Monitoring, red-teaming, and incident response in production
An ethics program does not end on launch day: behavior drifts as users invent new prompts, data ages, and the regulatory floor moves. The post-launch loop has three parts: continuous monitoring, scheduled red-teaming, and a tight incident runbook. This is the cadence Gaper engineers run for a typical mid-market deployment.
Post-launch ethics cadence. Five checkpoints across the first six months catch the bulk of post-launch drift. Quarterly red-team and fairness audits then continue indefinitely.
Monitoring needs to track what regulators actually ask about, not just latency and token cost. The four ethics signals every dashboard should expose are refusal rate by user segment, hallucination flag rate from your retrieval guardrail, escalation-to-human rate, and a sampled fairness score against your launch baseline. Anything that moves more than 15 percent week over week deserves a triage call.
Incident response is where most teams underinvest until the first incident lands. A working runbook names a single accountable owner, defines four severity tiers, sets a rollback path that can be triggered in under 30 minutes, and hard-codes the notification windows that apply, because missing the window is the most expensive mistake.
Incident response: time-to-notify by regime
| Regime | Who notifies whom | Deadline |
|---|---|---|
| GDPR Article 33 | Controller to the supervisory authority | Within 72 hours where feasible (text) |
| HIPAA | Covered entity to individuals; to HHS at the same time for 500 or more | No later than 60 days (45 CFR 164.404) |
| EU AI Act Article 73 | High-risk system provider to the market surveillance authority, once high-risk duties apply | 15 days; 10 for a death; 2 for widespread infringement (text) |
| US state breach laws | Business to residents, sometimes the attorney general | Varies by state |
The narrowest window is the binding one, so most multi-jurisdiction operators treat 72 hours as the universal incident clock. If your runbook can hit 72 hours, you have headroom for HIPAA and the EU AI Act. If it cannot, fix the bottleneck before the first real incident. Teams that want to add an additional layer of defense should look at our overview of specialized LLM experts who can architect production-grade safety controls from day one.
Where should human oversight sit in an LLM system?
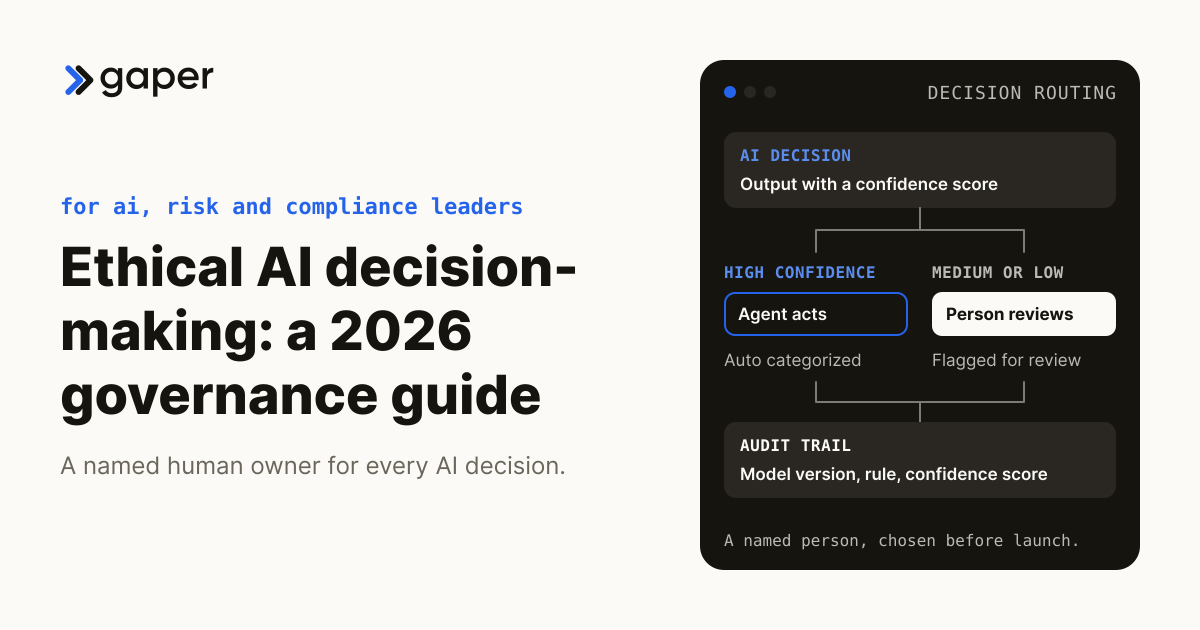
At every step where a wrong output is material or hard to reverse. Label each step Automated, Agent-drafted and human-approved, or Human-owned, log who approved what, and let the reviewer see the sources behind each answer.
That is the Gaper Ownership Map; Human-owned means the agent never runs it alone. Oversight prevents overreliance on a fallible tool and keeps a person accountable. Log the input, prompt and model version, sources, output, reviewer and action. Our guide to human-in-the-loop AI covers approval gates.
What extra ethical duties apply when an LLM is used in healthcare?
Patient privacy, equal care and clinician accountability. Sign a BAA with every vendor that touches PHI, test outcomes across patient groups, explain recommendations to clinicians, and keep a licensed professional in charge of care decisions.
Since 1 May 2025, Section 1557 covered entities must make reasonable efforts to identify patient care decision support tools, AI included, that use race, color, national origin, sex, age or disability as inputs, and to mitigate the risk of discrimination (45 CFR 92.210). GDPR governs consent in Europe, and FDA device rules can reach clinical software; our guide to AI for hospitals covers the EHR, BAA and FDA work. Audit and update models as medical knowledge changes.
Healthcare providers and startups should consider adopting Gaper's LLMs, which are designed with a strong emphasis on addressing ethical implications. Gaper's advanced AI solutions prioritize data privacy, minimize bias, and ensure transparency in medical decision-making. By integrating these responsible LLMs into your healthcare operations, you can enhance patient care while upholding the highest ethical standards. Embrace Gaper's LLMs to streamline your processes, improve diagnostic accuracy, and maintain trust in your AI-driven solutions.
How Gaper builds ethics-ready LLM systems
Gaper is the AI-native implementation partner that deploys supervised AI agents you own. Our LLM practice covers the full ethics stack: bias auditing for hiring, lending, and healthcare deployments, retrieval-augmented architectures that cut hallucination by 60 to 80 percent, PII redaction gateways that satisfy HIPAA and GDPR, model cards that pass procurement reviews, and quarterly red-team and fairness audits. We also support EU AI Act conformity assessments and NIST AI RMF documentation packages. Gaper engineers have built bias audits, hallucination guardrails, PII gateways, model cards, and incident runbooks for LLM rollouts across healthcare, fintech, legal, and consumer SaaS.
At handover you own the code, prompts, evaluation set, runbook and audit trail. If no one owns AI in your company yet, a Chief AI Officer is the role that signs off this checklist.
Most engagements open with a free 45-minute assessment that maps your state to the eight-rule checklist and surfaces the three highest-leverage fixes for the next 90 days. Book a free assessment at Gaper's booking page, explore the engineering pool at the hire AI engineers who specialize in evaluation harnesses. We are backed by 14 verified Clutch reviews and Harvard and Stanford alumni. Tell us your project and we will scope the ethics stack in a free assessment call. Free assessment. No commitment.
What are the most important ethical considerations in LLM development in 2026?
Bias and fairness, hallucination control, training data provenance, copyright and intellectual property, privacy and PII handling, transparency and AI disclosure, and red-team coverage. Each maps to the EU AI Act, US consumer protection law and the NIST AI RMF.
Bias and PII leakage carry the highest financial exposure because they trigger both statutory damages and class actions.
Do the EU AI Act and US federal AI rules apply to my startup?
The EU AI Act applies if you place AI on the EU market or your system's output is used in the EU, wherever you are based. US federal AI orders mostly bind agencies; for a startup they bite through federal LLM contracts.
Align with the NIST AI RMF first and add EU documentation later. Maximum EU penalties are 35 million euros or 7 percent of global revenue, whichever is higher, for prohibited practices; for SMEs and start-ups, the lower of the two applies (Article 99).
How do I actually reduce hallucination in a production LLM?
Switch from prompt-only generation to retrieval against a curated, versioned knowledge base, set a confidence threshold below which the model says "I do not know," log every refusal, and route high-stakes questions to a human reviewer.
Better prompts alone will not solve the problem at scale.
What goes into a pre-deployment ethics checklist?
Eight items: document every training data source, run a fairness audit on the launch population, define a hallucination threshold, wire PII redaction at the gateway, add an AI disclosure, red-team externally, publish a model card and data sheet, and stand up an incident runbook.
Each item needs a named owner.
How fast can Gaper assemble an ethics-ready LLM team?
Most engagements open with a free 45-minute assessment that maps your state to the eight-rule checklist and surfaces the three highest-leverage fixes for the next 90 days.
Engagements are backed by 14 verified Clutch reviews and Harvard and Stanford alumni.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
How do you test an LLM for bias before launch?
Who is liable when an LLM system causes harm?
What should an AI vendor contract cover?
Where should human oversight sit in an LLM system?
What extra ethical duties apply when an LLM is used in healthcare?
What are the most important ethical considerations in LLM development in 2026?
Do the EU AI Act and US federal AI rules apply to my startup?
How do I actually reduce hallucination in a production LLM?
What goes into a pre-deployment ethics checklist?
How fast can Gaper assemble an ethics-ready LLM team?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.