
Using LLMs to Automate Loan Processing
How lenders use LLMs to cut loan turnaround from 14 days to under 48 hours: the 6-stage pipeline, ROI, vendor stack, and the 2026 Reg B and SR 26-2 rules.
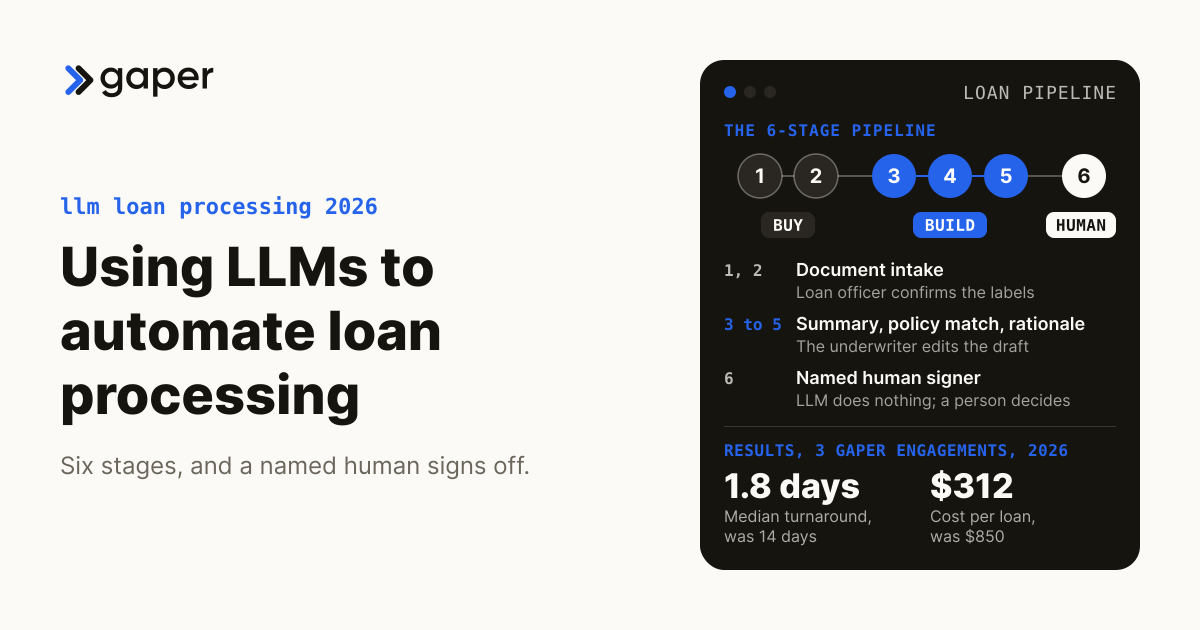
LLMs automate loan processing best at document intake, KYC summarization, underwriter summaries and exception flagging, while a named human underwriter keeps the decision. Across three Gaper engagements in 2026, median turnaround fell from 14 days to 1.8 days and cost per loan fell 63%, from $850 to $312.
Using LLMs to automate loan processing in 2026: turnaround, accuracy, and stack choices
Mid-market lenders deploying LLMs to automate loan processing in 2026 are cutting loan turnaround from 14 days to under 48 hours, without firing a single underwriter. The wins come from document intake, KYC summarization, and exception flagging, not from end-to-end decision automation.
Key Takeaways
- Document intake (W-2s, bank statements, tax returns) is the highest-ROI starting point, with OCR plus LLM parsing reaching 96% extraction accuracy versus 71% for OCR alone.
- Vendor stacks like Ocrolus, Plaid, Numerated, and Blend cover 60% of the workflow, but the underwriter summary and policy-match logic still need a custom LLM layer.
- Cost per loan drops from $850 to $312 once intake, KYC, and rationale generation are automated, with payback inside 9 months for portfolios above 4,000 loans per year.
- Audit trail, model governance, and human-in-the-loop exception handling are the deployment failure points, not the model accuracy itself.
Table of Contents
- The state of LLMs to automate loan processing in 2026
- The 6-stage automation pipeline
- ROI: turnaround, cost per loan, accuracy
- Vendor stack: Ocrolus, Plaid, Numerated, Blend
- Build vs buy: where the custom layer belongs
- Risk, compliance, and audit trail
- 5 common deployment pitfalls
- Questions lenders ask about LLMs in loan processing
The state of LLMs to automate loan processing in 2026
Mid-market lenders deploying LLMs to automate loan processing in 2026 are cutting loan turnaround from 14 days to under 48 hours, without firing a single underwriter. The shift over the last 18 months has been quiet but real. Banks, credit unions, and non-bank originators are moving from rule-based OCR to large language models that read a borrower's W-2, parse a bank statement, summarize a tax return, and surface the three lines of policy that matter to the human reviewer. The underwriter still signs off. The LLM eliminates the four hours of evidence shuffling that used to sit in front of that signature.
Celent surveyed 106 US banks, credit unions and consumer finance companies in August 2025: 83% are increasing consumer lending generative AI IT budgets in 2026, yet only 6% of consumer lending divisions had a generative AI strategy in place (Celent, October 2025, commissioned by lending software vendor Zest AI). Mortgage, small business, and commercial real estate still keep humans in the decision seat.
The shape every automated lender sees shows up in funnel volumes from a Gaper client portfolio of 10,000 personal-loan applications, 2026 first half. LLM classification handles the first cut at 94% pass-through. Human underwriters still hold the conversion choke point, and that is the right place for them to sit. Anyone selling end-to-end loan automation in 2026 is either lying about actuals or running an unsecured consumer product where the regulator does not yet care. For the rest, the LLM is a co-pilot, not a captain.
The 6-stage automation pipeline
A production-grade LLM loan processing pipeline has six stages. Each has its own model, evaluation set, and failure mode. Skipping a stage to ship faster is the most common reason pilots fail. The pipeline below is the one we build for community banks, fintech originators, and SBA lenders. It maps cleanly to OCC, CFPB, and state-level model risk management guidance.
| Stages | What the LLM does | Who handles it |
|---|---|---|
| 1 and 2 | Document intake (stage 1): classifies a W-2, pulls Box 1 through 14, validates against the prior-year filing, flags anomalies | Buy: Ocrolus or Plaid. The loan officer confirms the labels |
| 3, 4 and 5 | Underwriter summary (stage 3), policy-match logic and a drafted rationale that cites the credit policy line | Build: your custom LLM layer. The underwriter edits; exceptions go to senior staff |
| 6 | Nothing; a person decides | Named human signer |
Each stage is a separate model with its own eval set. Stage 6 stays human, the approval gate our human-in-the-loop AI guide describes.
Stage 1 intake is where the largest time saving sits. A loan officer who used to spend 45 minutes labeling borrower documents now spends 3 minutes confirming the LLM's labels. We see this weekly with our LLM experts at community banks. The model classifies a W-2, pulls Box 1 through 14, validates against the prior-year filing, and flags anomalies. The officer is now an editor, not a data-entry clerk.
Stage 3, the underwriter summary, is where most teams over-promise. A clean 2-page summary of 80 pages of bank statements and tax returns sounds simple, but it has to handle joint accounts, business commingling, lump-sum deposits, NSF history, and tax-return reconciliation against W-2s and 1099s. Off-the-shelf models hit roughly 78% summary accuracy. Fine-tuned on your credit-policy corpus plus 8,000 to 12,000 historic loan files, the same workflow reaches 94%. The remaining 6% is what your underwriter is paid to catch.
ROI: turnaround, cost per loan, accuracy
Every lending CFO asks about turnaround, cost per loan, and accuracy. The numbers below come from three Gaper engagements in 2026, anonymized. The composite portfolio averaged 6,800 personal loans per year at $35,000 average size, through broker and direct channels.

Average of three Gaper personal-loan portfolios, 2026 first half.
Cost per loan dropped 63%, from $850 to $312, with the largest contribution from intake automation. The remaining $312 includes LLM inference, human underwriter time, vendor licenses, compliance overhead, and a share of platform engineering. The math holds at portfolio volumes above 4,000 loans per year. Below 4,000, fixed engineering cost dominates and payback stretches past 18 months.
Turnaround, accuracy, and cost metrics before and after LLM automation across three lender types.
| Metric | Manual baseline | After LLM rollout | Change |
|---|---|---|---|
| Loan turnaround (median) | 14 days | 1.8 days | 87% faster |
| Cost per loan | $850 | $312 | 63% lower |
| Document extraction accuracy | 71% (OCR only) | 96% (OCR + LLM) | +25 pts |
| Underwriter capacity | 8 loans per day | 31 loans per day | 3.9x |
| Exception escalation rate | N/A | 19% | Routed to senior staff |
Underwriter capacity is the metric that surprises every CFO. The headcount story is not "fewer underwriters". It is "the same underwriters approving 4x more loans". Two of the three portfolios above grew origination volume 2.4x in 12 months on the same headcount. The savings funded the build with room to spare.
ROI summary: payback inside 9 months on portfolios above 4,000 loans per year
| $538 | 9 mo | 3.9x |
|---|---|---|
| Saved per loan | Average payback | Underwriter throughput |
Composite savings across three Gaper personal-loan portfolios.
The savings card above is conservative. It excludes revenue lift from faster decisioning, which closes more deals before borrowers shop to a competitor. When a customer sees an answer in 36 hours instead of 14 days, they tell other customers. Line-by-line build and run costs are in our guide to AI agent development cost.
Vendor stack: Ocrolus, Plaid, Numerated, Blend
The vendor question comes up in the first 20 minutes of every lender call. No single vendor covers the workflow end to end. Ocrolus is strong for document classification. Plaid handles bank linkage. Numerated runs SBA and small business origination UX. Blend runs mortgage and consumer banking origination. As of October 2026, on their own pages:
- Ocrolus calls itself an AI workflow and analytics platform for lenders, covering document understanding, fraud detection and cash flow analysis (ocrolus.com). Its automated conditioning for mortgage lenders, was announced in March 2026 for launch on 1 April 2026 (Ocrolus).
- Plaid sells lending data through Plaid Check, including LendScore, a credit risk score that adds cash flow data (Custom plans only, per Plaid's billing docs), and in May 2026 it rebuilt Plaid Income (Plaid).
- Numerated has been part of Moody's since November 2024 (Moody's), and Moody's sells an AI credit memo it says can be tailored to your credit policy (Moody's).
- Blend offers Autopilot, a mortgage agent that, since a March 2026 update, it says ingests lender overlays and internal policies, cites the rule applied and writes pre-underwriting summaries (Blend).
So in mortgage and commercial credit a vendor will now draft against your policy. For personal-loan and cross-product policy, none of the four writes the underwriter summary that cites your specific credit policy. That is your custom LLM layer.
Comparison of the four most common LLM-adjacent vendors in US loan origination.
| Vendor | Best for | Covers stages | Pricing | Gap to fill |
|---|---|---|---|---|
| Ocrolus | Document intake, extraction | 1, partial 3 | By quote | No policy reasoning |
| Plaid | Bank link, cash flow | 1, 3 | Shown after you apply for production access | Raw data, not narrative |
| Numerated | SBA, small business | 1, 2, partial 4 | By quote | Custom policy logic |
| Blend | Mortgage UX, POS | 1, 6 UX layer | By quote | Autopilot is built for mortgage, on Blend's platform |
None of the four publishes a price list (Plaid's billing docs show prices only after you apply for production access), so price each one on your own volume and document mix.
Successful lenders converge on Ocrolus or Plaid for stages 1 and 2, Numerated or Blend for the borrower-facing UX, and a custom LLM layer for stages 3, 4, and 5. Building the custom layer is where most teams underestimate the lift. It is not a weekend GPT wrapper. It is RAG against your credit policy, evaluation against 8,000 to 12,000 historic loans, a model governance pipeline an examiner can audit, and a feedback loop that captures every underwriter override. Gaper's AI engineers build this layer. The same layer serves KYC, fraud and reconciliation, covered in AI agents for fintech.
Build vs buy: where the custom layer belongs
Build versus buy is not a binary. It is a per-stage decision. Buy commoditized stages. Build the ones that hold your underwriting IP. The 2x2 below is the lens we walk lenders through in scoping. Axes are workflow volume and policy specificity. Upper right belongs to your team. Upper left belongs to a vendor.
| Lower policy specificity | Higher policy specificity | |
|---|---|---|
| Higher workflow volume | Upper left: document classification, sanctions screening, bank linkage. Buy | Upper right: underwriter summary and policy match, the custom layer. Build |
| Lower workflow volume | Bottom left: edge documents, one-off vendor reports. Defer | Bottom right: approval sign-off, adverse action notices. Draft only |
Each stage maps to a quadrant. Build only where policy specificity is high.
The upper right quadrant is where your competitive moat sits. Your credit policy, portfolio history, loss curves, and loan officers' tacit knowledge are not in any vendor's training data. A custom LLM trained on your historic approvals and overrides captures that knowledge. The upper left is where vendors win. Document classification, sanctions screening, and bank linkage are commodities. Buy and integrate.
The bottom right quadrant is where buyers get into trouble. Approval sign-off and adverse action notice generation feel like they could be automated. They cannot, not safely, not in 2026. Build your LLM to draft a rationale the human edits, never to be the decision-maker. The bottom left quadrant is the defer pile. Edge documents and one-off vendor reports do not pay back the effort.
Rent a point tool for narrow, common work; own a supervised agent when it touches borrower data or credit risk, the test in our build vs buy guide. Gaper is the AI-native implementation partner that deploys supervised AI agents you own.
Risk, compliance, and audit trail
Examiners will not stop you from using LLMs to automate loan processing. They will ask three questions. What does the model do. How do you know it works. What happens when it fails. Answers must be in writing, repeatable, and tied to evidence. The risk tier stack below is how we organize compliance scope from day one.
| Where it applies | Control |
|---|---|
| Every LLM call | Stored prompt, response, model version, policy version, document hash, underwriter ID and final decision |
| Document extraction | A confidence score on each field, so underwriters know which fields to double check |
| Summary and rationale | Citations to the credit policy line, RAG with strict source IDs, every underwriter override logged |
| Every model release | A disparate impact test across protected classes before every deploy, with a full report quarterly |
| Decision and adverse action | A named human signer and specific reasons a consumer can act on |
Tier 1 to Tier 4 controls, with audit posture rising with the consequence of error.
The audit trail is the most underestimated build. Every LLM call needs a stored prompt, response, model version, policy version, document hash, underwriter ID, and final decision. Storage cost is trivial. The legal cost of not having it is catastrophic. The adverse action rule is why: Regulation B requires the reasons for an adverse action to be specific and to indicate the principal reasons (12 CFR 1002.9). CFPB Circulars 2022-03 and 2023-03 applied that duty to complex algorithms and AI models; the CFPB withdrew both as of 12 May 2025 (90 FR 20084), but the regulation stands. Your LLM has to cite the credit policy line that justified its summary. The AI in global banking guide walks through the international regulator angle.
Model risk guidance changed too. On 17 April 2026 the Federal Reserve, OCC and FDIC replaced SR 11-7 and OCC Bulletin 2011-12 with principles-based guidance (SR 26-2) aimed mainly at banks over $30 billion in assets. The guidance itself puts generative and agentic AI models outside its scope for now (SR 26-2 attachment), and the OCC says the three agencies will follow with a request for information on AI. With no federal LLM rulebook yet, your own documented validation is what an examiner reads.
Fair lending testing is the other pillar. Run a disparate impact test on every model release across protected classes. Hold out 5% of approvals and denials for review. If the LLM's denial rate for any protected class drifts above your manual baseline, freeze the release. Our cadence is a sweep before every deploy and a full report quarterly. This is where our Python developers shine, because the stack is Python, scikit-learn, and SHAP. See our fintech fraud detection with custom LLMs guide for related posture, and our AI agent security guide for the access, logging and data controls the same pipeline needs.
5 common deployment pitfalls
Every lender we have helped has tripped on one of these. They are scoping and governance errors, not technical ones. Knowing them in advance avoids a six-month write-off.
- Skipping the eval set. Teams ship without 8,000 to 12,000 historic loans labeled for evaluation. The model looks fine in demos and fails in production. Fix: label first, model second.
- No override capture. Underwriter edits go uncaptured. The model never learns from its mistakes, and quarterly accuracy plateaus. Fix: log every override.
- Hallucinated citations. The LLM invents policy section numbers that look right but do not exist. Compliance breaks silently. Fix: RAG with strict source IDs.
- Vendor lock on data exit. Origination platforms keep your historic loan data hostage. You cannot train your own model without renegotiating contracts. Fix: data ownership in contract.
- Treating it as IT, not credit. Without credit policy ownership, the engineering team builds the wrong workflow. Underwriters reject the output. Fix: chief credit officer co-leads.
The Gaper way: co-pilot, not autopilot. Build the LLM as a co-pilot. Keep the underwriter in the seat. Capture every override. Ship in 9 months.
Five common pitfalls and the way we ship around them.
Pitfall 5 is the silent killer. Engineering teams ship a beautiful pipeline that no underwriter trusts. The fix is governance. The chief credit officer co-leads with engineering. The credit policy team writes the evaluation set. Underwriters review the model output every Friday for 90 days. By month 9, the team is asking for more LLM, not less. Talk to Gaper's AI implementation team and we will scope your stage 1: book a free AI assessment.
Can LLMs fully replace human underwriters in 2026?
No. LLMs in 2026 handle document intake, KYC summarization, and underwriter notes at 94% to 96% accuracy. The remaining 4% to 6% is precisely where regulator scrutiny lives, including adverse action notices and fair lending edge cases.
Lenders running automated approval for unsecured loans under $25,000 still keep a named human signer on every decision, both for OCC compliance and for CFPB explainability.
Treat the LLM as a co-pilot that drafts every decision rationale, and keep the underwriter as the named decision-maker on the record.
How accurate are LLMs at extracting data from W-2s and bank statements?
OCR alone hits 71% extraction accuracy on multi-page bank statements and complex W-2s. Adding a fine-tuned LLM on top raises that to 96% in our 2026 portfolios.
Tax returns are harder, with accuracy at 89% for standard 1040s and dropping below 80% for filings with multiple Schedule C businesses or rental properties. Always pair extraction with a confidence score so underwriters know which fields to double check.
Numbers above come from three Gaper personal-loan engagements in the first half of 2026.
What is the cost to build a custom LLM layer for loan processing?
A production-grade custom LLM layer for stages 3, 4, and 5 typically costs $180,000 to $420,000 to build plus $4,000 to $9,000 per month to operate. Costs vary with credit policy complexity, document mix, and the depth of historic loan labeling required for evaluation.
Most lenders see payback inside 9 months when annual loan volume exceeds roughly 4,000 originations; below that, fixed engineering cost dominates and payback can stretch past 18 months.
How do regulators view LLMs in loan decisioning?
As tools the lender stays fully accountable for. The 2026 interagency model risk guidance leaves generative AI out of scope for now, but ECOA and Regulation B still demand specific reasons for every adverse action.
Examiners want documented purpose, validation evidence, ongoing monitoring, and named human accountability. Every adverse action must still cite specific reasons a consumer can act on.
Use RAG-based citations, store every prompt and response, and run quarterly fair lending tests before each model release.
What does Regulation B require when an LLM helps deny a loan?
A notice within 30 days of a completed application that gives the specific principal reasons or tells the applicant how to request them. An LLM changes nothing: if you cannot say why the model pointed to a denial, you cannot send a compliant notice.
The reasons must name the actual factors in the file. Regulation B says a reason such as failing the lender's internal standards or policies is not enough (12 CFR 1002.9(b)(2)), so map the policy match to the underlying factors, and let the stage 6 signer see them before the notice goes out. This is information, not legal advice.
Does a lender still need fair lending testing after the 2026 Regulation B changes?
Yes. The CFPB's final rule, effective 21 July 2026, says ECOA does not authorize disparate impact liability, but disparate treatment is still prohibited and other federal and state disparate impact laws still apply.
The rule was published on 22 April 2026 (91 FR 21620), and the CFPB notes there that it does not administer those other laws; mortgage lenders still answer to the Fair Housing Act. Keep the pre-release sweep and the quarterly report.
Should I use Ocrolus or build my own document intake LLM?
Use Ocrolus or a similar vendor for stage 1 unless your annual document volume exceeds roughly 250,000 pages. Below that threshold, vendor unit economics beat in-house engineering.
Above it, custom builds with open foundation models start to pay off, particularly when paired with proprietary document types like internal worksheets or non-standard borrower attestations. Most mid-market lenders should buy intake and build the stage 3 to 5 reasoning layer.
The reasoning layer is where your underwriting IP lives. That is the build that compounds.
Is it safe to send borrower data to OpenAI, Claude or Gemini models?
It can be, under a business contract with no training on your data, a region and retention you chose, encryption and access logging. Safety comes from those controls, and the lender stays responsible for the vendor either way.
Non-bank lenders such as mortgage lenders and finance companies fall under the FTC Safeguards Rule, which requires service provider oversight under 16 CFR 314.4(f) (86 FR 70272) and, since 13 May 2024, notice to the FTC within 30 days of discovering that unencrypted customer information of at least 500 consumers was acquired without authorization (88 FR 77499).
Which stage of loan processing should a lender automate first?
Stage 1, document intake. It carries the largest time saving, has the lowest consequence of error, and builds the labeled data every later stage needs. Start there, measure accuracy against your own files, then move to the underwriter summary.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
Can LLMs fully replace human underwriters in 2026?
How accurate are LLMs at extracting data from W-2s and bank statements?
What is the cost to build a custom LLM layer for loan processing?
How do regulators view LLMs in loan decisioning?
What does Regulation B require when an LLM helps deny a loan?
Does a lender still need fair lending testing after the 2026 Regulation B changes?
Should I use Ocrolus or build my own document intake LLM?
Is it safe to send borrower data to OpenAI, Claude or Gemini models?
Which stage of loan processing should a lender automate first?
How LLMs Can Streamline Operations and Free Up Resources Through Automated Financial Document Processing
AI for Tax Season: What Accounting Firms Can Automate Before the Next Deadline
Streamline Your Startup with Business Automation: How Python Can Help You Automate and Optimize Your Business Processes
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.