
Chain-of-Thought Prompting: Techniques and Examples (2026)
Chain-of-thought prompting in 2026: five techniques with paper results, what OpenAI, Anthropic and Google advise for reasoning models, and CoT in agents.
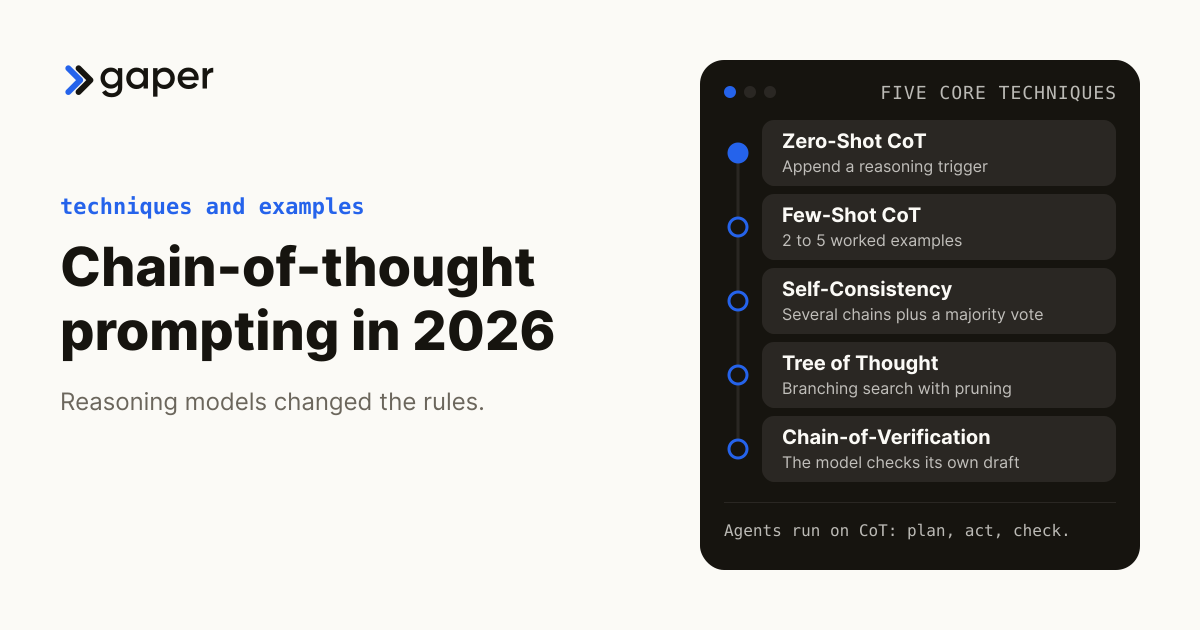
Chain-of-thought prompting asks a language model to work through intermediate steps before it answers; in the 2022 papers it more than tripled one model's grade-school math score. In November 2026 the flagship models from OpenAI, Anthropic and Google reason on their own, so you set the goal, the effort level and the checks instead of scripting the steps. The five classic techniques still matter for open-weight models and for agents that plan, act and verify.
TL;DR: Chain-of-Thought Prompting in 2026
- Chain-of-thought (CoT) prompting asks an LLM to show intermediate reasoning steps. In the original papers it lifted PaLM 540B from 17.9% to 56.9% on GSM8K math problems.
- Five core techniques exist: Zero-Shot CoT, Few-Shot CoT, Self-Consistency, Tree of Thought, and Chain-of-Verification. Each fits different use cases.
- Reasoning models changed the rules. GPT-6 Astra, Claude Opus 5.5 and Gemini 4 Argon think by default, their vendors call scripted steps unnecessary, and the hidden reasoning is billed as output.
- Scaling CoT in production requires prompt management systems, evaluation frameworks, fallback logic, and cost optimization. This is engineering work, not prompt tweaking.
- Agents run on CoT: plan, act, check. Log and evaluate that reasoning rather than trust it.
Table of Contents
- What Is Chain-of-Thought Prompting?
- How Chain-of-Thought Prompting Works
- 5 CoT Techniques Every AI Engineer Should Know
- Real-World Applications of CoT Prompting
- CoT Prompting With Different AI Models
- Common Mistakes With CoT Prompting
- Building CoT Into Your Product
- Chain-of-Thought in Agents: Plan, Act, Check
- How do you write an AI agent system prompt?
- Chain-of-Thought Questions, Answered
What Is Chain-of-Thought Prompting?
Chain-of-thought prompting is a technique that instructs large language models (LLMs) to break down complex problems into intermediate reasoning steps before producing a final answer. Instead of jumping straight to a conclusion, the model works through the problem and shows each stage.
The concept was formalized by Jason Wei and colleagues at Google Brain in their 2022 paper. With eight worked examples that spelled out their reasoning, PaLM 540B went from 17.9% to 56.9% on GSM8K, a benchmark of grade-school math word problems. A few months later, Kojima et al. (2022) showed that simply adding "Let's think step by step" lifted text-davinci-002 from 17.7% to 78.7% on the MultiArith benchmark, and from 10.4% to 40.7% on GSM8K. Those findings reshaped how the entire AI industry approaches prompt design.
By 2026, chain-of-thought is built into the models themselves: OpenAI's GPT-6 and GPT-5.x reasoning models, Claude's adaptive thinking and Gemini's thinking levels all reason before the visible answer. Knowing when to prompt for it and when to leave it to the model gives AI engineers direct control over accuracy and consistency.
The reason CoT works is grounded in how transformer architectures process information. LLMs generate tokens sequentially, and each token generation is essentially one "step" of computation. When a model produces a direct answer, it must compress all the reasoning into a single forward pass. When you instruct it to show intermediate steps, each generated reasoning token provides additional context for the next token, allowing the model to perform multi-step computation that would be impossible in a single pass.
This matters for any task requiring logical deduction, mathematical calculation, causal reasoning, or multi-constraint satisfaction.
Chain-of-thought prompting lifted PaLM 540B from 17.9% to 56.9% on GSM8K math reasoning in the original Google Brain study.
Source: Wei et al., "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models," 2022
How Chain-of-Thought Prompting Works
The core mechanic is straightforward: you modify your prompt to explicitly request reasoning steps. The implementation details decide whether CoT improves your output or just wastes tokens, so here are concrete before-and-after examples.
Standard Prompt vs CoT Prompt
Consider a common product scenario: determining whether a customer support ticket should be escalated to a human agent. Here is how a standard prompt compares to a CoT prompt for the same task.
Standard Prompt (No CoT):
Given this customer message, classify it as "escalate" or "auto-resolve":

"I've been charged twice for my subscription and I want a refund
immediately or I'm filing a chargeback with my bank."

Classification:
CoT Prompt:
Given this customer message, analyze it step by step before classifying:

"I've been charged twice for my subscription and I want a refund
immediately or I'm filing a chargeback with my bank."

Step 1: Identify the core issue.
Step 2: Assess the urgency and emotional tone.
Step 3: Check for financial or legal implications.
Step 4: Determine if automation can resolve this.
Step 5: Provide classification with confidence level.

Analysis:
The standard prompt often produces a bare classification with no reasoning trail. The CoT version forces the model to evaluate urgency (chargeback threat), financial risk (duplicate charge), and resolution complexity (requires billing system access) before deciding. On a 2026 reasoning model, keep those decision criteria but drop the numbered steps, and let the model plan its own path.
Zero-Shot CoT: The Simplest Approach
Zero-shot CoT requires no examples. You simply append a reasoning trigger to your prompt. The most famous trigger is "Let's think step by step," but several variants work well depending on the task type.
# Zero-Shot CoT triggers that work well in production:

"Let's think step by step."                    # General reasoning
"Let's work through this systematically."      # Multi-constraint problems
"Before answering, analyze each component."    # Decomposition tasks
"Show your reasoning, then give the answer."   # Math/logic problems
"Think about this carefully before responding." # Ambiguous inputs
Zero-shot CoT is the lowest-effort, highest-ROI technique for models that do not reason on their own. On a reasoning model, skip the trigger: all three major vendors call scripted reasoning unnecessary, and OpenAI warns it can sometimes hinder performance.
Few-Shot CoT: Teaching by Example
Few-shot CoT provides the model with 2-5 examples that include both the problem and the step-by-step reasoning that leads to the answer. This approach shows the model exactly what kind of reasoning you expect and in what format.
Example 1:
Q: A server processes 150 requests/sec. After optimization,
   throughput increases 40%. What's the new rate?
A: Let me work through this.
   - Original rate: 150 requests/sec
   - Increase: 40% of 150 = 60 requests/sec
   - New rate: 150 + 60 = 210 requests/sec
   Answer: 210 requests/sec

Example 2:
Q: A database query takes 2.4 seconds. After adding an index,
   latency drops by 75%. New latency?
A: Let me work through this.
   - Original latency: 2.4 seconds
   - Reduction: 75% of 2.4 = 1.8 seconds
   - New latency: 2.4 - 1.8 = 0.6 seconds
   Answer: 0.6 seconds

Now answer this question using the same step-by-step approach:
Q: An API endpoint handles 3,200 concurrent users. After
   horizontal scaling to 4 nodes, capacity scales linearly.
   Total capacity?
Few-shot CoT consistently outperforms zero-shot when the reasoning pattern is domain-specific, at a higher token cost (your examples are included in every API call). In Kojima et al.'s comparison on text-davinci-002, eight worked examples beat the zero-shot trigger by 14.3 points on MultiArith (93.0% against 78.7%) and 8.0 on GSM8K. Anthropic says examples still shape how Claude approaches similar problems in its own thinking.
5 Chain-of-Thought Techniques Every AI Engineer Should Know
Chain-of-thought prompting has evolved well beyond a single trick into several distinct techniques, each suited to different problems and accuracy needs.

1. Zero-Shot Chain-of-Thought
Zero-shot CoT is the simplest and most widely used technique. You add a reasoning trigger phrase to your prompt without providing any examples. The model generates its own reasoning chain based solely on its training data and the instruction to think step by step.
Kojima et al. (2022) tested 16 trigger templates on MultiArith and found "Let's think step by step" scored best, at 78.7%, against 17.7% with no trigger. In production, test domain-tailored triggers too: "Let's trace through the execution step by step" for debugging, or "Let's evaluate each factor systematically" for financial analysis.
When to use it: Quick improvement without crafting examples, on a model that does not reason natively. General-purpose reasoning, initial prototyping, or tasks where the reasoning pattern is intuitive.
Limitations: The model may choose a suboptimal reasoning path because it has no example to follow. On highly specialized domains, the generic reasoning chain may miss critical steps. Token cost increase is modest (typically 1.5-2x).
2. Few-Shot Chain-of-Thought
Few-shot CoT includes 2-5 demonstration examples in your prompt, each showing the complete problem, reasoning chain, and final answer (Wei et al. used eight for GSM8K). This technique gives the model a concrete template for how to structure its thinking.
The quality of your examples matters enormously. Diverse examples (covering different subtypes of a problem) tend to outperform repetitive ones, and the model will mimic both the format and the quality of the reasoning you demonstrate.
When to use it: Domain-specific tasks where the reasoning path is non-obvious. Legal analysis, medical diagnosis, financial modeling, or any field where expert reasoning follows specific protocols. Also valuable when you need consistent output formatting across thousands of API calls.
Limitations: Higher token cost per call (examples add 500-2,000 tokens). Requires upfront effort to craft high-quality examples. May overfit to the example patterns if your examples are not diverse enough.
3. Self-Consistency Chain-of-Thought
Self-consistency CoT generates multiple independent reasoning chains for the same problem (the original paper sampled 40), then selects the most common answer through majority voting. Correct reasoning paths tend to converge on the same answer, while errors scatter.
Introduced by Wang et al. (2022), self-consistency beat single-chain CoT across the arithmetic and commonsense benchmarks the paper tested. On GSM8K it lifted PaLM 540B from 56.5% to 74.4% and code-davinci-002 from 60.1% to 78.0%.
When to use it: High-stakes decisions where accuracy justifies the compute cost. Medical diagnosis support, legal contract analysis, financial compliance checks.
Limitations: Cost scales linearly with the number of paths (5x-20x a single CoT call at 5 to 20 paths). Latency increases unless you run paths in parallel. Majority voting can fail if the problem has a systematic bias. Google now ignores temperature on Gemini 3.6 Flash and later, so you cannot raise it to vary the chains.
4. Tree of Thought (ToT)
Tree of Thought extends CoT from a single linear chain to a branching tree structure. At each reasoning step, the model generates multiple possible continuations, evaluates which branches are most promising, and prunes unpromising paths before continuing. This approach mimics how expert problem-solvers explore a solution space with deliberate backtracking.
Proposed by Yao et al. (2023), ToT excels at problems requiring search and planning. The paper tested Game of 24, creative writing and mini crosswords; in Game of 24, GPT-4 with chain-of-thought solved 4% of tasks and Tree of Thoughts solved 74%.
When to use it: Complex planning tasks with multiple viable paths. System architecture design, resource allocation, multi-step code refactoring.
Limitations: Highest compute cost of all techniques (roughly 10x-50x a single prompt). Requires orchestration logic outside the model to manage tree traversal, and latency grows with tree depth. Not justified for tasks with straightforward reasoning paths.
5. Chain-of-Verification (CoVe)
Chain-of-Verification adds a self-correction layer after the initial CoT reasoning. The model drafts an answer, generates verification questions about its own output, answers those questions independently, and revises the original answer based on any inconsistencies found.
Introduced by Dhuliawala et al. (2023) at Meta AI, CoVe targets hallucination. In the paper it more than doubled precision on Wikidata list questions with Llama 65B (0.17 to 0.36), cutting hallucinated answers per question from 2.95 to 0.68, and raised the FactScore of long-form biographies from 55.9 to 71.4.
When to use it: Applications where factual accuracy is critical and hallucinations carry real consequences. Healthcare information systems, legal research tools, customer-facing chatbots that reference product specifications or policies.
Limitations: Adds 2-3x tokens on top of the initial CoT cost. The model may verify its answers using the same flawed knowledge that produced the original error. Works best when combined with RAG (retrieval-augmented generation) so verification can reference authoritative sources.
Real-World Applications of CoT Prompting
CoT has moved far beyond academic benchmarks into six areas where its gains are measurable on your own data.
Mathematical Reasoning
Mathematical reasoning was the original proving ground for CoT, and verification matters as much as the chain. OpenAI's 2023 study "Let's Verify Step by Step" found that a verifier trained on feedback for every step beat one trained only on final answers; with it, the model solved 78% of a representative subset of the MATH test set.
In production, mathematical CoT works best when combined with structured output parsing. You instruct the model to show each calculation step in a consistent format, then programmatically verify intermediate results. If step 3 contradicts step 2, your system catches the error before presenting the final answer to the user. Google's prompting guide also says to enable code execution whenever the model needs to calculate.
Code Generation and Debugging
Code generation benefits enormously from CoT because programming is inherently sequential and logical. When you ask an LLM to generate a complex function without CoT, it often produces code that handles the happy path but misses edge cases, error handling, or performance considerations. With CoT, the model first outlines its approach, identifies potential edge cases, plans error handling, then generates code that addresses each identified concern.
Debugging benefits even more. A CoT debugging prompt instructs the model to: read the error message, identify the failing line, trace the variable state at that point, hypothesize root causes, propose a fix, and verify the fix does not introduce regressions. This structured approach mirrors how senior engineers debug and consistently outperforms "fix this error" prompts.
Medical Diagnosis Support
Healthcare AI systems use CoT to walk through differential diagnosis processes. A standard prompt might ask "What condition does this patient likely have?" CoT restructures this as: "Given these symptoms, lab results, and patient history, systematically consider the most likely diagnoses. For each candidate, evaluate which symptoms it explains and which it does not. Rank the candidates by probability and identify what additional tests would distinguish between the top candidates."
Google's Med-PaLM 2, which paired chain-of-thought with an ensemble refinement step, scored up to 86.5% on the MedQA exam benchmark in 2023, over 19 points above the first Med-PaLM. An exam is not a clinic, so that is not a diagnostic accuracy rate. The reasoning chain also provides transparency that is critical for clinical adoption, allowing physicians to verify the AI's logic rather than blindly accepting a suggestion.
Legal Document Analysis
Legal analysis requires identifying relevant clauses, understanding their implications in context, checking for conflicts between clauses, and assessing compliance with applicable regulations. Standard prompting frequently misses these interdependencies. CoT prompting structures the analysis as: identify all relevant sections, extract key obligations and conditions from each, cross-reference for conflicts, compare against the relevant regulatory framework, and summarize findings with specific clause references.
The explicit reasoning chain can serve as a first draft of the analysis memo that associates would otherwise write from scratch; measure the time saved on your own matters.
Financial Modeling and Forecasting
Financial models involve multi-step calculations with interdependent variables, making them ideal CoT candidates. A revenue forecasting prompt with CoT might instruct: "Analyze historical growth rate, identify seasonal patterns, account for market conditions, apply the appropriate forecasting model, calculate confidence intervals, and flag assumptions that carry the highest uncertainty." Each step produces intermediate values that the next step depends on, and the full chain is auditable.
The reasoning chain also lets portfolio managers and CFOs judge a forecast's assumptions rather than treat the output as a black box.
Customer Support Escalation Logic
Intelligent customer support routing uses CoT to evaluate ticket complexity, customer sentiment, financial exposure, and resolution requirements before deciding whether to auto-resolve, escalate to tier 2, or route to a specialized team. Without CoT, classification models often rely on keyword matching and miss nuanced signals like implied legal threats, multi-issue tickets, or VIP customer patterns.
Score routing accuracy on a labeled set of past tickets before and after adding CoT. The reasoning chain also feeds into quality assurance workflows, allowing support managers to audit why specific tickets were routed where they were.
Building AI Products?
Book a Free AI Assessment for Your CoT Pipeline
14 verified Clutch reviews | Harvard & Stanford Alumni
CoT Prompting With Different AI Models
Not all models respond to chain-of-thought prompting equally. The 2026 split is between reasoning models, which think before they answer, and models that reason only when prompted. As of November 2026:
| Model | CoT Support | Best Technique | Context Window | Notes |
|---|---|---|---|---|
| GPT-6 Astra (OpenAI) | Native reasoning | Clear goal plus reasoning effort | 1.05M | OpenAI's recommended starting model |
| Claude Opus 5.5 (Anthropic) | Native, adaptive thinking always on | Effort setting plus a self-check | 1M | Default effort medium |
| Gemini 4 Argon (Google) | Native, dynamic thinking | thinking_level | 1M | Google's flagship; default level medium |
| Llama 4 Scout / Maverick (Meta) | Prompt-based | Few-Shot CoT | Up to 10M (Scout) | Open weight, not a reasoning model; fine-tunable |
| Mistral Large 4 | Native, reasoning_effort low / medium / high | reasoning_effort | 1M | Open-weight MoE, GA 6 Oct 2026 |
| gpt-oss-20b (OpenAI) | Native, effort low / medium / high | Built-in reasoning | 128K | Open weight, runs in 16 GB of memory |
The best model for your CoT pipeline depends on your accuracy requirements, latency budget, and cost constraints. The hosted flagships deliver the highest accuracy at premium pricing; open-weight models suit teams that can self-host and want to fine-tune CoT behavior for their domain.
Models with native reasoning have internalized CoT. For them, explicit CoT prompting is usually redundant and can be counterproductive, adding tokens without improving accuracy. Test both approaches for your task before committing.
For smaller models, prompt-based CoT shows little benefit and can degrade performance. Wei et al. found CoT only helped at around 100B parameters, with smaller models producing "fluent but illogical chains of thought." The 2026 exception is small models trained to reason, such as gpt-oss-20b (3.6B active parameters). Otherwise, fine-tune on task-specific reasoning traces rather than relying on prompt-based CoT.
How OpenAI, Anthropic and Google Run Reasoning in 2026
Each vendor has an effort dial and hides the raw reasoning (checked at vendor docs, 8 November 2026):
- OpenAI. In the reasoning guide,
reasoning.effortruns fromnonetomaxdepending on the model; GPT-6 Astra rejectsnone, and GPT-5.5 defaults tomedium. GPT-5.6 and GPT-6 models add apromode. Raw reasoning is never exposed, only an opt-in summary, and OpenAI suggests reserving at least 25,000 tokens for reasoning and output at first. - Anthropic. With adaptive thinking, Claude decides per request whether and how much to think, steered mainly by
effort(low to max); on Fable 5.1 and Opus 5.5 thinking is always on. The fixedbudget_tokensmode of extended thinking is deprecated and rejected from Claude 4.7. Thinking blocks hold a summary, never the raw chain, omitted on Claude 5 models unless you opt in. - Google. Gemini thinks dynamically by default under
thinking_level; Gemini 4 Argon offers low, medium (default) and high.thinking_levelreplaces the olderthinking_budget, and thought summaries are off unless enabled.
What the Vendors' Prompting Guides Say About Step-by-Step Instructions
- OpenAI. The reasoning best practices say to "avoid chain-of-thought prompts," since "think step by step" "can sometimes hinder" performance. The newer guide wants a goal, constraints and output format "without prescribing every intermediate step," and for agents, a definition of done and how to verify it.
- Anthropic. The Claude prompting guide says to "prefer general instructions over prescriptive steps"; "think thoroughly" often beats a hand-written plan. Manual CoT is a fallback for when thinking is off. It recommends a self-check against your test criteria, except on Claude Opus 5.
- Google. The Gemini prompting strategies call it "generally not necessary" to have the model outline its reasoning steps, though "Think very hard before answering" can help. Google's Gemini 3 template still lists Plan, Execute, Validate and Format: structure the job, not the thoughts.
The classic techniques still drive models that do not reason natively, and self-consistency, Tree of Thought and Chain-of-Verification run in your orchestration code, whatever the model.
Common Mistakes With CoT Prompting
CoT is not a magic bullet. Misapplied, it wastes tokens, increases latency, and can even reduce accuracy. These are the five most common production mistakes, plus a sixth that arrived with reasoning models.
1. Over-Prompting: Forcing Too Many Steps
The most common mistake is prescribing an excessive number of reasoning steps. If your prompt specifies 10 mandatory steps for a problem that naturally requires 3, the model will pad the extra steps with redundant or fabricated reasoning. This padding consumes tokens and can introduce errors when the model justifies unnecessary conclusions.
Fix: Start with zero-shot CoT and observe how many steps the model naturally takes. Use that as your baseline, then add 1-2 additional steps only if you identify specific reasoning gaps.
2. Not Validating Intermediate Reasoning
Many teams use CoT to generate reasoning chains but only evaluate the final answer. If step 2 in a 5-step chain is wrong, every later step builds on a faulty foundation, and the final answer may look plausible while being entirely wrong.
Fix: Build evaluation frameworks that score intermediate steps, not just final outputs. For mathematical tasks, verify each calculation programmatically. For logical reasoning, check that each step follows from the previous one. Chain-of-Verification (CoVe) automates part of this process. On reasoning models, score the visible summaries and tool calls.
3. Ignoring Token Cost at Scale
CoT prompting increases output tokens by 2-3x for standard techniques and 5-50x for self-consistency and tree-of-thought approaches. At prototype scale (hundreds of calls per day), this is manageable. At production scale (millions of calls per day), the cost difference between standard prompting and self-consistency CoT can be six figures per month. Reasoning models add hidden thinking tokens to the same bill.
Fix: Implement a tiered approach. Use zero-shot CoT as the default, escalate to few-shot CoT for higher-complexity inputs (detected via a lightweight classifier), and reserve self-consistency for the highest-stakes decisions. On reasoning models, tier the effort setting the same way.
4. Using CoT When Simple Prompts Suffice
CoT adds value for tasks requiring multi-step reasoning: math, logic, causal analysis, multi-constraint decisions. It adds no value for tasks that are fundamentally about pattern matching, information retrieval, or text transformation. Sentiment classification, named entity recognition, text summarization, and simple Q&A do not benefit from CoT and may actually perform worse because the forced reasoning introduces unnecessary complexity.
Fix: Benchmark both approaches on your specific task. If standard prompting achieves 95%+ accuracy, adding CoT is likely waste. Reserve CoT for the tasks where it closes a meaningful accuracy gap.
5. Not Combining CoT With Retrieval (RAG + CoT)
CoT tells the model how to think. RAG (retrieval-augmented generation) gives the model what to think about. CoT without RAG reasons over stale or incomplete training data; RAG without CoT has the right information but may not process it correctly. The combination is where production systems see the biggest accuracy gains.
Fix: Architect your pipeline as: retrieve relevant documents, inject them into the prompt context, then apply CoT instructions to reason over the retrieved information. Our RAG vs fine-tuning guide covers when retrieval beats training on your data.
6. Scripting the Steps for a Reasoning Model
Prompts written for 2023 models carry numbered steps and "think step by step" triggers. On a reasoning model they duplicate its own reasoning and add tokens.
Fix: Strip the step lists, keep the decision criteria and output format, define a finished answer, and rerun your evaluation set at two or three effort levels.
Building CoT Into Your Product
Using chain-of-thought prompting in a personal ChatGPT conversation is easy. Deploying CoT in a production system that serves thousands or millions of users is an entirely different engineering challenge.
The gap between "CoT works in my notebook" and "CoT works in production" includes:
- Prompt management systems: Version-controlled prompt templates with A/B testing, rollback capabilities, and environment-specific configurations. Your CoT prompts need the same CI/CD rigor as your application code.
- Cost optimization: Dynamic technique selection based on query complexity. Simple queries get zero-shot CoT, complex queries get few-shot, critical queries get self-consistency. On reasoning models, the same routing sets the effort level. Building this classifier is itself an engineering task.
- Evaluation frameworks: Automated scoring of both intermediate reasoning steps and final outputs. Ground truth datasets, regression test suites, and continuous monitoring for accuracy drift as models are updated.
- Fallback logic: What happens when the CoT chain produces contradictory intermediate steps? When the model hits a token limit mid-reasoning? When latency exceeds your SLA threshold? Production systems need graceful degradation paths for every failure mode.
- Observability: Logging, tracing, and dashboarding for every reasoning chain. You need to know which prompt versions are producing which accuracy levels, which input patterns cause failures, and how costs trend over time.
This is why companies building AI products hire dedicated AI engineers rather than relying on prompt tweaking by generalists. The prompt itself is 10% of the work. The other 90% is the infrastructure, evaluation, and operations that make it reliable at scale.
How Gaper Can Help
Our AI engineers have deployed chain-of-thought pipelines across healthcare scheduling (with Kelly), accounting automation (with AccountsGPT), HR recruiting workflows (with James), and marketing operations (with Stefan). They have hands-on experience with every major LLM, every CoT technique covered in this article, and the production infrastructure to make it scale.
Whether you need a single AI engineer to build a CoT evaluation framework or a full team to ship a reasoning-powered product feature, Gaper matches you with the right talent.
Gaper is the AI-native implementation partner that deploys supervised AI agents you own.
Free assessment. No commitment. Cancel anytime.
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Chain-of-Thought in Agents: Plan, Act, Check
An AI agent is chain-of-thought stretched across tool calls: it reasons, calls a tool, reads the result, and reasons again until the job is done (Anthropic calls this interleaved thinking). The practical pattern has three parts.
Plan: Make the Plan an Output You Can Inspect
Hidden reasoning is not a plan you can review. Have the agent return a short written plan (steps, tools, final checks) and store it with the run, so a reviewer can approve it before anything changes.
Act: One Step at a Time, With Tool Contracts
The agent makes one tool call at a time and reads each result before the next; that is where it notices an empty lookup or a mismatched record. Reads run freely; anything that writes, sends, pays or deletes sits behind a precondition or a confirmation step.
Check: Verify Against Something Outside the Model
Before reporting success, the agent tests its result against criteria you defined: run the tests, validate the schema, re-query the source system. Prefer programmatic checks to self-grading, and define "done" in the prompt. When a check fails, it retries within a limit or hands off; our guide to human-in-the-loop AI covers where those approval gates belong.
Log and Evaluate the Reasoning, Do Not Trust It
A model's written reasoning is evidence, not an audit trail. In an April 2025 Anthropic study, reasoning models given a hint that shaped their answer mentioned it only about 25% of the time (Claude 3.7 Sonnet) and 39% (DeepSeek R1). Log inputs, plans, summaries, tool calls and checks, score outcomes on a fixed set of real cases, and rerun it whenever the prompt, model or effort changes. See AI agent observability.
How do you write an AI agent system prompt?
Write it as an operating spec, not a personality. State the job and its boundary, give every tool a contract that covers failure, list the few hard rules, show boundary-case examples, then version and test it against real transcripts like any other code.
The system prompt is the contract between you and your agent. Demos run on the happy path; production brings ambiguous requests, tool errors and adversarial users, and an agent whose prompt never covered those edges improvises, often confidently and wrong.
Start With the Job, Not the Personality
"You are a friendly, helpful assistant" tells the model almost nothing actionable. State the role, the workflow and the single outcome it owns. Weak: "You help customers with their questions." Strong: "You are a tier-1 support agent for an e-commerce returns desk. You handle order status, return eligibility, and refund timelines for orders placed in the last 90 days. You do not handle chargebacks, fraud claims, or anything involving a payment dispute, those route to a human." Define the boundary before the behavior, because most incidents come from the agent confidently acting outside its lane.
Be Explicit About Tools and Their Contracts
Models do not infer tool semantics from names: get_user could mean the current user, a looked-up user, or a search. The schema defines the mechanical contract; the system prompt adds the judgment the schema can't express, and the two must agree. For every tool, cover:
- Trigger conditions, stated as rules, not hints.
- Preconditions, for example "never issue a refund without an order ID you have verified."
- Failure handling for errors, timeouts and empty results: "say you don't know" beats inventing a result.
- Mutating versus read-only, so every tool that changes state gets a confirmation step.
Encode the Hard Rules as Constraints, Not Suggestions
Guidance ("prefer concise answers") is not a constraint ("never reveal another customer's order details"). Put the non-negotiables in their own section as absolute rules, such as always escalating when a user mentions legal action, a security issue, or self-harm. Keep the list short, because forty rules dilute the five that matter; most production prompts run from a few hundred to a couple thousand tokens. The highest-leverage rule: if you are not confident you can complete this correctly, hand off to a human with a summary.
Show, Don't Just Tell, With Examples
Include worked examples for the boundaries: the happy path, one ambiguous request, one out-of-scope request to refuse, and one where a tool fails. When a mistake traces to a gap in judgment, the fix is often a new example, not a new paragraph.
Treat the Prompt as Production Code
Keep the prompt in source control with a changelog, and run an evaluation set of real transcripts and known failures every time you change a word. Getting that loop running inside a company's real stack is most of the work, and it's exactly the kind of thing an AI agent development company does when it takes an agent from a notebook to running in production. Pin the model and prompt together, and watch escalation rates: never handing off means loose constraints, constant hand-offs mean tight ones.
Where Chain-of-Thought Belongs in the System Prompt
On a reasoning model, do not narrate how to think. Say when to plan, what to verify before reporting success and what "done" means, then set the effort in the API call. On a non-reasoning model, one instruction to reason before calling a tool, plus an example, still earns its tokens.
What does chain-of-thought prompting mean for reasoning models?
It still means breaking a problem into intermediate steps before answering, but reasoning models now do that internally. Your prompt's job shifts from scripting the steps to stating the goal, the constraints, the effort level and how the answer will be checked.
Chain-of-thought works because each reasoning token adds context for the next, enabling multi-step computation impossible in a single forward pass.
What are the five chain-of-thought techniques every AI engineer should know?
Zero-Shot CoT (add a trigger like "Let's think step by step"), Few-Shot CoT (2 to 5 worked examples), Self-Consistency (several chains plus a majority vote), Tree of Thought (branching search with pruning), and Chain-of-Verification (the model checks its own draft).
Paper results, costs and limits are in the techniques section.
Does chain-of-thought prompting work with all AI models?
It helps large models most. Reasoning models such as GPT-6 Astra, Claude Opus 5.5 and Gemini 4 Argon already think internally, so a step-by-step instruction is usually redundant. Small models not trained to reason often write fluent but illogical chains.
Small models trained to reason, like gpt-oss-20b, are the exception. For open-weight models that do not reason natively, such as Llama 4, prompt-based CoT still matters.
How much does chain-of-thought prompting increase accuracy?
On GSM8K math problems the papers report jumps from 17.9% to 56.9% (PaLM 540B with eight worked examples), 10.4% to 40.7% (a zero-shot trigger on text-davinci-002) and 56.5% to 74.4% with self-consistency (PaLM 540B). Simple tasks see little benefit.
Those figures come from 2022 models; on current reasoning models manual CoT adds little. On non-reasoning models CoT usually helps code generation, debugging and logic, and does little for sentiment classification or summarization. The number that matters for your product is the one from your own evaluation set.
Is chain-of-thought prompting the same as prompt engineering?
No. Prompt engineering is the broad discipline of designing inputs to get reliable outputs from language models. Chain-of-thought is one technique within it, alongside role prompting, few-shot examples, output format rules, prompt chaining and retrieval-augmented generation (RAG).
Prompt chaining splits a complex job across prompts that pass results along. A production prompt typically combines techniques: role prompting to set context, RAG to inject relevant data, CoT to structure reasoning, and output format specification for machine-parseable results. Two habits separate practice from guesswork: validate every output rather than accepting it, and learn each model's strengths and limits.
Does chain-of-thought prompting cost more tokens?
Yes. Reasoning steps are output tokens, and reasoning models bill their hidden thinking as output too. As rough rules of thumb, zero-shot CoT costs 1.5 to 2x a plain prompt, few-shot 2 to 3x, self-consistency 5 to 20x and Tree of Thought 10 to 50x.
Few-shot costs more because examples add input tokens; self-consistency is arithmetic, since five chains cost about five times one. On reasoning models the main cost control is the effort setting. Use the cheapest variant or effort level that meets your accuracy threshold, and reserve expensive techniques for the highest-stakes decisions.
Can I use chain-of-thought prompting for code generation?
Yes. Ask the model to restate the requirements, plan the approach, list edge cases and error conditions, write the code, then check it against tests. On a reasoning model, give it the requirements and the tests and let it plan, then run the tests yourself.
This mirrors how experienced software engineers work. For testing, prompt the model to think like an adversarial user and list the inputs most likely to break the code, then make them test cases. Measure the effect on your own codebase rather than trusting a published average.
How do I implement chain-of-thought prompting at scale?
Version prompts like code, route each request to the cheapest technique or effort level that meets your accuracy bar, score reasoning and answers on an evaluation set, add fallbacks for contradictions, timeouts and token limits, and log every chain.
That is the five building blocks from Building CoT Into Your Product, plus the agent habits above: an inspectable plan, programmatic checks, and an evaluation set you rerun on every change.
Ready to Build?
Ship CoT-Powered AI Products Faster
Stop experimenting in notebooks. Start deploying in production.
14 verified Clutch reviews | Harvard & Stanford Alumni | No commitment required
Thirty minutes, no commitment. We map one workflow, make the build or buy call, and scope the smallest thing worth shipping.
Frequently asked questions
What Is Chain-of-Thought Prompting?
How do you write an AI agent system prompt?
What does chain-of-thought prompting mean for reasoning models?
What are the five chain-of-thought techniques every AI engineer should know?
Does chain-of-thought prompting work with all AI models?
How much does chain-of-thought prompting increase accuracy?
Is chain-of-thought prompting the same as prompt engineering?
Does chain-of-thought prompting cost more tokens?
Can I use chain-of-thought prompting for code generation?
How do I implement chain-of-thought prompting at scale?
Ready to turn AI into execution?
Book a free assessment of one workflow. We map it, make an honest build versus buy call before any code, and if an off the shelf product covers the job we will tell you so.